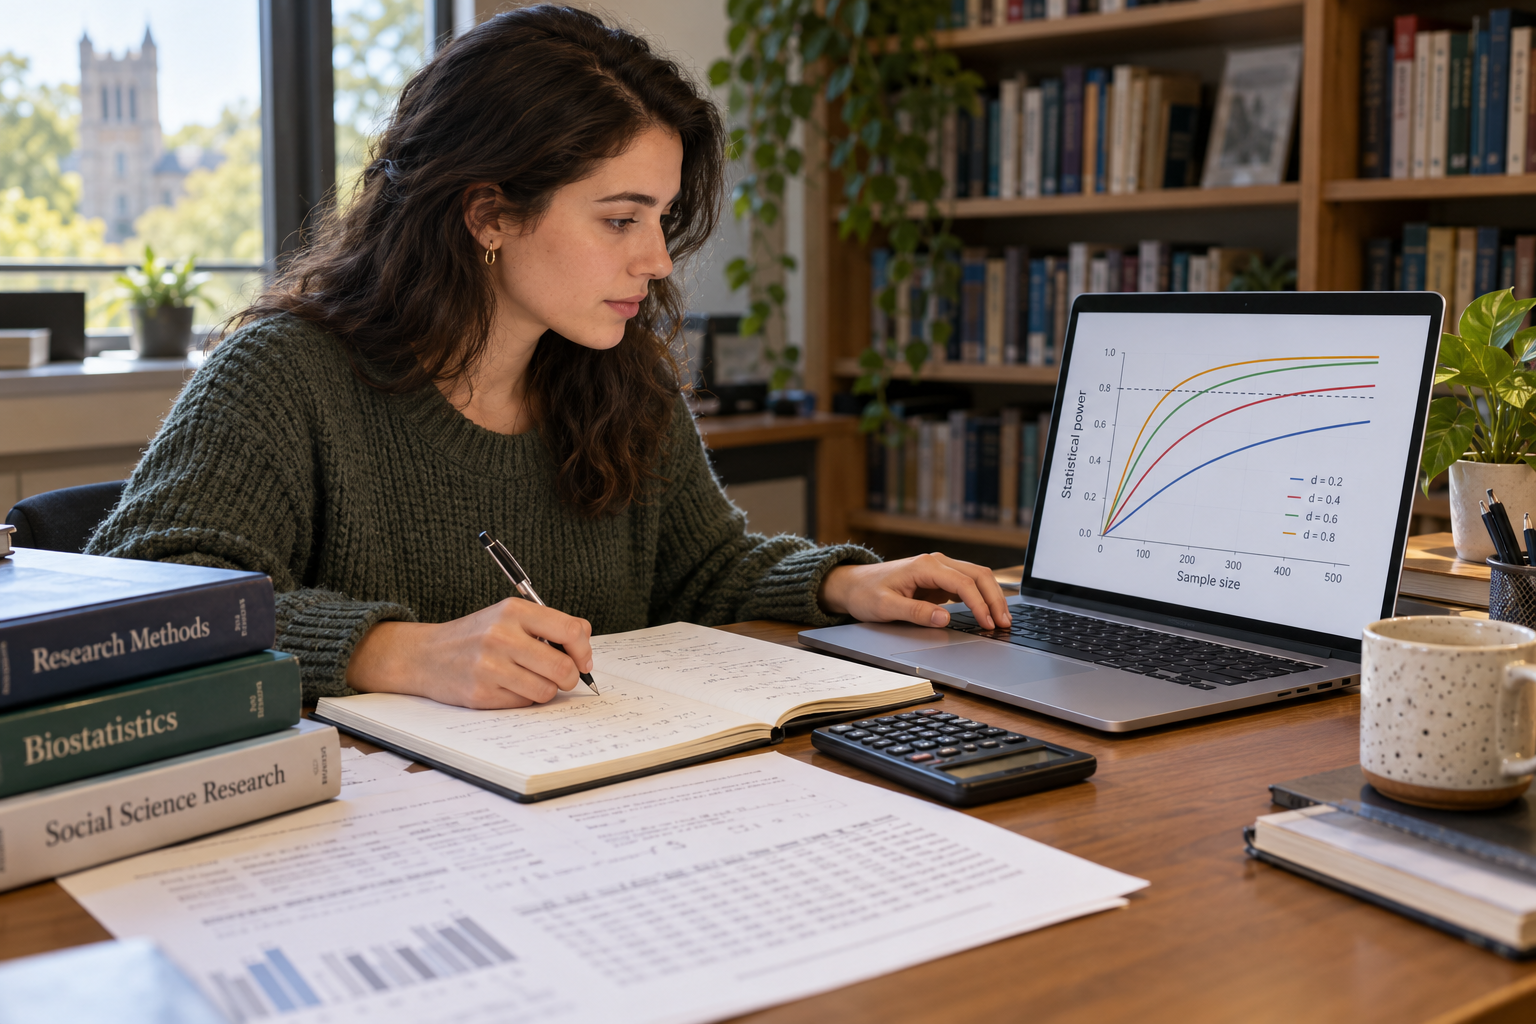
Sample size is one of the most important design decisions in quantitative dissertation research. A sample that is too small may provide insufficient statistical power to detect an effect that genuinely exists, while recruiting substantially more participants than necessary can consume time, money, and participant resources without a clear methodological benefit. For this reason, a dissertation should explain how its target sample was determined rather than presenting the final number as an arbitrary recruitment goal.
Sample size and power analysis are closely connected. Statistical power describes the probability that a statistical test will detect a specified effect when that effect exists under the assumptions used in the calculation. An a priori power analysis works in the opposite direction: the researcher specifies the planned statistical test, expected effect size, significance level, desired power, and other design parameters, and then calculates the sample required to achieve those conditions.
Students often struggle because there is no universal answer to questions such as "Is 100 participants enough for a dissertation?" The required sample depends on what the study is trying to detect and how the data will be analysed. This guide explains how to justify a dissertation sample systematically, including effect size, alpha, statistical power, test selection, G*Power, attrition, sampling strategy, feasibility, and the wording needed for a transparent methodology chapter.
Why Sample Size Justification Matters in a Dissertation
A sample size is not simply the number of questionnaires a researcher hopes to collect. In quantitative research, it influences the precision of estimates and the ability of inferential tests to distinguish meaningful effects from sampling variability. Consequently, readers need to understand why the selected sample was appropriate for the particular research questions and statistical analysis.
A strong justification also demonstrates that the sample was considered during research design rather than rationalised after data collection. Epic Essay's guide to writing a dissertation methodology chapter explains that methodology should justify research decisions rather than merely describe procedures. Sample size is one of those decisions because it affects what the planned analysis can reasonably detect.
Sample size also interacts with the sampling strategy. A study can contain hundreds of participants and still have limited generalisability if participants were selected through a strongly biased recruitment process. Conversely, a carefully selected probability sample can improve representativeness without eliminating the need to consider whether the number of observations is sufficient for the intended statistical analysis.
A defensible sample is not simply "large enough." It is a sample whose size, recruitment method, and analytical purpose can all be justified in relation to the research design.
What Is Statistical Power?
Statistical power is the probability of rejecting a false null hypothesis for a specified alternative effect under the assumptions of the analysis. It is conventionally represented as 1 - β, where β is the probability of a Type II error. A Type II error occurs when the analysis fails to reject the null hypothesis even though the specified effect is genuinely present.
A target power of .80 is frequently used in research planning, corresponding to an assumed 20% Type II error probability for the specified alternative. This is a convention rather than a universal law. Some research contexts use .90 or another value when missing an important effect would have greater consequences or disciplinary guidance requires a higher target.
The relationship between power and sample size is intuitive. Holding other planning parameters constant, a larger sample generally provides greater ability to detect a specified effect because estimates become more precise. However, sample size is only one component of power, so increasing participant numbers cannot compensate for every weakness in research design or measurement.
The UCLA Statistical Consulting guidance on power analysis emphasises that power analysis is not governed by one simple sample-size formula for every research situation. The appropriate calculation depends on the statistical model and the assumptions used to represent the proposed study.
What Determines the Required Sample Size?
Power calculations are built from several interacting quantities. For many common hypothesis tests, these include the significance level, desired statistical power, effect size, and features of the planned analysis such as the number of groups or predictors. If the researcher changes one component while holding the others constant, the required sample can change substantially.
For example, designing a study to detect a very small effect normally requires more observations than designing it to detect a large effect. Increasing desired power from .80 to .90 also generally increases the required sample. Using a more stringent significance criterion can similarly increase sample requirements.
The core components are summarised below.
| Component | Meaning | Effect on Sample Planning |
|---|---|---|
| Effect size | Magnitude of the effect the study is designed to detect | Smaller target effects generally require larger samples |
| Alpha | Pre-specified probability of a Type I error under the null hypothesis | More stringent alpha levels generally require larger samples |
| Statistical power | Probability of detecting the specified effect when it exists | Higher desired power generally requires a larger sample |
| Statistical test | Planned inferential procedure and model structure | Different tests require different calculations |
| Design structure | Groups, predictors, allocation ratios, repeated measurements, or other design features | Changes the relevant power model and sample requirement |
| Expected attrition | Participants expected to withdraw or provide unusable data | Usually increases the number that should initially be recruited |
The table explains why statements such as "a dissertation needs at least 100 respondents" are methodologically weak. One hundred observations could be more than adequate for one analysis and severely underpowered for another. The sample needs to be linked to the exact analytical problem.
How Effect Size Influences Sample Size
Effect size represents the magnitude of the difference, relationship, or model effect the study is designed to detect. Different statistical procedures use different effect-size metrics. Examples include Cohen's d for a standardised difference between two means, Pearson's r for correlation, and Cohen's f for certain ANOVA power calculations.
Smaller effects are harder to distinguish from sampling variability, so detecting them reliably generally requires larger samples. Larger effects create a stronger statistical signal and can therefore be detected with fewer observations under otherwise equivalent conditions. This relationship is one reason sample-size calculations should state the assumed effect size explicitly.
The effect-size assumption should ideally be supported by substantive evidence. Previous studies, meta-analyses, pilot data, established theory, or a scientifically meaningful minimum effect can provide a basis. Simply selecting "medium" because statistical software offers that option is less persuasive unless the convention is defensible for the research area.
Epic Essay's guide to sample size justification in research similarly emphasises that power analysis connects effect size, significance level, power, and sample size. A dissertation should make those assumptions visible so that readers can evaluate how the target sample was derived.
How Alpha and Type I Error Affect Sample Planning
The significance level, represented by α, defines the pre-specified threshold used to control the probability of a Type I error under the null hypothesis. A Type I error occurs when a true null hypothesis is rejected. An alpha level of .05 is common in many disciplines, although appropriate thresholds depend on the research context and analytical plan.
Making alpha more stringent generally increases the required sample when effect size and power are held constant. A study designed around α = .01 therefore often needs more observations than the same design using α = .05. The researcher is requiring stronger evidence before rejecting the null hypothesis, so more information may be needed to maintain the desired power.
The choice should be established before examining the study results. Changing alpha after seeing the p-value undermines the logic of pre-specified hypothesis testing. If the dissertation uses a conventional .05 threshold, this can be stated directly in the power-analysis assumptions.
Multiple primary comparisons can complicate the issue because procedures used to control multiplicity may alter the effective significance criterion. Where the planned research contains several primary hypotheses, sample-size planning should reflect the actual inferential strategy rather than pretending that only one isolated test will be performed.
Why 80% Power Is Common but Not Automatically Correct
A power target of .80 is widely used because it represents an established compromise between the probability of detecting a specified effect and the resources required to recruit participants. Under this target, β equals .20 for the effect assumed in the calculation. However, the convention should not be treated as proof that .80 is ideal for every dissertation.
Increasing desired power to .90 reduces the assumed Type II error probability to .10, but it normally increases the required sample. Whether that additional protection is justified depends on the research consequences, disciplinary expectations, feasibility, and importance of the effect being investigated.
The important point is to state the chosen value transparently. A methodology might explain that an a priori calculation used α = .05, desired power = .80, and an effect size supported by previous literature. This is more informative than stating only that "G*Power recommended 128 participants."
Power is always power to detect a specified effect under specified assumptions. Writing that a study simply "has 80% power" without identifying the effect and statistical test leaves the justification incomplete.
Why the Planned Statistical Test Changes the Required Sample
There is no single power calculation that applies to every dissertation. A two-group t-test, correlation, one-way ANOVA, chi-square analysis, and multiple regression ask different statistical questions and use different probability models. Consequently, the appropriate sample-size calculation must correspond to the primary planned analysis.
A correlation study might specify the smallest population correlation it seeks to detect. A two-group experiment may specify a standardised mean difference and allocation ratio. A one-way ANOVA may require the expected effect size, number of groups, alpha, and desired power, while regression planning can depend on the number of predictors and the particular effect being tested.
The distinction is illustrated below.
| Planned Analysis | Typical Planning Information | Example Research Question |
|---|---|---|
| Independent samples t-test | Effect size, alpha, power, group allocation | Do two teaching methods differ in mean examination score? |
| Correlation | Target correlation, alpha, power, test direction | Is study time associated with examination performance? |
| One-way ANOVA | Effect size, alpha, power, number of groups | Do mean scores differ across three teaching methods? |
| Chi-square test | Effect size, alpha, power, degrees of freedom or table structure | Is study mode associated with assessment preference? |
| Multiple regression | Effect size, alpha, power, predictors and tested model effect | Do motivation and attendance predict academic performance? |
The dissertation's primary hypothesis should normally guide the main sample-size calculation. If several planned analyses have different requirements, researchers may calculate multiple scenarios and plan around the most demanding analysis that is central to the study.
What Is an A Priori Power Analysis?
An a priori power analysis is conducted before data collection to determine the sample needed for a planned study. The researcher specifies the effect to be detected, desired power, alpha, statistical test, and relevant design parameters. The calculation then estimates the minimum analysable sample required under those assumptions.
This approach is especially useful in a dissertation proposal because it demonstrates prospective planning. The sample is justified before the researcher knows whether the final result will be statistically significant. This separation reduces the temptation to construct a sample-size rationale around the observed findings.
A priori analysis should be distinguished from calculating "observed power" after obtaining a p-value. Post hoc calculations based primarily on the observed effect and completed sample often add little useful information because they are closely tied to the result already observed. Confidence intervals, effect-size estimates, and discussion of precision can be more informative when interpreting completed research.
The published guide to sample size determination using G*Power explains that sample-size calculations should identify the hypothesis, effect size, power, alpha, and relevant Type I and Type II error considerations. This provides a useful framework for documenting an a priori calculation in a dissertation methodology.
How to Use G*Power for Dissertation Sample Size Planning
G*Power is widely used for a priori power analysis because it supports common families of statistical tests, including t, F, chi-square, z, and exact tests. The software does not decide the correct assumptions for the researcher. Its output is only as defensible as the test, effect size, alpha, power, and design parameters entered.
The first task is therefore to identify the planned statistical analysis accurately. A student testing a Pearson correlation should not select a two-group mean-comparison procedure merely because both produce p-values. Similarly, a dissertation using multiple regression needs a calculation corresponding to the intended regression hypothesis.
A typical a priori workflow is:
- Identify the primary research hypothesis.
- Select the statistical test that will answer that hypothesis.
- Choose an a priori sample-size calculation.
- Specify the effect size the study should be capable of detecting.
- Justify that effect size using literature, pilot evidence, or substantive reasoning.
- Specify the significance level, such as α = .05.
- Specify the desired statistical power, such as .80 or .90.
- Enter design-specific information such as group allocation, predictors, or number of groups.
- Calculate the minimum analysable sample.
- Adjust the recruitment target for expected attrition or unusable responses where appropriate.
The numerical result should then be documented alongside the assumptions that generated it. A screenshot from G*Power may be useful in an appendix if required by the programme, but the methodology still needs a written explanation. Software output is evidence of a calculation, not a substitute for methodological justification.
How to Choose an Effect Size for a Power Analysis
Effect-size selection is often the most difficult part of power analysis because the required sample can change dramatically depending on the value entered. The strongest approach is to identify an effect that is substantively meaningful and empirically plausible. Previous studies examining closely related variables are particularly valuable when their designs and populations resemble the proposed research.
Meta-analyses can provide stronger evidence because they synthesise effects across multiple studies. Pilot studies can also inform planning, although effect estimates from very small pilots are themselves uncertain and should not be treated as precise population values. Where direct evidence is unavailable, established conventions may be used cautiously and explicitly acknowledged as assumptions.
Researchers should also distinguish the effect they expect from the smallest effect they consider worth detecting. Designing a study around an unrealistically large expected effect can produce an artificially small sample requirement. If the true effect is more modest, the completed study may have inadequate power.
A transparent dissertation therefore explains where the effect-size assumption came from. Readers should be able to distinguish a literature-based estimate, a pilot estimate, a minimum meaningful effect, and a conventional benchmark.
Sample Size Examples for Different Dissertation Designs
The examples below illustrate how sample justification changes with the planned analysis. They are methodological examples rather than universal sample recommendations. Actual calculations should use parameters appropriate to the dissertation and the exact statistical model.
| Dissertation Design | Power Analysis Inputs | What Must Be Justified |
|---|---|---|
| Two-group experiment | Target standardised mean difference, alpha, power, allocation ratio | Expected difference and group allocation |
| Correlational survey | Target correlation, alpha, power, one- or two-sided test | Expected or minimum meaningful association |
| Three-group ANOVA | Target ANOVA effect size, alpha, power, three groups | Expected magnitude of between-group differences |
| Multiple regression | Target model effect, alpha, power, predictor structure | Number of predictors and effect being tested |
| Categorical association study | Target chi-square effect, alpha, power, table structure | Expected strength of association and category structure |
The examples demonstrate why copying another dissertation's sample size is rarely a sufficient justification. Even studies in the same subject area can require different samples if their statistical tests, expected effects, number of groups, or analytical objectives differ.
How Sampling Method and Sample Size Work Together
Power analysis answers a statistical question about the number of observations needed under specified assumptions. It does not determine how those observations should be selected from the population. Sampling strategy addresses that separate issue.
Epic Essay's guide to sampling methods in research distinguishes probability methods such as random and stratified sampling from non-probability approaches such as convenience and purposive sampling. These methods differ in how participants enter the study and therefore affect representativeness, selection bias, and the scope of generalisation.
A power calculation cannot convert convenience sampling into random sampling. If 200 volunteers are recruited through social media, the study may meet its numerical power target while still having selection limitations. Both dimensions need to be discussed honestly in the methodology.
The strongest sampling section therefore answers two different questions: why was this number of participants required, and how were those participants selected? Combining these questions into one vague statement can conceal important methodological limitations.
How to Adjust Sample Size for Attrition and Incomplete Responses
The minimum sample produced by a power calculation usually represents the number of analysable observations needed under the specified model. In practice, researchers may lose participants through withdrawal, incomplete questionnaires, eligibility problems, missing outcome data, or other exclusions. Recruitment planning may therefore need to exceed the minimum analysable sample.
Suppose a power calculation indicates that 160 complete cases are required and the researcher reasonably anticipates that 20% of recruited participants will not provide analysable data. Simply adding 20% of 160 produces 192 recruits, but losing 20% of 192 leaves only about 154. A more appropriate inflation calculation divides the required complete sample by the expected retention proportion: 160 / 0.80 = 200 participants.
The attrition assumption should itself be justified where possible. Previous studies using similar recruitment procedures, pilot work, institutional experience, or evidence about online survey completion may provide a reasonable estimate. Arbitrarily adding 10% because it is common practice is weaker than explaining why that allowance is plausible.
Distinguish the minimum analysable sample from the recruitment target. They are not necessarily the same number, and a methodology should make the difference explicit.
Population Size vs Statistical Power: Which Should Determine Your Sample?
Students often assume that sample size must always be calculated as a fixed percentage of the population. In many inferential analyses, however, statistical power is driven more directly by the target effect, statistical model, alpha, power, and variability than by the raw population size. Sampling from 50,000 people does not automatically mean that a fixed percentage such as 10% must be recruited.
Population size becomes important in particular designs, especially when sampling a substantial fraction of a finite population or when estimating population proportions to a specified margin of error. Survey sample-size formulas designed for prevalence or precision questions answer a different planning question from power calculations designed to detect an association or group difference.
This distinction explains why a population-based sample-size calculator should not automatically be used for every dissertation. A survey estimating the percentage of students satisfied with a service and a regression study testing whether three variables predict satisfaction require different forms of planning.
The researcher should therefore begin with the primary objective. If the goal is hypothesis testing, power analysis may be the relevant framework. If the goal is estimation to a particular level of precision, confidence-interval or margin-of-error planning may be more appropriate.
Can You Justify Sample Size Using a Rule of Thumb?
Rules of thumb sometimes appear in textbooks and research traditions, such as minimum cases per predictor or broad recommendations for particular analyses. They can provide a preliminary sense of feasibility, but they do not adapt well to differences in expected effect size, statistical power, measurement reliability, design complexity, or the specific hypothesis being tested.
A formal power analysis is therefore usually stronger when the dissertation involves confirmatory quantitative hypothesis testing and the required inputs can be reasonably specified. If a rule of thumb is used, the researcher should cite its methodological source, explain why it applies, and acknowledge its limitations rather than presenting it as a universal statistical requirement.
Rules can also conflict. One source may recommend ten observations per predictor while another recommends substantially more. Selecting whichever guideline produces the most convenient sample is not a defensible methodology.
Where formal power analysis is difficult because the model is unusually complex, simulation, sensitivity analysis, precision-based planning, or specialist statistical advice may provide a better solution. The justification should match the actual analytical problem rather than forcing it into an inappropriate generic rule.
What If You Cannot Reach the Sample Size from the Power Analysis?
Student researchers often face practical limits involving time, access, ethics approval, recruitment channels, and dissertation deadlines. If the calculated minimum is 250 participants but only 140 can realistically be recruited, the difference should not be hidden by rewriting the original power analysis. The limitation needs to be addressed transparently.
One useful approach is a sensitivity analysis. With the feasible sample fixed, the researcher can determine the minimum effect size that the planned analysis would be adequately powered to detect under the chosen alpha and power. This changes the question from "How many participants are required?" to "What magnitude of effect can this feasible sample detect with the desired power?"
The researcher can then explain the implication. A smaller feasible sample may still be informative for moderate or large effects while providing limited sensitivity to smaller effects. This is much more accurate than claiming that a convenience target became statistically adequate simply because recruitment proved difficult.
Practical feasibility belongs in dissertation planning, but it should complement rather than replace statistical reasoning. A transparent limitation is methodologically stronger than an unsupported claim that the available number was automatically sufficient.
How to Write a Sample Size Justification in Your Methodology
The sample-size paragraph should allow another researcher to understand and reproduce the reasoning. It should identify the power-analysis method or software, statistical test, effect size, alpha, desired power, and resulting minimum sample. If the recruitment target was inflated for attrition, that adjustment should also be explained.
A hypothetical write-up for a two-group study might state: "An a priori power analysis was conducted for the planned independent samples comparison. The calculation assumed a two-sided significance level of .05, power of .80, and a standardised effect size supported by previous research. The analysis indicated a minimum requirement of N participants. To allow for anticipated incomplete responses, the recruitment target was increased to N participants."
A correlational dissertation would require different wording because the target effect is a correlation rather than a standardised group difference. Similarly, regression analysis should identify the model or tested predictor effect used in the calculation. The justification must describe the calculation actually performed.
The final methodology should also explain participant selection. Epic Essay's dissertation methodology example shows that sampling strategy, participants, data collection, and analysis form connected parts of the research design. A strong sample-size paragraph therefore fits within a wider explanation of how the study will generate evidence capable of answering the research questions.
Common Sample Size and Power Analysis Mistakes
A common mistake is selecting a round number such as 100 or 200 and then searching for a source that appears to justify it. This reverses the logic of research planning. The analytical requirements should inform the target before recruitment begins.
Another problem is reporting that G*Power produced a sample without documenting the inputs. Two researchers can obtain dramatically different required samples from the same statistical test by entering different effect sizes or power targets. The software name alone therefore provides almost no information about how the calculation was constructed.
Students may also use the observed effect from their completed dissertation to claim that the original sample was adequately powered. This retrospective reasoning does not demonstrate that the study was prospectively designed to detect a meaningful effect. A priori planning and transparent sensitivity analysis provide more defensible approaches.
Finally, sample size should not be confused with sampling quality. A large biased sample does not automatically become representative, and a statistically powered study is not automatically a well-designed study. Recruitment, measurement, missing data, and analytical validity remain important regardless of participant numbers.
A Step-by-Step Checklist for Justifying Your Dissertation Sample
A systematic process makes sample-size justification easier to defend because every numerical assumption is connected to the research design. Begin with the primary research question rather than with the number of participants you think you can recruit.
Before finalising the methodology, work through the following sequence:
- Define the target population and unit of analysis.
- Identify the primary research question or hypothesis.
- Select the statistical analysis that directly tests that hypothesis.
- Determine the effect-size measure required by that analysis.
- Use previous literature, pilot evidence, or substantive reasoning to justify the target effect.
- Set and justify the significance level.
- Choose the desired statistical power.
- Enter all relevant design parameters into an appropriate power-analysis method or software package.
- Record the minimum analysable sample produced by the calculation.
- Inflate the recruitment target for justified attrition or unusable-data expectations where necessary.
- Explain the sampling method separately from the numerical sample-size calculation.
- Document the calculation and assumptions clearly enough for another researcher to reproduce them.
This sequence turns sample size from an arbitrary number into an explicit methodological argument. It also helps identify unrealistic projects early enough for the design, recruitment strategy, or research question to be reconsidered before data collection begins.
Building a Defensible Sample Size and Power Analysis for Your Dissertation
Sample size and power analysis should be treated as part of dissertation design rather than as a calculation added to the methodology after recruitment. The required sample depends on the primary statistical analysis, effect the study needs to detect, significance criterion, desired power, and relevant features of the research design. Changing any of these assumptions can change the number of observations required.
A strong justification also distinguishes statistical adequacy from sampling quality and practical recruitment. Power analysis can estimate how many analysable cases are required under specified assumptions, while the sampling strategy determines how those cases are selected. Attrition and incomplete responses may then require the initial recruitment target to exceed the calculated minimum.
The most defensible methodology makes every stage transparent: identify the primary hypothesis, justify the effect size, specify alpha and power, use the correct statistical model, report the calculated minimum, and explain any recruitment adjustment. When these decisions are documented clearly, the dissertation sample becomes an evidence-based component of the research design rather than an arbitrary number that the examiner is left to question.
Comments