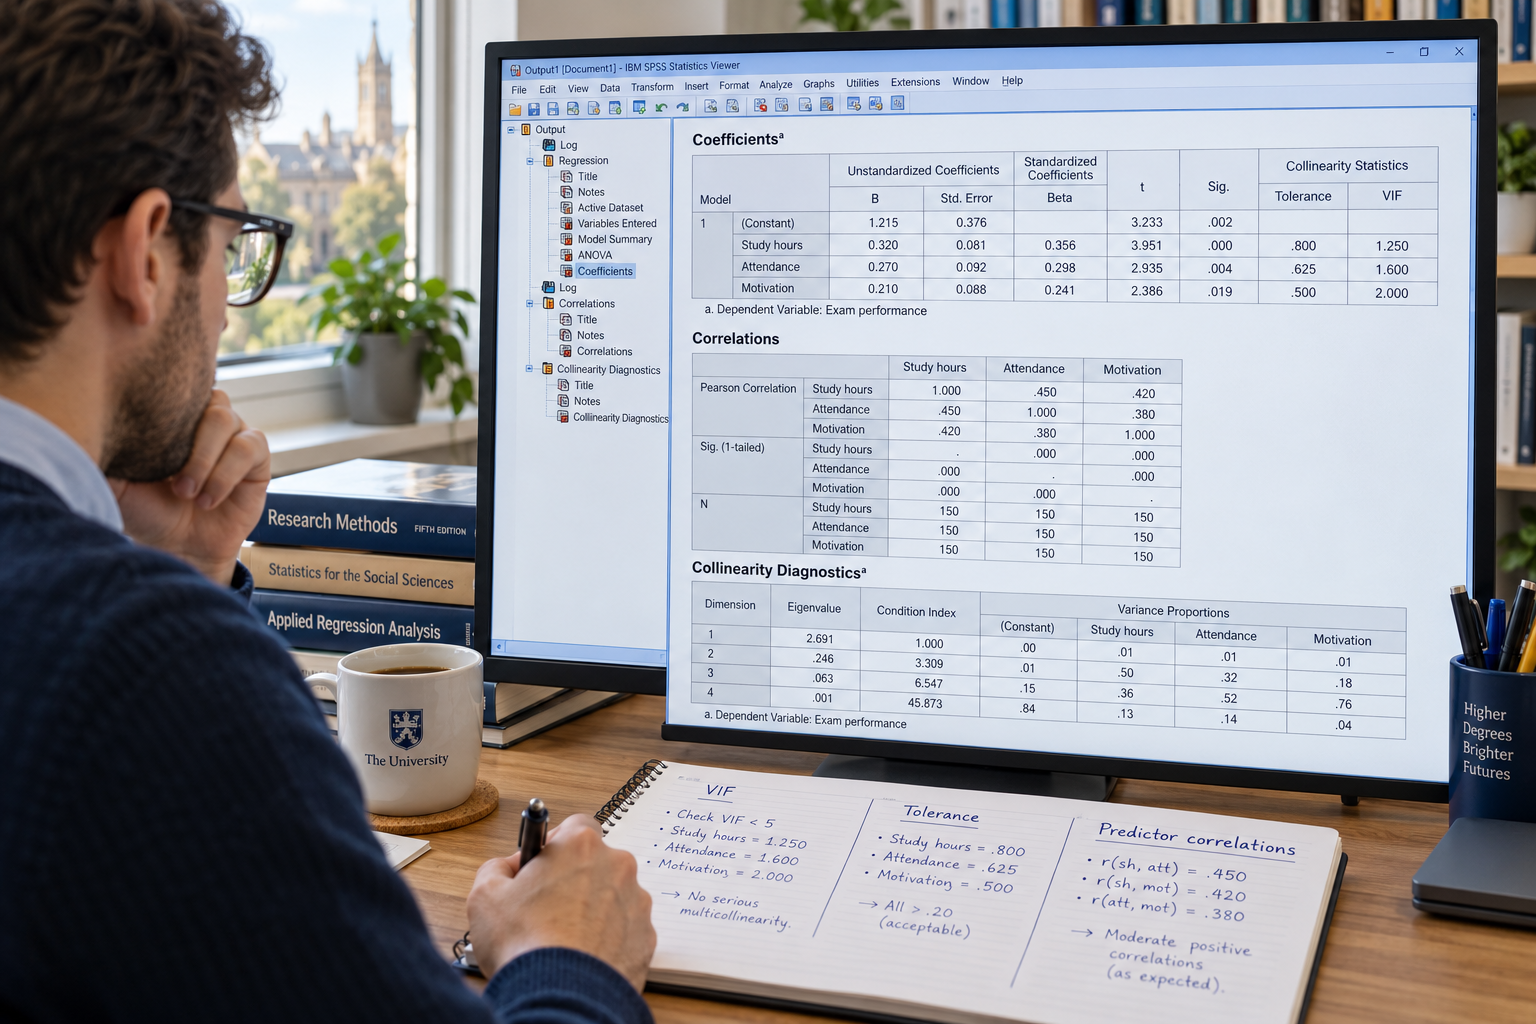
Multiple regression is designed to estimate how several predictors relate to an outcome while the other predictors in the model are held constant statistically. That advantage creates an important challenge: the model must be able to distinguish the information contributed by each predictor. When predictors overlap too strongly, their separate regression coefficients can become difficult to estimate precisely.
This problem is known as multicollinearity. Students commonly encounter it in SPSS through variance inflation factor (VIF) and tolerance statistics, yet interpreting those values correctly requires more than comparing them with a single cutoff. Multicollinearity can inflate standard errors, destabilise coefficients, produce unexpected signs, and make theoretically important predictors appear non-significant even when the overall regression model performs reasonably well.
A strong dissertation analysis should therefore diagnose the source and severity of multicollinearity before deciding how to respond. This guide explains what multicollinearity means, how VIF and tolerance are calculated, how to check collinearity in SPSS, why common thresholds are only diagnostic rules of thumb, and what researchers can do when predictors overlap substantially.
What Is Multicollinearity in Regression?
Multicollinearity occurs when one predictor in a multiple regression model can be predicted strongly from other predictors in the same model. The predictors are therefore carrying overlapping linear information. In the extreme case of perfect multicollinearity, one predictor is an exact linear combination of others and the regression coefficients cannot be estimated uniquely.
Less extreme multicollinearity is much more common. For example, a business dissertation might predict employee performance using job satisfaction, organisational commitment, work engagement, and motivation. These are conceptually distinct constructs, but they may still correlate strongly enough that separating their unique regression contributions becomes statistically difficult.
The Penn State regression guidance on multicollinearity explains that increasing collinearity inflates the variance of regression coefficient estimates. This means the coefficients can become unstable even when the underlying variables genuinely relate to the outcome.
Multicollinearity is primarily a problem of separating predictor effects. It does not automatically mean that the entire regression model is useless.
Why Does Multicollinearity Matter?
The main consequence of multicollinearity is reduced precision in individual regression coefficients. When several predictors contain similar information, the model struggles to determine which predictor should receive credit for explaining variation in the dependent variable. Standard errors increase, confidence intervals widen, and coefficient estimates can become sensitive to small changes in the sample or model specification.
This can create apparently contradictory output. A regression model may have a statistically significant overall F test and respectable R-squared while several individual predictors are non-significant. In some cases, predictors that have strong zero-order correlations with the outcome become weak after entering the multiple regression because their explanatory information overlaps substantially with other predictors.
Multicollinearity can also produce unstable coefficient signs. A predictor that is positively correlated with the outcome may receive a negative regression coefficient after several closely related variables are entered. That sign reversal is not automatically proof of an SPSS error; it may indicate that the coefficient is estimating a narrow conditional relationship in the presence of heavily overlapping predictors.
Epic Essay's regression analysis interpretation guide explains that regression coefficients represent relationships conditional on the other variables included in the model. Multicollinearity makes those conditional coefficients harder to estimate precisely and therefore harder to interpret confidently.
What Is VIF in Regression?
VIF stands for variance inflation factor. It quantifies how much the variance of a regression coefficient is increased because a predictor overlaps linearly with the other predictors in the model. Every predictor receives its own VIF because each predictor can have a different degree of redundancy with the remaining variables.
To understand the calculation, imagine temporarily treating one predictor as an outcome and regressing it on all the other predictors. The R-squared from that auxiliary regression indicates how well the remaining predictors explain that variable. VIF is then calculated from that R-squared.
VIF = 1 ÷ (1 - R² for predicting that predictor from the other predictors)
A VIF of 1 indicates no linear overlap with the remaining predictors. Larger values mean more of the predictor's information can be reconstructed from other variables, increasing uncertainty in its regression coefficient. The VIF does not describe how strongly the predictor relates to the dependent variable; it describes how strongly it overlaps with the other independent variables.
What Is Tolerance?
Tolerance expresses the same underlying information from the opposite direction. It is calculated as one minus the R-squared obtained when a predictor is regressed on the other predictors. It can also be calculated as the reciprocal of VIF.
Tolerance = 1 - R² = 1 ÷ VIF
High tolerance means that a substantial proportion of the predictor's variance is not explained by the other predictors. Low tolerance means that the variable is largely redundant with them. UCLA's SPSS regression diagnostics guidance describes tolerance as the proportion of variance in a predictor that cannot be accounted for by the remaining predictors.
Because VIF and tolerance are mathematical reciprocals, they should not be treated as independent pieces of evidence. A very high VIF necessarily corresponds with very low tolerance. Reporting both can still be useful because SPSS presents both statistics and many dissertation guidelines ask students to discuss them.
| VIF | Tolerance | General Diagnostic Meaning |
|---|---|---|
| 1.00 | 1.00 | No linear inflation from the other predictors |
| 2.00 | .50 | Some predictor overlap, often not inherently problematic |
| 4.00 | .25 | Warrants closer investigation in some guidance |
| 5.00 | .20 | Often treated as evidence of substantial collinearity requiring contextual evaluation |
| 10.00 | .10 | Commonly treated as a serious warning level |
| 20.00 | .05 | Severe overlap and potentially unstable coefficient estimation |
The values in this table should not be interpreted as universal pass-or-fail boundaries. The severity of a particular VIF depends on the research goal, coefficient precision, sample, theoretical model, and whether the affected predictor is central to the hypothesis.
What VIF Value Is Too High?
There is no single scientifically universal VIF cutoff. Penn State notes that VIF values above 4 warrant further investigation and values above 10 indicate serious multicollinearity. UCLA likewise treats tolerance below .10 and VIF above 10 as important warning signs in its SPSS regression diagnostics material.
Other textbooks and institutional guides use stricter thresholds such as 5, and some applied settings become concerned at even lower levels. This variation is precisely why students should avoid writing that "VIF must always be below 10" as though 9.9 is automatically acceptable and 10.1 automatically invalid.
VIF should instead trigger diagnostic reasoning. A VIF of 4.5 may deserve careful examination if a key coefficient changes dramatically when related predictors enter the model. A VIF of 6 may be less concerning in a prediction-focused analysis where individual coefficients are not the principal inferential target, provided the model's intended use and limitations are understood.
Treat VIF thresholds as diagnostic warnings, not automatic rules for deleting variables. The substantive model and purpose of the regression should determine what action is justified.
Can Pairwise Correlations Detect Multicollinearity?
A correlation matrix is a useful starting point because extremely high correlations between predictors can reveal obvious redundancy. If two variables correlate at .95, including both in an ordinary multiple regression deserves careful justification. However, pairwise correlations alone are not a complete multicollinearity diagnostic.
Multicollinearity can involve combinations of several predictors rather than one extremely correlated pair. A predictor may be moderately correlated with several other variables and nevertheless be highly predictable from them collectively. In that situation, no individual pairwise correlation needs to appear extreme.
This is why VIF is especially useful. It evaluates each predictor against the combined linear information in the remaining predictors. A correlation matrix and VIF therefore answer related but different diagnostic questions.
Students conducting quantitative dissertations should inspect both the correlation structure and the regression diagnostics. Epic Essay's quantitative thesis research guide emphasises that quantitative analysis should involve deliberate assessment of data quality and analytical assumptions rather than simply producing inferential statistics.
How to Check Multicollinearity in SPSS
SPSS can report VIF, tolerance, eigenvalues, condition indices, and variance proportions through the Linear Regression procedure. IBM's current SPSS linear regression documentation confirms that collinearity diagnostics include VIF and tolerance for individual predictors together with eigenvalues, condition indices, and variance-decomposition proportions.
The basic SPSS procedure is:
- Select Analyze.
- Select Regression.
- Select Linear.
- Move the outcome variable into the Dependent box.
- Move the predictors into the Independent(s) box.
- Select Statistics.
- Select Collinearity diagnostics.
- Keep the required coefficient and model-fit options selected.
- Run the regression.
- Inspect the Tolerance and VIF columns in the Coefficients table.
- Where necessary, examine the separate Collinearity Diagnostics table.
The IBM REGRESSION documentation explains that the collinearity option also produces eigenvalues, condition indices, and variance-decomposition proportions. These additional diagnostics can be useful when VIF indicates a problem or when the researcher needs to determine which variables participate in a problematic dependency.
How to Interpret VIF and Tolerance in SPSS
The VIF and tolerance values appear in the SPSS Coefficients table alongside B, standard error, beta, t, and significance. Students should examine each predictor rather than only looking at an average VIF. Multicollinearity can be concentrated in a subset of predictors while other variables remain largely unaffected.
Consider a hypothetical dissertation predicting employee performance from engagement, organisational commitment, job satisfaction, and years of experience. Suppose SPSS reports VIF values of 7.20 for engagement, 6.85 for commitment, 1.90 for job satisfaction, and 1.15 for experience. The first two variables deserve particular investigation because their values indicate substantially greater overlap with the predictor set.
The corresponding tolerances would be approximately .139 for engagement and .146 for commitment. These values reveal the same issue from the opposite direction. The researcher should then inspect correlations, theoretical definitions, measurement items, coefficient stability, and possibly condition diagnostics before deciding whether the model requires revision.
| Predictor | Tolerance | VIF | Interpretive Priority |
|---|---|---|---|
| Employee engagement | .139 | 7.20 | Substantial overlap; investigate further |
| Organisational commitment | .146 | 6.85 | Substantial overlap; investigate further |
| Job satisfaction | .526 | 1.90 | Limited inflation |
| Years of experience | .870 | 1.15 | Little evidence of collinearity |
The correct conclusion is not automatically that engagement and commitment must be deleted. The output indicates that their unique coefficients may be estimated with reduced precision. The next question is why they overlap and whether they represent theoretically necessary distinctions.
What Is the Condition Index?
Condition indices provide another way of examining linear dependencies among predictors. SPSS calculates them from eigenvalues associated with the predictor structure. Very small eigenvalues can indicate dimensions in which predictor information is nearly redundant, while large condition indices can signal potentially important dependencies.
A condition index is most informative when interpreted together with the variance-decomposition proportions. If several predictor coefficients have large proportions of their variance associated with the same high condition-index dimension, those predictors may be involved in a problematic collinearity structure.
Researchers sometimes quote condition-index thresholds mechanically, but the same caution applied to VIF is appropriate here. Condition indices are diagnostic evidence rather than automatic deletion rules. They should help identify the structure of a problem already suspected from model behaviour, VIF, tolerance, or the research design.
For most undergraduate and master's dissertations, VIF and tolerance provide an accessible primary diagnostic. Condition indices can add depth where the model is complex or the source of multicollinearity is not obvious.
What Causes Multicollinearity?
Multicollinearity can arise naturally because social, behavioural, business, and health variables are often conceptually related. Constructs such as depression and anxiety, income and wealth, engagement and commitment, or weight and body surface area can share substantial information. This form of collinearity may reflect genuine characteristics of the phenomenon being studied rather than poor data management.
Researchers can also create multicollinearity through model specification. Including several variables that measure almost the same construct can introduce unnecessary redundancy. A particularly clear example occurs when all categories of a dummy-coded categorical variable are entered together with an intercept, creating perfect linear dependence commonly known as the dummy-variable trap.
Polynomial and interaction models can create another form of collinearity. A variable X may correlate strongly with X squared, while X can also correlate with an interaction term formed from X and another predictor. This does not automatically mean the model is incorrectly specified because the higher-order terms may be required by the research hypothesis.
| Source | Example | Possible Response |
|---|---|---|
| Overlapping constructs | Engagement and organisational commitment | Revisit theoretical distinction and measurement validity |
| Duplicate or near-duplicate measures | Two variables measuring nearly the same score | Consider selecting or combining measures when theoretically justified |
| Dummy-variable trap | Entering every category plus an intercept | Use an appropriate reference category |
| Polynomial terms | X and X squared | Retain when theoretically necessary; consider centring where useful |
| Interaction terms | X, Z, and X × Z | Consider centring constituent continuous predictors for interpretive purposes |
| Restricted or unusual sample | Predictors move together within a narrow sampled population | Consider sampling structure and generalisability |
Understanding the source matters because different causes require different responses. Deleting one member of a theoretically necessary interaction is very different from removing a redundant duplicate measure.
What Should You Do When VIF Is High?
The first response should be investigation rather than immediate variable deletion. Check that the data were coded correctly, review the predictor correlation matrix, inspect the definitions of the variables, and determine whether two predictors measure essentially the same construct. Data-entry mistakes or incorrectly created dummy variables should be corrected before more complicated remedies are considered.
Next, return to theory. If two highly overlapping predictors represent genuinely different concepts central to the research questions, removing one merely to reduce VIF can create omitted-variable or specification problems. The researcher should consider whether the study is capable of estimating their unique contributions precisely rather than treating statistical convenience as the only criterion.
If variables are genuinely redundant and one provides no distinct theoretical information, removing one may be defensible. Alternatively, closely related items or indicators may sometimes be combined into a composite measure when measurement theory supports that decision. The choice should be justified conceptually and not made solely because one variable has the larger p-value.
Never delete a predictor solely because its VIF crosses an arbitrary threshold. Diagnose why the overlap exists and consider what deleting the variable would do to the meaning of the model.
Does Mean-Centring Solve Multicollinearity?
Mean-centring subtracts the sample mean from a continuous predictor, creating a variable whose zero point represents the sample mean. It is particularly useful in models containing interactions or polynomial terms because it can make lower-order coefficients easier to interpret and can reduce some forms of nonessential collinearity created by those terms.
However, centring does not solve fundamental redundancy between two distinct predictors. If job satisfaction and organisational commitment are strongly related because they measure overlapping constructs, subtracting their means does not remove that substantive relationship. Their correlation remains unchanged by ordinary mean-centring.
Students should therefore avoid the generic statement that "multicollinearity was solved by centring all variables." Centring is useful for particular model structures, but it is not a universal treatment for highly correlated predictors.
The methodological explanation should specify why centring was performed. If it supports interpretation of an interaction model, state that purpose directly rather than presenting it as a mechanical VIF-reduction technique.
Should You Combine Highly Correlated Predictors?
Combining variables can be appropriate when they are intended to measure dimensions of the same broader construct and there is theoretical and measurement evidence supporting a composite score. For example, several validated items may legitimately form a single scale rather than enter the regression as competing predictors.
However, variables should not be combined merely because they correlate strongly. If age and work experience are conceptually different variables, averaging them would produce an unclear quantity even if their correlation is high. Statistical overlap does not automatically establish measurement equivalence.
Dimension-reduction methods such as principal components analysis can sometimes replace a set of correlated variables with a smaller number of components. This can reduce collinearity but changes the research question because the regression then uses constructed components rather than the original predictors.
Any such transformation should therefore be justified in the methodology. A technically stable regression is not necessarily a theoretically meaningful regression.
Can Ridge or Lasso Regression Help?
Regularised regression methods such as ridge regression and lasso can be useful when prediction is the central objective and many correlated predictors are present. Ridge regression shrinks coefficients and can stabilise predictions when predictors overlap strongly. Lasso also penalises coefficient size and can shrink some coefficients to zero, effectively performing a form of variable selection.
These methods do not simply "repair" an ordinary multiple regression while leaving its interpretation unchanged. Penalisation changes the estimation procedure, coefficient behaviour, and inferential framework. A dissertation should therefore introduce ridge or lasso as a deliberate modelling strategy rather than quietly switching methods after seeing high VIF values.
For traditional explanatory dissertations focused on individual OLS coefficients and hypothesis tests, theory-driven variable selection or improved measurement may be more appropriate. For high-dimensional prediction problems, regularisation may be highly valuable. The research objective should determine the solution.
This distinction reflects a broader methodological principle: remedies should address the research problem, not only improve a diagnostic statistic.
Does Multicollinearity Bias Regression Coefficients?
Under the usual correctly specified ordinary least-squares framework, imperfect multicollinearity does not by itself make coefficient estimates systematically biased. The primary problem is variance: coefficient estimates become less precise and more unstable as predictors become harder to distinguish.
This distinction explains why an overall regression model can still predict reasonably well despite severe uncertainty about individual coefficients. If two predictors carry almost the same information, their combined predictive contribution may remain useful even though assigning a separate coefficient to each becomes difficult.
Perfect multicollinearity is different because the coefficients are not uniquely estimable. Software must omit a variable, alter the model, or otherwise resolve the exact dependency. Imperfect multicollinearity allows estimation but can make the resulting individual coefficients unreliable for interpretation.
Students should therefore avoid writing that multicollinearity "makes regression invalid" without qualification. Its seriousness depends heavily on whether the dissertation's objective is coefficient interpretation, hypothesis testing, prediction, or another modelling purpose.
A Dissertation Example of Multicollinearity
Consider a hypothetical business dissertation predicting employee performance from engagement, organisational commitment, job satisfaction, and years of experience. The overall regression is significant and explains 48% of the variance in performance. However, engagement and organisational commitment have VIF values of 7.20 and 6.85, and neither coefficient is individually significant despite both variables showing strong positive bivariate correlations with performance.
The appropriate interpretation is not that engagement and commitment have suddenly become irrelevant. Their unique regression coefficients ask what happens to performance as one variable changes while the other overlapping predictor is held constant. Because these constructs share substantial information, the model has limited precision in separating their unique associations.
The researcher could review the theoretical framework and measurement instruments to determine whether both predictors are essential. If they represent distinct hypotheses, retaining them and transparently discussing the imprecision may be preferable to deleting one solely to obtain significance. If they are effectively duplicate measures of the same construct, a theoretically supported composite or one preferred measure may provide a clearer model.
The final decision should therefore connect diagnostics to theory. That is more academically defensible than treating VIF as an automated variable-selection tool.
How to Report Multicollinearity in a Dissertation
The methodology or preliminary-analysis section should explain how multicollinearity was assessed and what criteria guided interpretation. The wording should be specific enough to show that the researcher understands the diagnostic rather than simply stating that "all regression assumptions were met."
A straightforward example for a model without problematic collinearity could read: "Multicollinearity was assessed using tolerance and variance inflation factors. VIF values ranged from 1.18 to 2.46 and tolerance values ranged from .407 to .847, indicating no evidence of severe predictor redundancy under the diagnostic criteria applied."
If values are more concerning, report them transparently and explain the response. For example: "Engagement and organisational commitment showed elevated VIF values of 7.20 and 6.85. Because both variables represented theoretically distinct constructs central to the hypotheses, they were retained, but individual coefficient estimates were interpreted cautiously due to reduced precision."
Epic Essay's guide to dissertation findings and discussion emphasises that statistical findings should be reported accurately before their wider implications are interpreted. Multicollinearity diagnostics are part of demonstrating that the regression coefficients have been evaluated critically rather than accepted automatically.
Common Multicollinearity Mistakes Students Should Avoid
The first mistake is using only a correlation matrix and assuming that no correlation above .80 means multicollinearity cannot exist. VIF evaluates whether a predictor can be explained collectively by the remaining predictors, so multivariable dependencies can exist without one extreme pairwise correlation.
A second mistake is deleting the predictor with the highest VIF automatically. This may reduce the diagnostic value while damaging the theoretical model. Variables should be removed because the revised specification makes conceptual and statistical sense, not simply because the SPSS table becomes cleaner.
Students also sometimes claim that high VIF proves two variables measure exactly the same construct. It does not. VIF indicates linear redundancy in the analysed sample; it does not establish conceptual identity or measurement validity.
Another mistake is focusing only on whether VIF is under 10. A predictor with VIF = 6 may already have substantially inflated uncertainty, particularly when the coefficient is central to the dissertation. Diagnostic interpretation should consider coefficient stability, confidence intervals, theoretical overlap, and the study objective.
A Step-by-Step Multicollinearity Checklist
A defensible regression analysis treats collinearity diagnostics as part of model evaluation rather than as a final SPSS checkbox. Students should examine both statistical evidence and the conceptual relationships among predictors before altering the model.
- Confirm that the regression model is theoretically justified before evaluating diagnostics.
- Check predictor coding and identify accidental duplicate variables.
- Inspect the predictor correlation matrix for obvious high correlations.
- Request collinearity diagnostics in SPSS Linear Regression.
- Inspect tolerance and VIF for every predictor.
- Treat commonly cited thresholds as warnings rather than automatic deletion rules.
- Use condition indices and variance proportions when the collinearity structure requires deeper diagnosis.
- Identify whether the overlap is substantive, structural, or caused by coding.
- Correct dummy-variable dependencies or model-construction errors.
- Consider whether highly overlapping variables are theoretically distinct.
- Remove a predictor only when the revised model remains conceptually defensible.
- Consider a validated composite when variables legitimately represent the same construct.
- Use centring appropriately for interaction or polynomial models rather than as a universal cure.
- Consider regularised regression when prediction and high-dimensional correlated predictors justify it.
- Report the diagnostic values and methodological decision transparently.
This process prevents multicollinearity analysis from becoming an arbitrary threshold exercise. It also makes the final regression easier to defend because every modification can be connected to both statistical evidence and the dissertation's theoretical framework.
Managing VIF and Tolerance Without Damaging Your Regression Model
Multicollinearity occurs when predictors contain overlapping linear information, reducing the precision with which their unique regression coefficients can be estimated. VIF expresses how much coefficient variance is inflated by that overlap, while tolerance expresses the proportion of predictor variance not accounted for by the remaining predictors. High VIF and low tolerance therefore describe the same underlying problem from opposite directions.
The most important lesson is that diagnostic thresholds should trigger investigation rather than automatic model editing. VIF values around 4 or 5 may warrant closer examination, while values approaching or exceeding 10 are commonly treated as serious warnings, but the appropriate response depends on theory, model purpose, coefficient stability, and the source of the redundancy. Pairwise correlations, condition diagnostics, and substantive understanding can help determine what the numbers actually mean.
For dissertation research, the strongest response is transparent and theory-driven. Correct coding problems, retain important predictors when their conceptual role justifies them, combine variables only when measurement theory supports doing so, and use alternative modelling approaches when the research objective genuinely requires them. A good regression model is not the one with the lowest possible VIF values; it is the one that represents the research question coherently while producing estimates whose limitations have been properly diagnosed and reported.
Comments