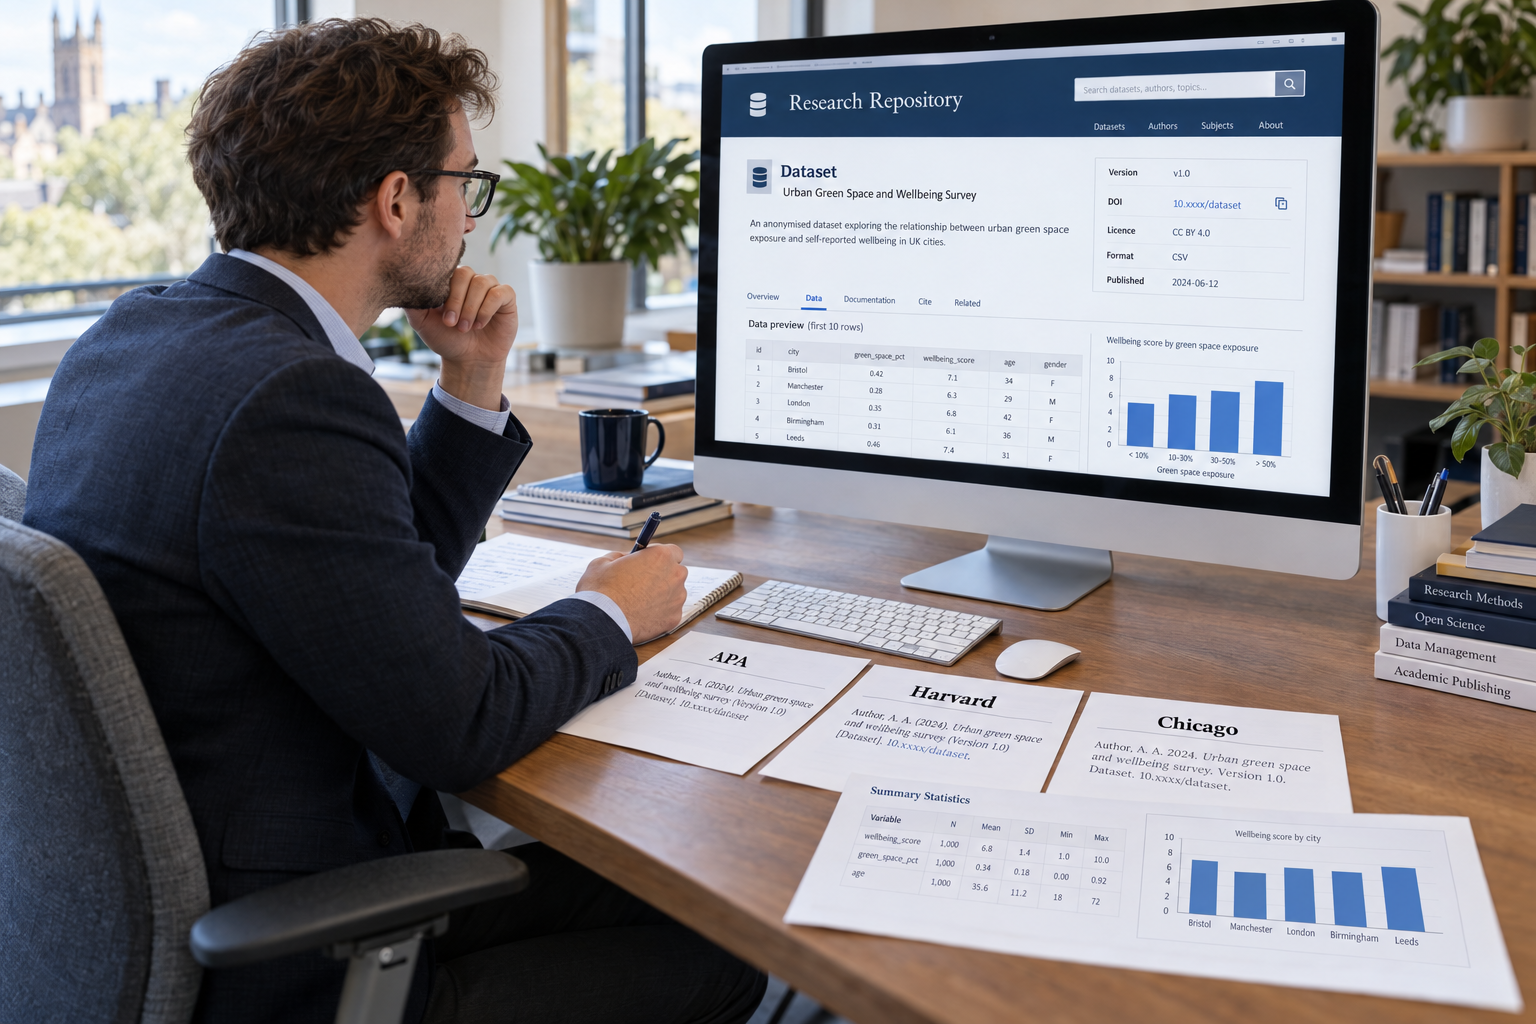
Academic research increasingly depends on data that exist separately from traditional journal articles, books, and reports. Students may analyse census microdata, download economic indicators, reuse survey responses from a research repository, work with environmental measurements, or conduct a dissertation using an existing public dataset. When those data form part of the evidence used in an assignment, they need to be acknowledged accurately.
Learning how to cite a dataset in APA, Harvard, and Chicago can be more difficult than citing an ordinary article because a dataset may have a creator, release year, version number, repository, DOI, study identifier, and access date. Some datasets also change over time, while others are permanently archived as specific versions. Correct referencing therefore helps readers identify not only the data source but the exact dataset or release that supported the analysis.
The first decision is not actually where to place the commas or brackets. Students must establish whether they used the underlying dataset itself or merely encountered statistics in a report, article, table, or webpage. This guide explains that distinction before showing practical dataset citation formats for APA 7, Harvard, and Chicago, with dissertation-focused examples and common mistakes to avoid.
What Is a Dataset Citation?
A dataset citation is a formal reference to a collection of research data that has been created, published, archived, or distributed as an identifiable research output. The data may consist of survey responses, experimental measurements, demographic records, financial observations, environmental readings, coded texts, or another organised body of information. A dataset citation allows the reader to determine who created the data, when they were released, which version was used, and where they can be accessed.
This matters because datasets can function as evidence in their own right. If a student downloads household survey microdata and calculates a regression model, the downloaded dataset is part of the empirical foundation of the dissertation. Citing only a webpage that describes the survey may not identify the precise research object that generated the student's findings.
Epic Essay's academic referencing guide explains the broader principle that sources should be traceable and connected clearly to the material derived from them. Dataset citation applies that principle to research data rather than conventional prose publications.
A dataset citation should identify the data you actually used, not merely the website on which you first discovered that the data existed.
Dataset vs Report vs Database: Which One Should You Cite?
A dataset is not necessarily the same thing as the database or repository containing it. Repositories such as institutional archives can hold thousands of different studies, files, or versions. Referencing only the repository homepage may therefore be too broad to show readers which data were analysed.
A dataset is also different from a report that presents findings derived from data. If you read an official report and use a statistic already calculated and published by its authors, the report may be the appropriate source. If you download the underlying dataset and calculate your own percentage, correlation, regression, or other result, the dataset becomes the relevant research source.
This distinction is especially important in dissertations using secondary data. Epic Essay's guide to thesis research methods identifies secondary data analysis as a legitimate quantitative research approach, but methodological transparency requires students to identify where the analysed data originated.
| What You Used | What You Normally Cite | Typical Example |
|---|---|---|
| Downloaded dataset | The specific dataset | You download survey microdata and perform your own analysis |
| Statistic reported in an article | The article | You quote a percentage calculated by the article's authors |
| Statistic reported in an official report | The report | You use an unemployment figure published in a labour report |
| Online statistical table | The table or source specified by the provider | You reproduce values directly from an official table |
| Repository containing many studies | The individual dataset | You retrieve one archived study from a large data repository |
| General information about a database | The database or relevant webpage | You describe the database rather than analyse a specific dataset |
The key question is therefore where your evidence actually came from. A reference should lead the reader as directly as possible to the research object supporting your analysis.
What Information Do You Need Before Citing a Dataset?
Before formatting the reference, collect the metadata supplied by the dataset provider. Well-managed repositories often display a recommended citation, DOI, version number, creators, publication date, and repository name on the dataset landing page. These details are more reliable than trying to construct a reference from the downloaded filename alone.
The creator may be an individual researcher, a team, government agency, university, research centre, or international organisation. The relevant year is normally associated with the publication or release of the dataset or version being cited, not automatically the historical period represented by the data. For example, a dataset released in 2025 may contain observations collected between 2018 and 2023.
Version information becomes particularly important when a dataset has been corrected, expanded, or reissued. Two researchers who cite the same dataset title but analyse different versions could obtain different results. A DOI or other persistent identifier helps readers locate the exact research object even if a repository changes its web structure.
| Element | What to Record | Why It Matters |
|---|---|---|
| Creator | Individual author, research team, or organisation | Establishes responsibility for creating the dataset |
| Year | Publication or release year of the cited dataset | Identifies the release being used |
| Dataset title | Full official title | Identifies the research object |
| Identifier | Study number or catalogue number where relevant | Helps distinguish datasets with similar titles |
| Version | Version, edition, release, or revision number | Shows exactly which data were analysed |
| Repository or publisher | Archive or organisation distributing the data | Shows where the dataset is maintained |
| DOI | Persistent digital object identifier | Provides a durable route to the dataset |
| URL | Stable dataset landing page when no DOI exists | Provides retrieval information |
| Access date | Date on which changing data were accessed | Can identify the state of a dynamic dataset |
Not every style uses all these elements in exactly the same order. Recording them before writing, however, allows the reference to be adapted accurately to APA, Harvard, Chicago, or a university-specific convention.
How to Cite a Dataset in APA 7
APA 7 treats a dataset as a citable research output when the data themselves are being analysed or presented. The APA Style guidance for data set references places the dataset title after the creator and year, followed by any relevant identifier or version information and a bracketed description identifying the material as a data set.
A common APA 7 structure is:
Author, A. A. (Year). Title of data set (Identifier; Version X) [Data set]. Publisher or Repository. DOI or URL
An illustrative reference might therefore look like this: Morgan, L. J. (2025). University student engagement survey (Study 241; Version 2) [Data set]. National Education Data Archive. https://doi.org/10.xxxx/xxxxx. The DOI shown here is intentionally illustrative rather than a real source.
APA uses the normal author-date system for the in-text citation. The corresponding parenthetical citation would be (Morgan, 2025), while a narrative citation could read Morgan (2025). If an organisation created the dataset, the organisation can function as the corporate author.
APA Dataset with a DOI
Where a DOI is supplied, it should normally be preferred because it is designed to provide a persistent identifier for the research object. APA presents modern DOIs as hyperlinks beginning with https://doi.org/. Students should copy the DOI from the repository record rather than construct one from memory.
The University of Melbourne's APA 7 dataset guidance similarly identifies author, year, dataset title, the description "[Data set]," publisher or source, and DOI as the main elements. It also notes that the dataset title is italicised under normal APA presentation and that a URL can be used where a DOI is unavailable.
APA Dataset Without a DOI
If no DOI exists, APA can use the URL of the dataset or its stable landing page. The objective is to direct the reader to the specific research object, not simply to the organisation's home page. A stable repository record is therefore usually more useful than a generic website address.
APA retrieval dates are generally unnecessary for fixed archived datasets. They become relevant when the contents are designed to change over time and the reader may otherwise see different values later. Students should therefore distinguish a permanent archived release from a continuously updated statistical resource.
How to Cite a Dataset in Harvard Referencing
Harvard referencing requires particular caution because there is no single universal Harvard manual. Universities create their own Harvard variants, meaning punctuation, capitalisation, access-date requirements, and treatment of online material can differ. Students should use their institution's guide rather than assuming that one Harvard template applies everywhere.
A useful institutional example is the University of Leeds Harvard dataset guide. Leeds gives the following general structure:
Family name, INITIAL(S). Year. Title of dataset. Publisher. [Online]. [Accessed Day Month Year]. Available from: DOI or URL
An illustrative example could therefore be: Morgan, L.J. 2025. University student engagement survey. National Education Data Archive. [Online]. [Accessed 7 October 2026]. Available from: https://doi.org/10.xxxx/xxxxx. The example demonstrates the structure only and should not be submitted as a genuine source.
The in-text citation follows Harvard's author-date logic, for example (Morgan, 2025). Where a government department, university, company, or international organisation created the dataset, that organisation can normally be treated as the corporate author.
Students should compare this structure with the exact rules supplied by their university. Epic Essay's Harvard referencing guide explains why local institutional requirements take priority when different Harvard versions prescribe slightly different formats.
How to Cite a Dataset in Chicago Author-Date Style
Chicago offers two citation systems: Author-Date and Notes and Bibliography. Students therefore need to identify which Chicago system their department requires before formatting a dataset. The Author-Date system is common in scientific and social-scientific work and connects parenthetical citations to a final reference list.
Curtin University's current Chicago 18 Author-Date dataset guidance uses a structure based on creator, year, dataset title, publisher or source, and DOI or URL. A practical pattern is:
Author Surname, First Name. Year. "Title of Dataset." Publisher or Source. DOI or URL.
An illustrative entry could therefore read: Morgan, Lena J. 2025. "University Student Engagement Survey." National Education Data Archive. https://doi.org/10.xxxx/xxxxx. The corresponding Chicago Author-Date in-text citation would be (Morgan 2025).
Chicago Author-Date does not place a comma between the author's surname and year in the parenthetical citation. This appears minor, but mixing APA or Harvard punctuation into Chicago is a common consistency error. The complete reference should remain aligned with Chicago conventions from beginning to end.
How to Cite a Dataset in Chicago Notes and Bibliography
Chicago Notes and Bibliography uses numbered footnotes or endnotes rather than author-date parenthetical citations. A full note normally identifies the creator, dataset title, repository or source, publication information, and DOI or stable URL. A bibliography entry then reorganises the same essential information with the lead creator's surname first.
A practical note pattern for an identifiable dataset is:
1. First Name Last Name, "Title of Dataset," Repository or Publisher, Year, DOI or URL.
The corresponding bibliography pattern can be structured as:
Last Name, First Name. "Title of Dataset." Repository or Publisher, Year. DOI or URL.
An illustrative first note could therefore be: 1. Lena J. Morgan, "University Student Engagement Survey," National Education Data Archive, 2025, https://doi.org/10.xxxx/xxxxx. A later shortened note could identify Morgan and a shortened dataset title, provided the reader can connect it clearly to the earlier citation.
Because Chicago accommodates an unusually wide range of source types, institutional examples may differ in how a specialised research dataset is described. Students should therefore consult the current Chicago manual or their university's Chicago guide when a repository provides additional elements such as versions, accession numbers, release dates, or data-specific identifiers.
APA vs Harvard vs Chicago Dataset Citations
The three systems cite the same underlying research object but organise the information differently. APA explicitly uses a bracketed description such as "[Data set]," Leeds Harvard adds an online designation and access date, while Chicago Author-Date follows its own author-year reference structure. These differences mean that copying a dataset citation from a repository without checking the required style can produce inconsistent formatting.
| Feature | APA 7 | Harvard Example | Chicago Author-Date |
|---|---|---|---|
| In-text system | Author-date | Author-date | Author-date |
| Typical in-text form | (Morgan, 2025) | (Morgan, 2025) | (Morgan 2025) |
| Dataset description | [Data set] | May use [Online] under institutional conventions | Usually identified through title and source context |
| Version information | Included when available | Follow institutional rules and repository metadata | Include where necessary to identify the cited release |
| DOI | Preferred when available | Used when available under the selected Harvard variant | Used when available |
| Access date | Normally for changing data | Frequently required for online datasets in institutional Harvard systems | Useful where no publication date exists or the data change over time |
The table highlights why the phrase "cite the dataset" does not mean "use the same reference and change the heading." Each referencing system determines the sequence, punctuation, descriptive labels, and in-text relationship for the citation.
How to Cite a Government Dataset
Government datasets frequently use organisations rather than named individual researchers as their creators. The relevant statistical office, department, ministry, bureau, or agency can therefore function as the corporate author. Students should use the specific organisation responsible for the data rather than a vague label such as "government."
For example, if a national statistics agency releases an employment dataset, the agency name would normally occupy the author position. The dataset title, release year, version where applicable, repository or publisher information, and DOI or stable URL would then be arranged according to APA, Harvard, or Chicago rules.
The year represented by the observations should not automatically replace the publication year. A dataset titled "Labour Market Survey 2023" might have been released or revised in 2024. Students should inspect the official metadata and use the date required by the citation style.
If you did not download or analyse the dataset but instead copied a figure from an official report, cite the report rather than pretending to have used the underlying data. The citation should always represent your actual research process.
How to Cite World Bank, OECD, and Other International Data
International organisations often provide both publications and interactive statistical databases. The correct citation depends on how the information was accessed. If you quote a statistic from a published report, cite that report; if you download a specific dataset or data series for analysis, identify the appropriate dataset or statistical resource.
Dynamic databases require additional thought because their contents can be revised. A stable downloaded release with a DOI may be cited as a fixed dataset, whereas an interactive table that changes over time may require an access or retrieval date under the applicable style. Students should inspect the provider's recommended citation because major statistical organisations often supply source-specific instructions.
The organisation itself commonly functions as the corporate author. However, the name displayed on the platform should not be confused automatically with the dataset creator if another organisation actually produced the data. Repository metadata can clarify the roles of creator, publisher, distributor, and host.
This distinction strengthens methodological reporting. When a dissertation claims to analyse World Bank or OECD data, the reader should be able to determine which indicator, years, countries, release, and dataset were used rather than being directed only to a generic homepage.
What If the Dataset Has a Version Number?
Version numbers should be retained when they help identify the specific dataset analysed. Research repositories may issue revised files after correcting errors, adding observations, improving documentation, or extending the collection period. Ignoring the version can make reproducibility more difficult.
APA explicitly provides space for identifiers and versions after the dataset title. Harvard institutions may incorporate version information according to their local rules, while Chicago can also include a version where it is necessary to distinguish the research object. Repository-generated citations are useful for locating this metadata even when their punctuation needs adjustment.
If the DOI itself resolves to a specific version, that persistent identifier provides additional precision. Nevertheless, including an explicitly supplied version in the reference can help readers understand which release was used without opening the DOI record.
Do not silently replace the version you analysed with a newer version that appeared before you submitted the dissertation. Your citation should identify the evidence that actually produced your results.
When Does a Dataset Need an Access or Retrieval Date?
Access dates are particularly relevant when data are designed to change. An interactive economic database may update values after revisions, while a live public-health dashboard may replace yesterday's figures with today's information. Readers need to know when the researcher observed the values if the source does not preserve a stable historical version.
APA generally reserves retrieval dates for content designed to change over time. By contrast, Harvard variants such as Leeds Harvard routinely include an accessed date for online datasets. Chicago guidance can also use an access date where publication information is unavailable or the underlying resource is continuously revised.
A fixed archived dataset with a permanent DOI normally creates less ambiguity because the cited object can remain retrievable as a defined release. Students should therefore determine whether they are dealing with a stable dataset or a dynamic statistical service before deciding which date information is needed.
The access date should not be used to disguise missing metadata. If a publication year or version exists, record it. An access date answers when you consulted the source, not when the data were created or released.
How to Cite Data You Created Yourself
Students do not normally create a conventional external reference to unpublished raw data that exist only on their personal computer and are unavailable to readers. Instead, the methodology explains how the data were generated, while tables, figures, appendices, or supplementary files present relevant parts of the resulting evidence according to institutional requirements.
The situation changes when a student deposits their research data in a repository and the dataset receives a persistent identifier. Once it exists as a retrievable research object, it can be cited similarly to other archived datasets. This can be particularly relevant for doctoral research, open-science projects, or journal articles requiring data availability.
Students should not upload participant data merely to make them citable. Ethics approval, informed consent, confidentiality commitments, legal restrictions, and institutional data-management rules determine whether research data may be shared. Methodological transparency does not override participant protection.
Where data remain confidential, describe the collection and analysis procedures accurately without exposing restricted information. The objective is responsible transparency, not universal public availability.
How to Mention the Dataset in a Dissertation Methodology
A reference-list entry alone does not explain how secondary data were used. The methodology should identify the dataset, justify why it was appropriate, state relevant years or waves, explain inclusion and exclusion decisions, and describe any cleaning or transformation undertaken before analysis. Epic Essay's methodology writing guide emphasises that data sources and selection decisions should be transparent and academically justified.
For example, a dissertation might state that it used an archived national employment dataset covering respondents aged 18–35 between specified years. It could then explain why those observations were selected, which variables were extracted, how missing values were handled, and what analytical procedure followed. The dataset citation identifies the source, while the methodology explains the researcher's use of it.
This distinction is important because citing data does not replace methodological justification. Two researchers can use the same dataset but select different variables, exclude different cases, or apply different statistical models. Readers need both the citation and a transparent account of those decisions.
Students should also preserve an accurate record of the dataset version used. Good research organisation makes it easier to ensure that the reference list, methodology, data files, and statistical outputs all point to the same source.
Should You Cite Both the Dataset and Its Related Article?
Some datasets accompany a journal article describing how the data were collected. If you use both the dataset and the article, each can serve a different evidential function. The dataset supports the empirical analysis you performed, while the article may provide methodological background, sampling information, theoretical context, or interpretation from the original researchers.
You should therefore not assume that citing the article automatically replaces a dataset citation when you directly analysed archived data. Conversely, do not cite a dataset merely because an article mentions that data exist if all your information came from the article itself.
Where both are genuinely used, cite both. In the methodology, the dataset citation can identify the data analysed, while the related publication can support statements about the original study's recruitment, measurement design, or data-collection procedures.
This produces a clearer scholarly trail. Readers can distinguish what the original researchers wrote about the study from the underlying data that you analysed independently.
Common Dataset Citation Mistakes Students Should Avoid
A common mistake is citing the repository rather than the individual dataset. Writing only "Figshare," "Dryad," or another archive name may identify where the information is hosted but not which research object was used. Always look for the dataset's own metadata page.
A second mistake is omitting the version. This can become significant when archived data are corrected or expanded. If the repository provides a version, edition, release number, or study identifier that your citation style accommodates, use it to improve precision.
Students also frequently confuse the year represented by the data with the publication year. A dataset containing measurements from 2010–2020 could have been released in 2022. The citation year should follow the rules of the referencing system and the metadata for the dataset rather than being guessed from the observational period.
Do not invent missing dataset metadata. If the author, year, version, DOI, or publisher is unclear, inspect the repository record and follow your citation style's rules for genuinely missing information.
Another error is citing the dataset when the student never accessed it. If your knowledge of the results comes entirely from a report or journal article, cite that publication. Accurate referencing should describe the evidence you actually consulted.
A Step-by-Step Checklist for Citing a Dataset Correctly
Dataset referencing becomes straightforward when the citation is built from verified metadata rather than copied blindly from an automated generator. Before submitting an assignment or dissertation, check both the bibliographic entry and the way the data are described in the methodology.
- Confirm that you actually used the dataset rather than only a report discussing it.
- Open the dataset's official repository or publisher record.
- Identify the individual creator or corporate author.
- Record the dataset's publication or release year.
- Copy the complete official dataset title.
- Record any study identifier, version, edition, or release number.
- Identify the repository, archive, publisher, or distributor.
- Use the DOI where one is supplied.
- Use a stable dataset URL when no DOI is available.
- Add an access or retrieval date when required by the style or because the data change over time.
- Format the entry specifically for APA, your university's Harvard variant, or the required Chicago system.
- Make sure the in-text citation or footnote corresponds with the final reference.
- Describe the specific subset, years, waves, or variables used in the methodology where relevant.
- Check that the dataset version in the citation matches the version actually analysed.
Automated citation exports can help retrieve metadata, but they should still be checked manually. Repository-generated citations may follow a different style, capitalisation rule, or version of a citation standard from the one required by your university.
Citing Datasets Accurately in Academic Research
Knowing how to cite a dataset in APA, Harvard, and Chicago begins with identifying the exact research object that supplied your evidence. When you analyse downloaded or archived data directly, the dataset itself deserves a traceable citation. When you merely use a statistic reported in an article, report, or webpage, that publication may instead be the appropriate source.
APA 7 identifies datasets explicitly as research outputs and provides a structure for dataset titles, identifiers, versions, repositories, and DOIs. Harvard follows the same broad goal of author-date traceability but varies between institutions, making the university's prescribed version essential. Chicago requires an additional decision between Author-Date and Notes and Bibliography before the final format can be determined.
Whichever style is required, accuracy matters more than simply making the reference look technical. Verify the creator, year, title, version, repository, DOI, and access information against the official dataset record, then make sure the citation matches the data actually analysed. A precise dataset citation strengthens reproducibility, supports methodological transparency, and gives proper credit to the researchers and organisations responsible for producing the evidence behind your academic work.
Comments