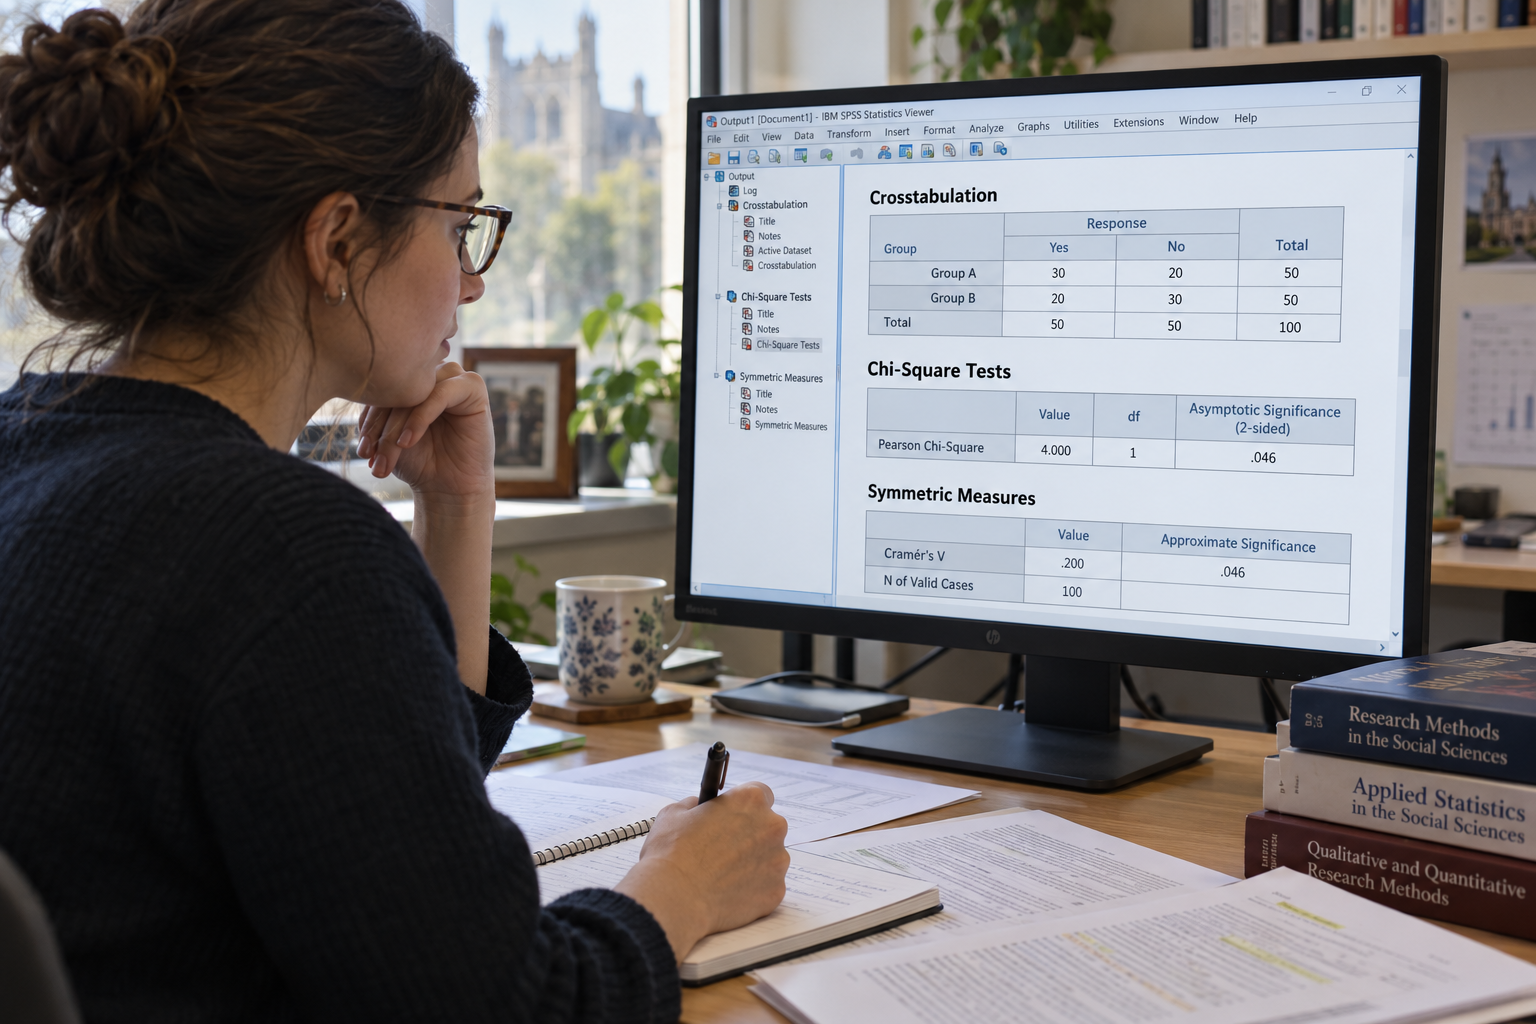
Categorical data appear throughout university research. A business student might examine whether purchasing preference differs by age group, an education researcher might investigate whether learning preference is associated with year of study, and a health researcher might test whether treatment group is associated with recovery status. When both variables are categorical, the chi-square test of independence provides a widely used method for examining whether the observed pattern of frequencies is consistent with statistical independence.
Running a chi-square test in SPSS is relatively straightforward, but correct interpretation involves considerably more than finding a p-value below .05. Researchers need to understand the crosstabulation, compare observed and expected frequencies, check whether expected cell counts are adequate, interpret the Pearson chi-square statistic and degrees of freedom, and assess the strength and pattern of any association. Measures such as Phi and Cramér's V can add important information that statistical significance alone does not provide.
This guide explains how to conduct and interpret a chi-square test in SPSS step by step. It focuses primarily on Pearson's chi-square test of independence for two categorical variables, while also distinguishing it from the chi-square goodness-of-fit test. Practical examples show how to interpret SPSS output and turn the statistics into a concise, academically appropriate results write-up.
What Is a Chi-Square Test?
A chi-square test works with frequencies or counts rather than comparing means. In a test of independence, the central question is whether two categorical variables are associated. The null hypothesis states that the variables are independent, meaning that the distribution of one variable does not systematically vary according to the categories of the other variable.
SPSS handles this type of analysis through crosstabulation. IBM explains that the Crosstabs procedure creates two-way or multiway tables and can calculate Pearson's chi-square alongside measures of association. The table displays how cases are distributed across combinations of categories, allowing the researcher to compare the pattern actually observed with the pattern expected if the variables were independent.
Suppose a university researcher records students' mode of study as online or campus-based and their preferred assessment type as examination, coursework, or mixed assessment. Both variables are categorical. Pearson's chi-square can evaluate whether assessment preference is distributed independently of study mode or whether the observed frequencies provide evidence of an association.
The chi-square test of independence asks whether the pattern of observed frequencies across two categorical variables differs sufficiently from the pattern expected if those variables were independent.
Chi-Square Test of Independence vs Goodness-of-Fit Test
The term "chi-square test" can refer to more than one procedure. The chi-square test of independence examines the relationship between two categorical variables, whereas the goodness-of-fit test examines the distribution of one categorical variable against a specified expected distribution. Confusing these procedures can lead students to answer a different research question from the one they intended.
IBM describes its one-sample chi-square procedure as a goodness-of-fit test that compares observed frequencies across categories with equal or user-specified expected proportions. For example, a researcher could test whether four response categories occur equally often. By contrast, Crosstabs can be used to test whether two variables, such as employment status and preferred working arrangement, are independent.
The distinction can be summarised clearly.
| Feature | Chi-Square Test of Independence | Chi-Square Goodness-of-Fit Test |
|---|---|---|
| Number of categorical variables | Two | One |
| Main question | Are the two variables associated? | Does the observed distribution match an expected distribution? |
| Typical data structure | Contingency table | Frequency distribution |
| Example | Is study mode associated with assessment preference? | Are four assessment preferences equally common? |
This guide concentrates on the test of independence because it is commonly encountered in survey research, dissertations, and SPSS Crosstabs analysis. Students conducting a goodness-of-fit test should use the corresponding one-variable procedure and define the expected distribution appropriately.
When Should You Use a Chi-Square Test in SPSS?
Pearson's chi-square test of independence is appropriate when the research question concerns an association between categorical variables. These variables may be nominal, such as department or preferred brand, or may contain ordered categories, such as low, medium, and high satisfaction. The standard chi-square test uses the category frequencies rather than treating category codes as continuous measurements.
This distinction is important when working with survey datasets. Coding "Yes" as 1 and "No" as 2 does not turn the variable into a quantitative measure. The numbers simply identify categories, so statistical procedures should reflect the underlying measurement level rather than the numerical appearance of the codes.
Chi-square is also different from tests designed to compare means. If the outcome is a continuous examination score and the researcher wants to compare two groups, an independent samples t-test may be more appropriate. If the research question instead asks whether pass/fail status is associated with teaching method, the categorical structure makes a chi-square approach potentially suitable.
Choosing the analysis should therefore begin with the research question and variable types. Epic Essay's guide to quantitative thesis research and data analysis explains that statistical techniques should align with the research design, variables, and hypotheses rather than being selected simply because they are available in statistical software.
What Are the Assumptions of the Chi-Square Test?
The chi-square test does not require normally distributed continuous data because it analyses categorical frequencies. This does not mean that it is assumption-free. The validity of the test still depends on the sampling structure, independence of observations, and the adequacy of expected cell frequencies.
Independence means that each observation should contribute appropriately to the contingency table without the same participant being treated as multiple independent cases in a design that does not support this. For example, using the same respondents' before-and-after categorical responses as though they came from two unrelated groups would violate the independence structure. A procedure for related categorical data, such as McNemar's test in an appropriate two-category paired design, addresses a different research situation.
Expected frequencies also matter because the Pearson chi-square approximation becomes less reliable when cells are too sparse. IBM's current chi-square documentation states that expected frequencies should be at least 1 and that no more than 20% of categories should have expected frequencies below 5. For contingency-table analysis, researchers should inspect the expected-count information supplied with the chi-square output rather than assuming that a large overall sample automatically guarantees adequate cells.
The main issues to check are therefore:
- The variables are categorical and match the research question.
- The observations are independent under the study design.
- The data represent frequency counts rather than inappropriate continuous measurements.
- The expected cell frequencies are sufficiently large for the intended Pearson chi-square approximation.
- Categories have been coded correctly and missing values have been handled transparently.
These considerations belong in the analytical methodology rather than being treated as an afterthought. A statistically significant output cannot repair a design that does not satisfy the structure required by the test.
Observed vs Expected Frequencies in a Chi-Square Test
Understanding observed and expected frequencies makes chi-square interpretation much easier. Observed frequencies are simply the numbers of cases actually found in each cell of the crosstabulation. Expected frequencies are the counts that would be expected in those cells if the row and column variables were independent, given the marginal totals in the table.
IBM's Crosstabs documentation explains that SPSS can display both observed and expected values. It can also calculate residuals showing the difference between them. A positive residual means that more cases were observed than expected under independence, while a negative residual means fewer cases were observed than expected.
Consider a simplified hypothetical table comparing study mode and preferred assessment format.
| Study Mode | Examination | Coursework | Mixed Assessment | Total |
|---|---|---|---|---|
| Online | 18 | 47 | 35 | 100 |
| Campus | 39 | 28 | 33 | 100 |
| Total | 57 | 75 | 68 | 200 |
The pattern suggests that online students select coursework more frequently, while campus students select examinations more frequently. Pearson's chi-square evaluates whether deviations such as these are sufficiently large, across the entire table, to provide statistical evidence against independence.
How to Run a Chi-Square Test in SPSS Step by Step
For a test of independence, IBM provides the Crosstabs procedure under Analyze > Descriptive Statistics > Crosstabs. One categorical variable is placed in the rows and the other in the columns. The choice of which variable occupies which dimension does not change the Pearson chi-square significance test, although it affects how row and column percentages are read.
After defining the table, the Statistics options allow the researcher to request Chi-square and association measures such as Phi and Cramér's V. The Cells options can display observed counts, expected counts, row percentages, column percentages, and residuals. Requesting these values makes the output substantially more informative than generating the chi-square statistic alone.
A practical SPSS workflow is:
- Check that both variables are coded as meaningful categorical variables.
- Inspect category labels, missing values, and sample frequencies.
- Select Analyze > Descriptive Statistics > Crosstabs.
- Place one categorical variable in Rows and the other in Columns.
- Select Statistics and request Chi-square.
- Request Phi and Cramér's V when an association-size measure is relevant.
- Select Cells and request observed and expected counts.
- Request row or column percentages according to the comparison being made.
- Request residuals or adjusted standardized residuals when cell-level patterns need investigation.
- Run the analysis and interpret the crosstabulation before the significance table.
This workflow encourages researchers to understand the data pattern instead of jumping immediately to the p-value. SPSS output is most useful when the crosstabulation, assumptions, significance test, and association measure are interpreted as parts of one analysis.
How to Interpret the SPSS Crosstabulation Table
The crosstabulation is the descriptive foundation of the chi-square analysis. Counts show how many observations occupy each combination of categories, while percentages help compare groups whose totals may differ. Depending on the research question, row percentages or column percentages may provide the clearest description.
Suppose 47% of online students prefer coursework compared with 28% of campus students, while 18% of online students prefer examinations compared with 39% of campus students. These percentages provide a substantive description of the pattern. The chi-square test then evaluates whether the overall differences are statistically compatible with independence.
Researchers should avoid reporting percentages without identifying their denominator. Saying "47% preferred coursework" can be ambiguous if readers do not know whether 47% refers to online students, all coursework-preferring students, or the entire sample. Clear academic writing states whether percentages are calculated across rows, down columns, or across the total sample.
The crosstabulation should therefore be interpreted before inferential conclusions are written. Statistical significance can indicate that an association exists, but the table explains what that association actually looks like.
How to Check Expected Cell Counts in SPSS
The Chi-Square Tests table in SPSS includes information about expected counts, and the Cells options can display the expected value for each individual cell. These values need to be examined because sparse expected frequencies can make the asymptotic Pearson chi-square approximation unreliable.
A commonly applied rule is that no expected count should be below 1 and no more than 20% of expected counts should be below 5. This rule should be checked against the requirements of the specific analysis and course guidance. Simply reporting that the total sample contains 300 participants does not establish that the assumption is satisfied because some combinations of rare categories may still contain very small expected frequencies.
When the problem occurs in a 2 × 2 table, IBM's Crosstabs procedure can provide Fisher's exact test under relevant conditions. Sparse larger tables may require more careful decisions, such as an appropriate exact or Monte Carlo approach where available, collecting more data, or defensibly combining categories when the categories genuinely represent a coherent construct.
Do not combine categories merely to make the chi-square assumption pass. Any category restructuring should be substantively defensible and preferably determined by the research design rather than invented after examining the significance result.
How to Interpret the Pearson Chi-Square Value and p-Value
The Chi-Square Tests table normally contains several statistics, including Pearson Chi-Square, likelihood ratio, and, in some designs, additional tests. For a standard chi-square test of independence where its assumptions are appropriate, Pearson Chi-Square is typically the principal statistic reported.
The Pearson statistic measures the accumulated discrepancy between observed and expected frequencies across the contingency table, with each discrepancy considered relative to its expected frequency. Larger discrepancies generally produce a larger chi-square statistic. However, the raw chi-square value is interpreted together with the degrees of freedom rather than against a universal threshold.
The p-value evaluates the null hypothesis that the row and column variables are independent. If the pre-specified significance level is .05 and p is below .05, the analysis provides evidence against independence. If p is above .05, there is insufficient statistical evidence to reject independence at that threshold.
A significant chi-square result does not mean that one categorical variable causes the other. The test establishes evidence of association, while causal interpretation depends on the research design and cannot be inferred from a cross-tabulation alone.
How to Calculate and Interpret Degrees of Freedom
Degrees of freedom for a standard chi-square test of independence depend on the dimensions of the contingency table. For a table containing r rows and c columns, the degrees of freedom are calculated as (r - 1)(c - 1). A 2 × 3 table therefore has (2 - 1)(3 - 1) = 2 degrees of freedom.
This value appears in the SPSS Chi-Square Tests table and should normally be included in the academic write-up. Reporting the degrees of freedom helps identify the structure of the statistical test and is part of standard inferential reporting.
For example, a result might be reported as χ²(2) = 14.36, p < .001. The 2 inside parentheses represents the degrees of freedom rather than the sample size. The total number of valid observations can be reported separately where relevant.
Students should generally take the final degrees of freedom from the correct SPSS output rather than relying only on manual calculation, particularly when categories have been excluded because of missing values or other data-handling decisions.
What Does a Significant Chi-Square Result Actually Tell You?
A significant Pearson chi-square result indicates evidence that the variables are not statistically independent. In practical terms, the distribution of one categorical variable varies across categories of the other variable more than would be expected under the null model. It does not automatically reveal which cells account for the association.
This distinction becomes increasingly important as contingency tables grow. A 4 × 5 table contains 20 cells, and a significant omnibus chi-square statistic summarises discrepancies across all of them. Researchers therefore need to return to the crosstabulation, percentages, and residuals to understand the structure of the association.
Statistical significance also says little by itself about the strength of the relationship. With a very large sample, relatively modest differences in proportions can produce a small p-value. Measures such as Cramér's V help address this limitation by providing information about association magnitude.
Use Pearson's chi-square to determine whether there is evidence of association, the crosstabulation and residuals to understand its pattern, and an appropriate association measure to describe its strength.
How to Use Residuals to Understand a Significant Chi-Square Test
Residuals help identify cells in which observed counts differ from expected counts. IBM's Crosstabs procedure can provide raw residuals, standardized residuals, and adjusted standardized residuals. A positive residual indicates more observations than expected under independence, whereas a negative residual indicates fewer.
Standardized or adjusted standardized residuals put discrepancies onto a standardised scale, making unusually large departures easier to identify. This can be especially useful when the overall table contains several categories and the researcher wants to understand which combinations contribute most strongly to the association.
Residual interpretation should nevertheless be performed carefully because examining many cells introduces a multiple-comparison issue. Researchers should follow the inferential strategy required by their discipline rather than treating every residual beyond an informal threshold as a separate confirmed discovery.
The descriptive pattern should also remain visible. If online students appear more frequently than expected in the coursework cell and less frequently than expected in the examination cell, the percentages and residuals together provide a clearer explanation than simply writing that the chi-square test was significant.
How to Interpret Cramér's V and Phi in SPSS
Once an association has been examined, researchers often need to consider its magnitude. IBM's Crosstabs statistics include Phi and Cramér's V, both of which are based on the chi-square statistic. Phi is especially familiar for 2 × 2 tables, while Cramér's V provides a rescaled measure suitable for larger contingency tables.
IBM explains that Cramér's V is scaled so that its maximum possible value is 1. Values nearer zero indicate weaker association, while larger values indicate stronger association within the constraints of the table. However, the substantive meaning of a particular value depends on the variables, table dimensions, research context, and disciplinary conventions.
Students sometimes apply universal small, medium, and large labels without considering context. Such labels can be useful as rough conventions where explicitly justified, but they should not replace substantive interpretation. A seemingly modest association can still be important in public health or large-scale policy contexts, while a larger association may have limited practical meaning in another setting.
| SPSS Output | Question It Helps Answer |
|---|---|
| Crosstabulation counts | How are cases distributed across category combinations? |
| Row or column percentages | How do category proportions differ between groups? |
| Expected counts | Are the expected-frequency conditions adequate? |
| Pearson Chi-Square | Is there statistical evidence that the variables are associated? |
| Residuals | Which cells depart from the pattern expected under independence? |
| Phi or Cramér's V | How strong is the association? |
Interpreting these outputs together creates a much richer result than reporting the Pearson p-value alone. The test, descriptive pattern, and association magnitude answer different but complementary questions.
Chi-Square Test in SPSS Interpretation Example
Consider the hypothetical study of 200 students presented earlier. Study mode has two categories, online and campus, while assessment preference has three categories, examination, coursework, and mixed assessment. The descriptive table suggests different preference patterns between the two study modes.
Suppose SPSS reports Pearson χ²(2) = 14.36, p < .001. Assume that none of the expected cell counts is below 5, so the expected-frequency condition is adequately satisfied for this example. The result provides statistical evidence of an association between study mode and assessment preference.
Suppose Cramér's V is .268. This provides a standardised indication of the strength of association, which should be interpreted in the context of the study rather than solely through a generic label. The crosstabulation further shows that online students have a higher proportion choosing coursework, while campus students have a higher proportion choosing examinations.
| Output | Hypothetical Result | Interpretation |
|---|---|---|
| Pearson Chi-Square | 14.36 | Observed and expected frequencies differ across the table |
| Degrees of freedom | 2 | Based on a 2 × 3 contingency table |
| p-value | < .001 | Evidence against independence at alpha = .05 |
| Expected counts | None below 5 | Expected-frequency condition adequately satisfied in this example |
| Cramér's V | .268 | Standardised measure of association strength |
The correct interpretation therefore combines statistical significance, strength, and pattern. Writing only "there was a significant relationship" would omit much of the information needed for readers to understand what the relationship actually represents.
How to Report a Chi-Square Test in a Dissertation
A strong results paragraph normally identifies the variables, reports the chi-square statistic and degrees of freedom, provides the sample size where appropriate, gives the p-value, and describes the direction or pattern of association. Cramér's V or Phi can be added when an effect-size or association-strength measure is required.
Using the hypothetical example, a concise write-up could state: "A chi-square test of independence indicated a statistically significant association between study mode and assessment preference, χ²(2, N = 200) = 14.36, p < .001, Cramér's V = .268. Online students showed a higher proportion of coursework preference, whereas campus students showed a higher proportion of examination preference."
This reporting style communicates both the inferential result and the substantive pattern. It is more informative than copying the entire SPSS Chi-Square Tests table into the main text. Epic Essay's guide to presenting thesis results clearly similarly distinguishes objective statistical reporting from the broader interpretation that belongs in the discussion.
If the assignment requires a table, the crosstabulation can be reformatted into a concise academic table showing frequencies and relevant percentages. Raw SPSS output should not automatically replace a carefully presented results table, particularly when the software output contains statistics that are not discussed in the dissertation.
How to Report a Non-Significant Chi-Square Result
Non-significant results should be reported as carefully as significant ones. Suppose a study examining programme type and preferred study location produces χ²(2, N = 180) = 1.84, p = .399. At an alpha level of .05, the analysis does not provide sufficient evidence to reject the null hypothesis of independence.
A suitable write-up might state: "A chi-square test of independence found no statistically significant association between programme type and preferred study location, χ²(2, N = 180) = 1.84, p = .399." Descriptive percentages can still be presented if they are relevant, provided the writer does not portray small sample differences as established population associations.
It would be incorrect to conclude that the variables are "completely unrelated" or that the null hypothesis has been proved. A non-significant result indicates that the available data did not provide sufficient evidence against independence under the test and chosen threshold. The precision and power of the study still depend on sample size and the distribution of observations across cells.
Do not translate p greater than .05 into proof that two categorical variables have no relationship whatsoever. Report the evidence accurately without making a stronger claim than the test supports.
What to Do When Expected Cell Counts Are Too Small
Small expected counts require attention because the usual Pearson chi-square p-value relies on an approximation whose performance can deteriorate in sparse tables. The first step is to identify how many cells are affected and whether the problem results from genuinely rare categories, a small sample, or unnecessary fragmentation of the data.
For a 2 × 2 table, Fisher's exact test is an established alternative under sparse conditions, and IBM's Crosstabs procedure provides it for relevant 2 × 2 analyses. For larger contingency tables, exact or Monte Carlo methods may be available depending on the SPSS installation and analytical context. Researchers should use a method appropriate to the table rather than assuming Fisher's 2 × 2 procedure automatically solves every sparse-table problem.
Combining categories can sometimes be substantively reasonable. For example, two response options may represent the same theoretically justified broader category. However, categories should not be merged solely because doing so changes the p-value or removes an assumption warning.
The issue should also be reported transparently when it materially affects the analysis. Readers need to understand how the categories and statistical method were determined, particularly in dissertation research where analytical decisions contribute to the credibility of the findings.
Common Chi-Square Interpretation Mistakes in SPSS
A frequent mistake is using chi-square with inappropriate variables. Pearson's chi-square test of independence is designed for categorical frequency data, not for comparing continuous means. Researchers should identify the measurement level and research question before choosing the test.
A second mistake is ignoring the expected-count information. A small p-value can look convincing, but the validity of its usual interpretation depends on the conditions of the test. Expected frequencies should therefore be checked before the Pearson result is reported confidently.
Students also commonly report significance without explaining the association. A statement such as "gender and product preference were significantly associated, p = .002" tells the reader that evidence of association was found but not which preferences were more common in which categories. Crosstab percentages and, where appropriate, residuals are needed to explain the pattern.
Finally, association is often mistaken for causation. A statistically significant chi-square test does not demonstrate that one variable caused changes in the other. Causal conclusions require an appropriate research design and cannot be created by statistical significance alone.
How to Discuss Chi-Square Results Without Repeating the Results Section
The results section establishes the statistical evidence, whereas the discussion explains why the pattern matters. Once the chi-square result, relevant percentages, and association measure have been reported, the discussion can connect the finding to the research question, theory, and previous empirical studies.
For example, if online students show a stronger preference for coursework than campus students, the discussion might consider whether flexibility, assessment design, digital learning experience, or differences in student characteristics provide plausible explanations. These interpretations should be supported by relevant literature rather than invented from the statistical result itself.
Epic Essay's guide to dissertation findings and discussion explains that findings present the evidence while discussion develops its meaning in relation to existing scholarship. Maintaining this distinction prevents the discussion from becoming a repetition of p-values and percentages.
The discussion should also recognise limitations. A significant association found in a cross-sectional survey, for example, may support a relationship between variables without establishing temporal order or causation. The language of the discussion should remain consistent with what the research design can legitimately support.
A Step-by-Step Checklist for Interpreting Chi-Square Output in SPSS
Using a consistent interpretation sequence reduces the risk of reporting the wrong statistic or overlooking an assumption problem. Begin with the research question and variables, move through the crosstabulation and expected frequencies, and only then interpret the inferential test and association magnitude.
A practical checklist is:
- Confirm that the research question concerns categorical frequencies or an association between categorical variables.
- Determine whether you need a test of independence or a goodness-of-fit test.
- Check category coding, missing values, and the independence of observations.
- Inspect the crosstabulation and relevant row or column percentages.
- Request and examine expected cell frequencies.
- Confirm that the conditions for the planned Pearson chi-square analysis are sufficiently satisfied.
- Read the Pearson Chi-Square statistic and degrees of freedom.
- Interpret the p-value against the pre-specified significance level.
- If significant, examine percentages and appropriate residuals to understand the pattern.
- Report Phi or Cramér's V when an association-strength measure is appropriate.
- Use an appropriate alternative when sparse expected counts undermine the planned test.
- Write the result in relation to the research question without implying causation unless the design supports it.
This process keeps statistical significance in context. It also makes the transition from SPSS output to an academic results paragraph much easier because the researcher has already identified the pattern, checked the assumptions, and determined what the test actually supports.
Interpreting and Reporting Chi-Square Results in SPSS Correctly
A chi-square test in SPSS is most informative when it is treated as an analysis of categorical patterns rather than as a search for a p-value below .05. The crosstabulation shows what happened in the sample, expected frequencies establish the pattern anticipated under independence, and Pearson's chi-square evaluates whether the discrepancies provide statistical evidence of association.
A complete interpretation goes further by examining which categories account for the pattern and how strong the association appears to be. Percentages and residuals help explain the structure of the relationship, while Phi or Cramér's V can provide an association-size measure. Expected cell counts must also be checked before the usual Pearson result is accepted without qualification.
The final dissertation write-up should report the chi-square statistic, degrees of freedom, sample size where appropriate, p-value, association measure when required, and a concise description of the observed pattern. When these elements are interpreted together and the distinction between association and causation is maintained, chi-square analysis becomes a transparent and academically defensible way to answer research questions involving categorical data.
Comments