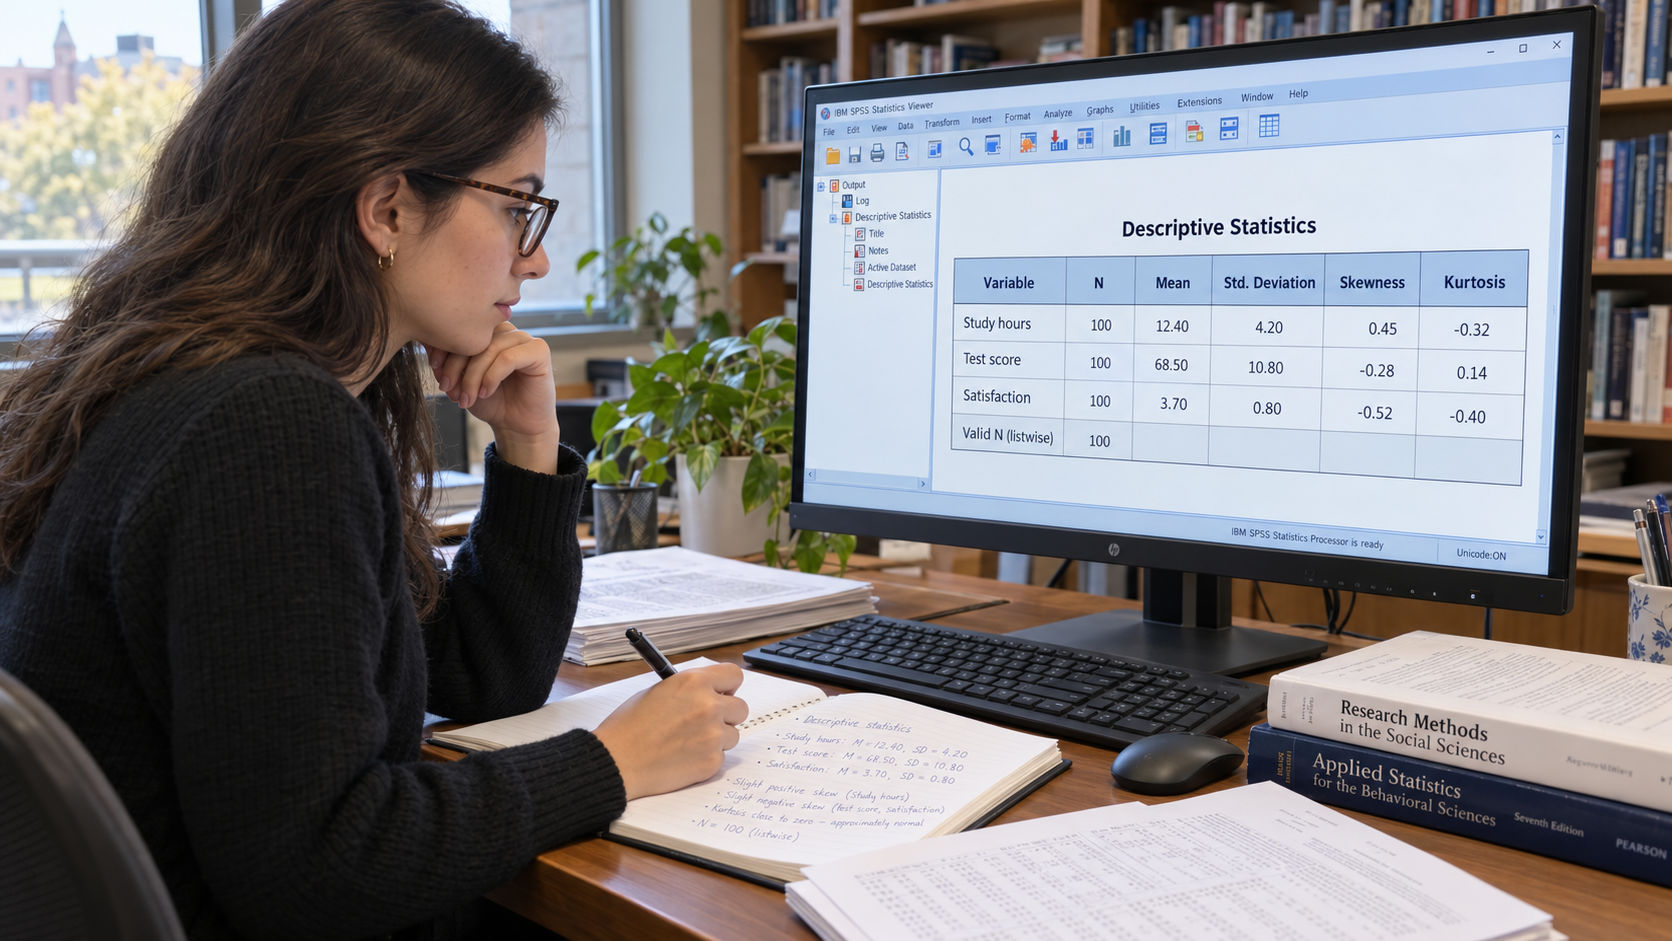
Statistical analysis should begin with understanding the data rather than immediately testing hypotheses. Before running correlations, t-tests, ANOVA, regression, or other inferential procedures, researchers need to know what their variables look like, where observations tend to cluster, how widely values vary, and whether unusual distributional features are present. Descriptive statistics provide this first systematic view of a quantitative dataset.
In SPSS, descriptive statistics can summarise variables using measures such as the mean, median, standard deviation, minimum, maximum, skewness, and kurtosis. These statistics answer different questions. The mean and median describe central tendency, standard deviation describes variability, while skewness and kurtosis provide information about distributional shape. IBM's SPSS documentation also identifies these measures among the statistics available through its descriptive and Explore procedures.
For dissertation students, the challenge is usually not obtaining these numbers but interpreting them correctly. A mean of 3.84, standard deviation of 0.71, or skewness of -0.62 means little unless it is interpreted in relation to the variable, its measurement scale, and the research purpose. This guide explains descriptive statistics in SPSS step by step, showing how to interpret mean, median, standard deviation, skewness, and kurtosis without relying on oversimplified statistical rules.
What Are Descriptive Statistics in SPSS?
Descriptive statistics are numerical summaries used to describe the characteristics of observed data. They do not, by themselves, test hypotheses about a wider population. Instead, they help researchers understand the sample and variables they have collected before deciding what further analysis is appropriate.
This distinction between descriptive and inferential analysis is important in quantitative research. Epic Essay's guide to quantitative thesis research and data analysis explains that descriptive statistics summarise characteristics such as averages and standard deviations, whereas inferential statistics are used to test hypotheses and make broader statistical inferences. Descriptive analysis therefore provides an important foundation rather than a substitute for inferential testing.
SPSS offers several routes for obtaining descriptive information. Analyze > Descriptive Statistics > Descriptives can provide common numerical summaries, while Analyze > Descriptive Statistics > Explore offers a broader examination that can include the mean, median, standard deviation, percentiles, skewness, kurtosis, histograms, boxplots, and normality-related outputs. The appropriate procedure depends on what information the researcher needs.
Descriptive statistics answer the question "What does this dataset look like?" before inferential statistics address questions about relationships, differences, predictions, or wider populations.
How to Run Descriptive Statistics in SPSS
Before requesting statistics, check how the variables have been defined. A numerical code does not automatically make a variable continuous. For example, coding employment status as 1 for employed and 2 for unemployed creates numerical values, but the variable remains categorical and calculating its mean would usually have little substantive meaning.
For suitable numerical variables, SPSS provides different procedures depending on the required output. The Descriptives procedure is useful for obtaining statistics such as the mean and standard deviation efficiently across several variables. The Explore procedure is particularly useful when researchers want the median, distributional statistics, plots, or a more detailed examination of individual variables.
A practical route for a detailed descriptive analysis is:
- Open the dataset and verify variable definitions and missing-value settings.
- Select Analyze > Descriptive Statistics > Explore.
- Move the quantitative variable or variables into the Dependent List.
- Add a factor variable if descriptive results need to be examined separately across groups.
- Use Statistics to request the required descriptive measures.
- Use Plots where histograms, boxplots, or related distributional diagnostics are useful.
- Run the analysis and interpret the output in relation to the measurement scale and research question.
The SPSS output may contain considerably more information than a dissertation requires. Researchers should report statistics because they help readers understand the data, not because SPSS happened to produce them. Selecting and explaining the most relevant output is part of statistical analysis.
How to Interpret the Mean in SPSS
The mean is the arithmetic average of a set of numerical observations. It is calculated by adding all observed values and dividing the total by the number of valid observations. In SPSS output, the mean provides a concise description of the central location of a quantitative variable when an average is meaningful for that variable.
Suppose 150 university students complete a study-engagement scale scored from 1 to 5 and the SPSS output reports a mean of 3.72. The sample's average engagement score is therefore 3.72. Interpretation should remain connected to the scale: if higher values represent greater engagement, the result indicates where the sample is centred on that measurement rather than proving that engagement is objectively "high."
The mean uses every observation and is consequently sensitive to extreme values. Consider income data in which most participants earn relatively similar amounts but a few respondents have exceptionally high incomes. Those high observations can pull the mean upward, making it less representative of what a typical participant earns.
This sensitivity is why the mean should not always be interpreted in isolation. Examining the median, histogram, boxplot, minimum and maximum values, and distributional shape can reveal whether the mean provides a useful summary. The choice of descriptive statistic should reflect the data rather than a rule that the mean must always be reported.
How to Interpret the Median in SPSS
The median is the middle value after observations have been arranged from lowest to highest. Approximately half of the observations lie below it and half lie above it. Because its position is more important than the magnitude of every observation, the median is generally less influenced by extreme values than the mean.
This property makes the median particularly informative for skewed distributions. Suppose monthly household income has a mean of 4,800 units but a median of 3,200 because a small number of very high-income observations pull the mean upward. Reporting only the mean could create an incomplete impression of the typical observation, whereas the median reveals the centre based on the ordering of cases.
The relationship between the mean and median can therefore provide useful descriptive information. In a reasonably symmetric unimodal distribution, they may be relatively close. In a strongly skewed distribution, they can differ considerably because the mean is affected more strongly by observations in a long tail.
However, the mean-median difference should not be used as a complete test of distributional form. Histograms, boxplots, skewness measures, and knowledge of the variable should also be considered. The National Institute of Standards and Technology notes that measures of centre represent different aspects of a distribution and can provide complementary information, especially when data are skewed.
Mean vs Median: Which Should You Report?
The appropriate measure of central tendency depends on the variable and the shape of the observed data. For many approximately symmetric continuous variables without influential extreme values, the mean provides a useful summary and works naturally with the standard deviation. For substantially skewed data, the median may communicate the centre more robustly and is often considered alongside the interquartile range.
The measurement scale also matters. A mean is meaningful only when numerical differences can be interpreted appropriately. For ordinal responses, such as a single Likert item, researchers should recognise that categories represent an ordering and that the interpretation of numerical averages involves additional assumptions. Multi-item scale scores are often treated differently when their construction and measurement properties justify it.
The following comparison helps clarify the roles of these statistics.
| Feature | Mean | Median |
|---|---|---|
| What it represents | Arithmetic average of observations | Middle ordered observation |
| Uses magnitude of every value | Yes | No |
| Sensitivity to extreme observations | Relatively sensitive | More resistant |
| Often useful for | Suitable approximately symmetric quantitative data | Skewed quantitative data or ordered data where a positional summary is appropriate |
| Common companion measure | Standard deviation | Interquartile range |
Researchers should therefore avoid choosing the mean or median solely because one produces a more attractive result. The descriptive measure should represent the data faithfully and match the type of variable being analysed.
How to Interpret Standard Deviation in SPSS
Standard deviation, usually abbreviated as SD, measures how dispersed observations are around the mean. A smaller SD indicates that observations tend to be relatively concentrated around the mean, while a larger SD indicates greater spread. Unlike variance, which is expressed in squared units, standard deviation is expressed in the original measurement units, making it easier to interpret substantively.
Suppose two groups both have a mean satisfaction score of 4.0 on the same scale. Group A has SD = 0.35, whereas Group B has SD = 1.10. Although their means are identical, responses in Group A are much more tightly concentrated around 4.0, while Group B contains considerably greater variation in satisfaction.
The size of a standard deviation has no universal interpretation without reference to the measurement scale. An SD of 5 could represent very little variability for a variable ranging from 0 to 1,000 but impossible variability for a scale bounded from 1 to 5. Students should therefore interpret dispersion relative to the variable's units, range, and substantive context.
For a normal distribution, observations follow familiar proportions around the mean, but researchers should not apply those proportions automatically to strongly non-normal data. Standard deviation remains a measure of spread, yet its interpretation should be considered alongside distributional shape and possible outliers.
How to Interpret Skewness in SPSS
Skewness describes asymmetry in a distribution. A symmetric distribution has skewness near zero. Positive skewness indicates a relatively longer right tail, whereas negative skewness indicates a relatively longer left tail, a convention also described by the NIST guidance on skewness and kurtosis.
Positive skewness commonly occurs when most observations are relatively low but a smaller number extend toward much higher values. Income, waiting times, and expenditure variables can show this pattern. The mean may be pulled toward the long right tail and can therefore be higher than the median in many positively skewed distributions.
Negative skewness describes the reverse pattern: most observations occur toward the higher end while a smaller number extend toward lower values. For example, scores on an easy examination could cluster near the upper limit while a small number of low scores form a left tail. The mean can then be pulled downward relative to the median.
The basic interpretation can be summarised as follows.
| Skewness Result | General Shape | Interpretation |
|---|---|---|
| Near 0 | Approximately symmetric | Neither tail is strongly longer than the other based on skewness alone |
| Positive | Right-skewed | The distribution has a relatively longer right tail |
| Negative | Left-skewed | The distribution has a relatively longer left tail |
The magnitude of skewness requires more care than the sign. Rules such as treating values within ±1 or ±2 as automatically "normal" appear frequently in student work, but they are not universal laws. Sample size, the planned statistical model, outliers, graphical evidence, and the assumptions of the subsequent analysis all affect whether observed skewness is consequential.
How to Interpret Kurtosis in SPSS
Kurtosis provides information about distributional shape, particularly tail behaviour and the occurrence of extreme observations relative to a reference distribution. One source of confusion is that different statistical conventions report kurtosis differently. Some define a normal distribution as having kurtosis of 3, whereas software may report excess kurtosis, for which the normal-distribution reference is 0.
IBM SPSS reports kurtosis using a convention in which a normal distribution has a value of 0. Positive values indicate relatively heavier tails or more extreme outlier behaviour compared with a normal distribution, while negative values indicate lighter tails. This convention needs to be recognised before interpreting the number because comparing an SPSS value directly with a textbook using a normal reference of 3 would be misleading.
For example, an SPSS kurtosis value of 1.40 indicates positive excess kurtosis relative to the normal reference of zero. A value of -0.80 indicates negative excess kurtosis. Neither number should automatically be translated into a verdict that the data are usable or unusable for a particular statistical procedure.
Researchers should also be cautious with the traditional language of "peakedness." Modern interpretation places important emphasis on tail behaviour and extreme observations. A histogram and boxplot can therefore provide valuable context when a kurtosis statistic appears unusual.
In SPSS, the normal-distribution reference for the reported kurtosis statistic is 0. Always check the convention used by your software or source before interpreting kurtosis.
What Skewness and Kurtosis Values Are Acceptable?
Students frequently search for a single acceptable skewness and kurtosis range that proves normality. Although threshold rules can sometimes serve as rough screening conventions, no universal cut-off can determine whether every dataset is suitable for every analysis. The practical importance of distributional shape depends on the statistical procedure, sample size, model, variable, and severity of departures.
SPSS also reports standard errors for skewness and kurtosis in relevant procedures. IBM documentation notes that skewness or kurtosis can be considered relative to its standard error when assessing departure from symmetry or normal-distribution behaviour. However, with large samples even relatively small departures can become detectable, so a formal or standardised statistic should not replace graphical and substantive assessment.
Histograms, Q-Q or normal probability plots, and boxplots can reveal features that a single coefficient cannot show clearly. A distribution can have problematic outliers, multiple clusters, or other structure even when one summary statistic appears unremarkable. Conversely, a moderate numerical departure does not necessarily invalidate a statistical analysis that is robust under the conditions present.
Do not declare data "normally distributed" solely because skewness and kurtosis fall inside a memorised cut-off. Instead, explain the criteria used, examine graphical evidence, and evaluate the assumptions that apply to the specific inferential test or model you intend to run.
How Mean, Median, SD, Skewness and Kurtosis Work Together
No single descriptive statistic provides a complete picture of a quantitative variable. The mean describes arithmetic centre, the median describes positional centre, standard deviation describes spread around the mean, and skewness and kurtosis describe aspects of distributional shape. Interpreting them together provides considerably more information than reading each number independently.
Consider a hypothetical dissertation variable measuring weekly study hours among 200 students. Suppose SPSS reports mean = 14.60, median = 13.00, SD = 6.20, skewness = 0.92, and kurtosis = 0.48. The mean being somewhat higher than the median is consistent with the positive skewness, while the SD indicates substantial variation in study hours across participants.
Now consider a satisfaction scale with mean = 3.84, median = 3.90, SD = 0.61, skewness = -0.18, and kurtosis = -0.31. The close mean and median and small skewness suggest a relatively symmetric distribution based on these summaries. The moderate SD indicates that responses are not identical, while the kurtosis value is fairly close to SPSS's zero reference.
The table below demonstrates how these statistics might appear in a dissertation results table.
| Variable | Mean | Median | SD | Skewness | Kurtosis | Descriptive Interpretation |
|---|---|---|---|---|---|---|
| Weekly study hours | 14.60 | 13.00 | 6.20 | 0.92 | 0.48 | Variable responses with a positive right skew |
| Student satisfaction | 3.84 | 3.90 | 0.61 | -0.18 | -0.31 | Relatively symmetric based on these descriptive measures |
| Assessment anxiety | 2.41 | 2.20 | 0.88 | 0.67 | -0.12 | Some positive asymmetry with moderate dispersion |
These interpretations deliberately remain descriptive. Whether any variable satisfies the assumptions of a later t-test, ANOVA, regression model, or another inferential procedure requires additional assessment appropriate to that procedure.
How to Use Descriptive Statistics Before Inferential Testing
Descriptive analysis can reveal problems before they affect later statistical procedures. Minimum and maximum values may expose impossible coding, unusual values may reveal data-entry errors, and extreme skewness can indicate that the chosen summary or statistical model deserves closer examination. This makes descriptive analysis an important quality-control stage rather than merely a table inserted into a dissertation.
Researchers should also use descriptive results to guide subsequent statistical choices without allowing them to dictate those choices mechanically. The appropriate inferential procedure depends on the research question, variable types, study design, group structure, and test-specific assumptions. Descriptive statistics provide evidence relevant to those decisions but do not determine the entire analytical strategy.
For quantitative dissertations, this sequence should be reflected in the methodology. Epic Essay's guide to writing the dissertation methodology chapter explains that analytical techniques should be stated and justified in relation to the data and research questions. A coherent methodology can therefore explain that descriptive analysis was conducted first to summarise the sample and examine the distributions before specified inferential procedures were applied.
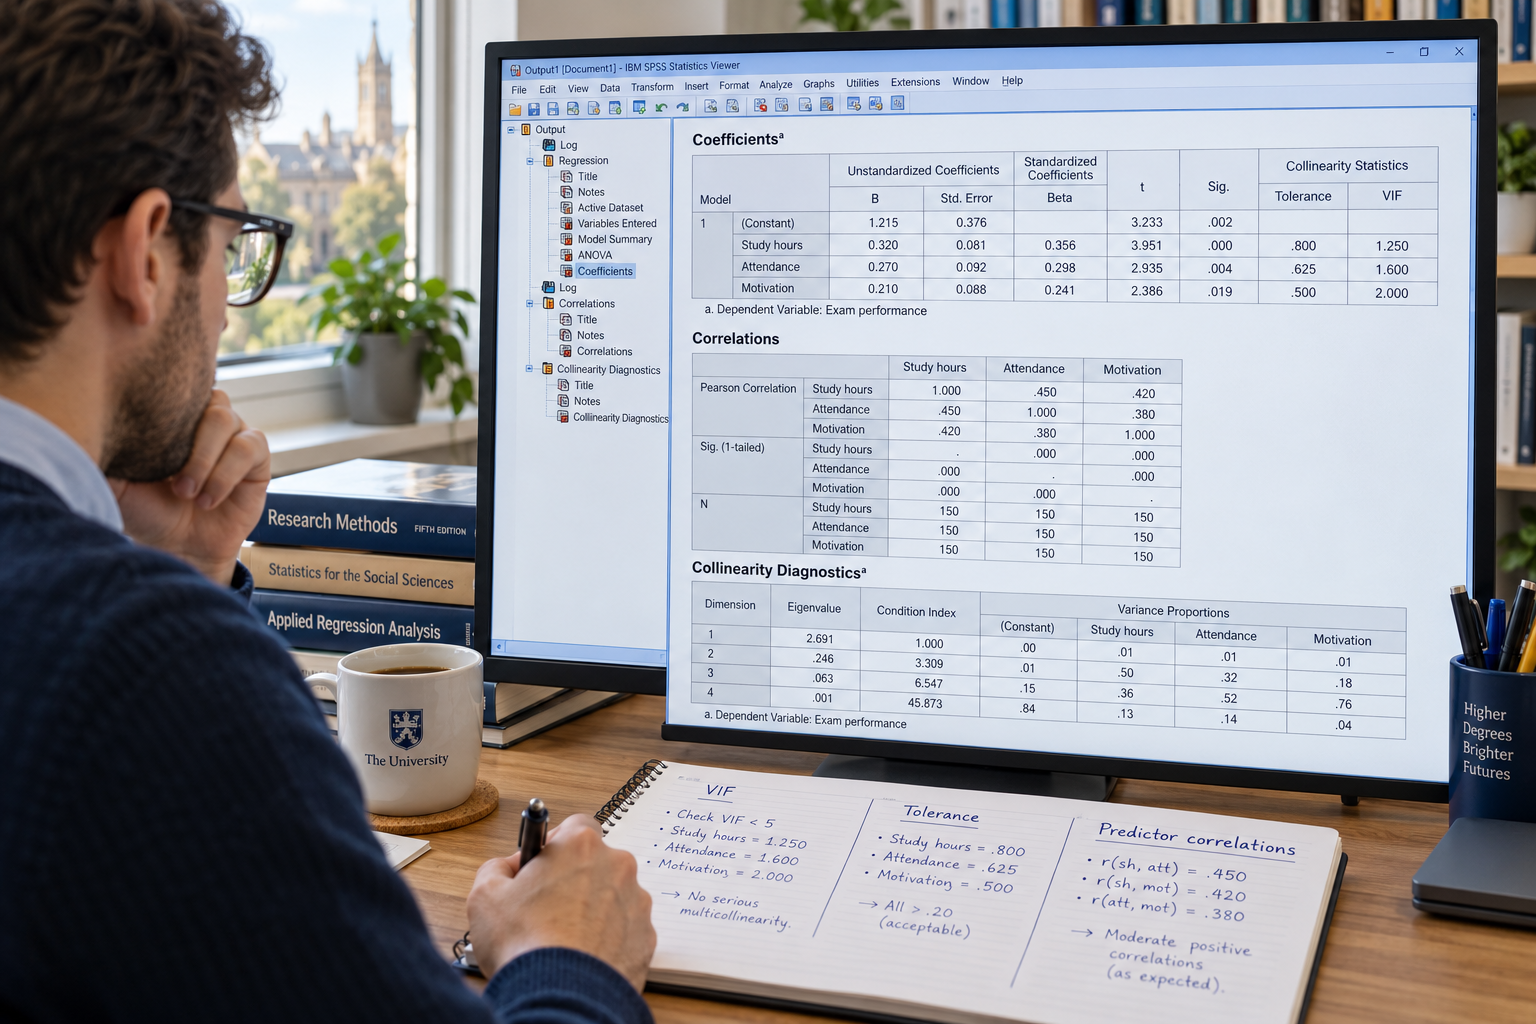
Where subsequent analysis involves more advanced modelling, students should avoid assuming that descriptive normality of every raw variable is always the relevant assumption. For example, regression diagnostics concern properties of the model and residuals in addition to characteristics of individual variables. The assumptions should be checked for the statistical procedure actually being used.
How to Report Descriptive Statistics in a Dissertation
A dissertation results chapter should present descriptive statistics selectively and clearly. Large blocks of raw SPSS output are rarely an effective substitute for academic presentation. Tables can summarise important measures, while the accompanying text should identify notable patterns rather than repeat every number already visible in the table.
Epic Essay's guide to presenting thesis results explains that findings should be organised clearly and presented objectively before detailed interpretation is developed. This is particularly relevant to descriptive statistics because students sometimes move from reporting a mean directly into unsupported explanations of why participants responded in a particular way.
A concise descriptive-results paragraph might state: "The student satisfaction scale had a mean score of 3.84 (SD = 0.61) and a median of 3.90. Skewness was -0.18 and kurtosis was -0.31, indicating little asymmetry and values relatively close to the normal-distribution reference on these descriptive measures." The wording reports the observed pattern without claiming more than the statistics establish.
The discussion chapter can later consider what those findings mean in relation to the research question and previous studies. Epic Essay's guide to dissertation findings and discussion distinguishes the presentation of statistical outcomes from their broader interpretation. Keeping these functions clear helps prevent the results chapter from becoming speculative.
Common SPSS Descriptive Statistics Mistakes
One common mistake is calculating and interpreting means for variables merely because they are stored as numbers in SPSS. Category codes such as 1 = Economics, 2 = Psychology, and 3 = Nursing do not have meaningful arithmetic distances. A mean programme code of 1.9 would therefore not describe an academically meaningful average programme.
A second mistake is interpreting standard deviation without reference to the scale. Writing that "SD = 0.8 shows low variability" is incomplete unless the reader understands the variable's possible values and substantive context. Dispersion is relative to the measurement system and observed distribution.
Students also frequently label data normal based on a single skewness or kurtosis threshold. Distributional assessment should combine numerical summaries with appropriate graphical diagnostics and should be linked to the assumptions of the intended statistical procedure. The aim is not to make every dataset look normal but to understand its characteristics accurately.
Finally, researchers sometimes paste complete SPSS output tables into dissertations without editing or explanation. SPSS output is designed for statistical analysis, not necessarily for academic communication. A dissertation should normally extract and organise the statistics readers need, label variables clearly, and explain the important descriptive patterns in the text.
A Practical SPSS Descriptive Statistics Interpretation Checklist
A systematic workflow reduces interpretation errors and makes the transition from SPSS output to dissertation writing easier. The process should begin with the variable itself rather than with the numbers displayed in the output. Researchers need to know what was measured before deciding which summary statistics are meaningful.
Use the following sequence when reviewing descriptive statistics:
- Confirm the measurement level and coding of each variable.
- Check the number of valid and missing observations.
- Inspect minimum and maximum values for impossible or suspicious values.
- Interpret the mean where an arithmetic average is substantively meaningful.
- Examine the median, particularly when the distribution may be skewed.
- Interpret standard deviation relative to the variable's scale and mean.
- Check the sign and magnitude of skewness for asymmetry.
- Interpret SPSS kurtosis relative to its normal-distribution reference of zero.
- Inspect appropriate graphs, especially when distributional shape matters.
- Relate descriptive findings to the assumptions of the planned inferential analysis.
- Present selected statistics in a clear academic table rather than copying unnecessary output.
- Describe the observed results accurately before developing broader interpretation.
This approach makes descriptive statistics part of a coherent analytical process. It also reduces the risk of applying memorised rules without considering the variable, dataset, or research design.
Interpreting Descriptive Statistics in SPSS with Confidence
Descriptive statistics in SPSS provide the foundation for understanding quantitative data. The mean describes arithmetic centre, the median identifies the positional centre, standard deviation measures dispersion around the mean, skewness describes asymmetry, and kurtosis provides information about distributional tails and extreme observations relative to a reference distribution. These statistics become most informative when interpreted together rather than as isolated values.
Students should avoid turning descriptive analysis into a checklist of universal thresholds. Whether a mean is representative, an SD is large, or skewness and kurtosis are problematic depends on the variable, sample, distribution, and statistical analysis that follows. Graphical inspection and knowledge of the research design provide essential context for numerical summaries.
For dissertation reporting, present only the statistics that help readers understand the sample and variables, organise them clearly, and distinguish objective results from later interpretation. When descriptive analysis is completed carefully, it does more than produce a table of numbers: it reveals the structure of the dataset and provides a defensible foundation for the statistical decisions that follow.
Comments