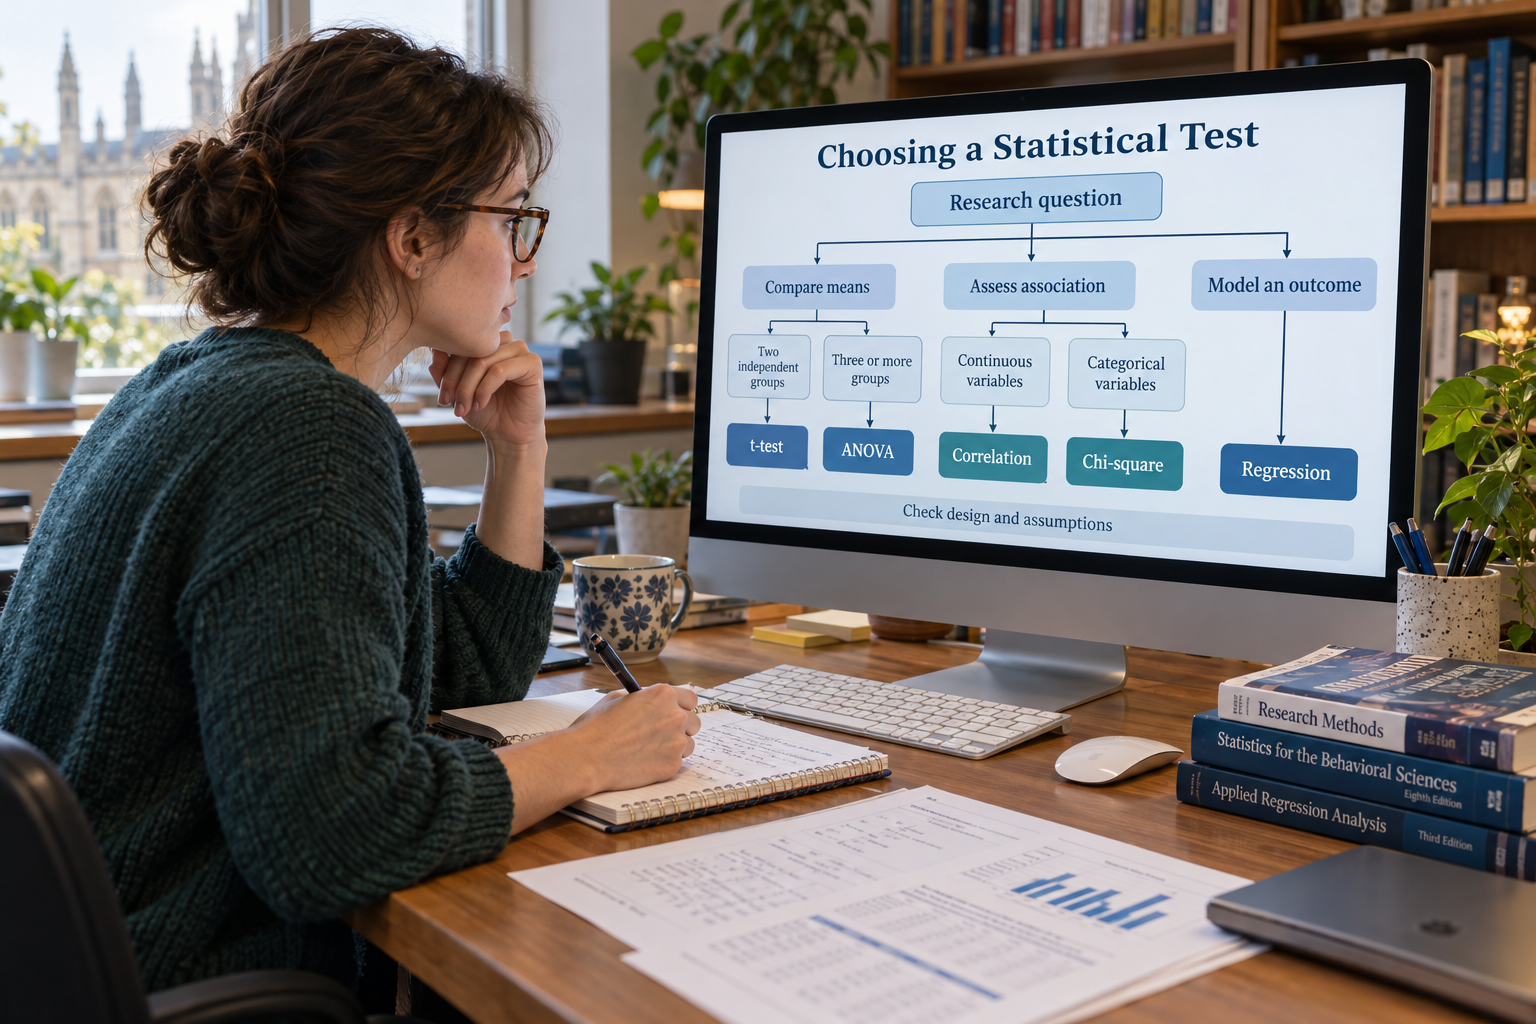
Choosing the right statistical test is one of the most important decisions in quantitative dissertation research. Statistical software can calculate a t-test, ANOVA, correlation, chi-square test, or regression model within seconds, but it cannot decide whether that procedure is appropriate for the research question and data. A technically correct calculation can still produce a methodologically weak dissertation if the wrong statistical test has been selected.
The decision should therefore begin before opening SPSS, R, Stata, Python, or another statistical package. Researchers need to establish what they are trying to test, identify the measurement level of their variables, determine whether observations or groups are independent or related, and examine the assumptions required by the proposed analysis. These decisions connect the statistical analysis directly to the research design.
This guide provides a practical framework for choosing statistical tests for dissertation research. It covers descriptive and inferential analysis, t-tests, ANOVA, chi-square tests, Pearson and Spearman correlation, regression, paired and independent designs, and common non-parametric alternatives. The aim is not to replace discipline-specific statistical guidance, but to help students understand the decision process that should occur before a test is selected.
Why Choosing the Right Statistical Test Matters in a Dissertation
A statistical test evaluates a particular type of question under particular conditions. Some procedures compare groups, others examine associations between variables, and others estimate how one or more predictors relate to an outcome. Selecting a test simply because it is familiar or appears frequently in previous dissertations reverses the correct methodological process.
The analytical strategy should instead follow from the research question and study design. Epic Essay's guide to the dissertation methodology chapter emphasises that analytical techniques should align with the type of data and research questions. This alignment allows an examiner to follow the reasoning from the research objective to the evidence and finally to the statistical procedure used to analyse it.
Different tests also make different assumptions about the data. The appropriate choice may depend on whether an outcome is continuous, ordinal, binary, or nominal; whether groups are independent or paired; and whether relevant distributional or model assumptions are adequately satisfied. The UCLA Statistical Methods and Data Analytics guide to choosing statistical tests similarly organises test selection around the number and nature of variables, measurement level, study structure, and relevant assumptions.
The correct statistical test is not the most sophisticated test available. It is the test that appropriately answers the research question using the variables and study design you actually have.
Start with the Research Question, Not the Statistical Software
The first decision is to identify what the research question asks statistically. A dissertation might ask whether two groups differ, whether several groups differ, whether two variables are associated, whether measurements change over time, or whether several variables predict an outcome. Each question represents a different analytical objective and narrows the range of potentially suitable tests.
For example, a researcher investigating whether average job satisfaction differs between remote and office-based employees has a group-comparison question. A researcher investigating whether working hours are related to job satisfaction has an association question. A third researcher examining whether working hours, salary, age, and management support jointly predict job satisfaction has moved towards a regression question.
The hypotheses should reflect the same logic. If a hypothesis proposes a difference between groups, the analysis must be capable of testing differences. If it proposes a relationship between variables, an association or regression procedure may be more appropriate. Statistical analysis becomes easier to justify when the research question, hypothesis, variables, and test all address the same analytical problem.
Before choosing a test, classify the purpose of the analysis into a broad category:
- Describing a sample or variable.
- Comparing two groups or conditions.
- Comparing three or more groups or conditions.
- Testing an association between categorical variables.
- Examining a relationship between numerical or ordinal variables.
- Predicting or explaining an outcome using one or more variables.
This classification does not determine the final test by itself, but it substantially reduces the possibilities. The next step is to examine the variables because the same research purpose can require different statistical procedures depending on how the data are measured.
Identify Your Variable Types Before Choosing a Statistical Test
Statistical tests operate on variables with particular measurement properties. A nominal variable places observations into categories without an inherent ranking, such as department or employment type. An ordinal variable contains ordered categories, while continuous or scale variables represent numerical measurements for which quantitative differences are meaningful within the context of the analysis.
The outcome variable is particularly important because its form often determines the family of statistical model that can be considered. A continuous outcome may support procedures such as t-tests, ANOVA, or linear regression when their assumptions are appropriate. A binary outcome may instead require methods such as logistic regression when the objective is prediction or modelling.
Students should classify variables according to what they actually measure rather than how they happen to be coded in a dataset. Coding "male" and "female" as 0 and 1, for example, does not transform the variable into a continuous measurement. Numerical codes can represent categories without changing their underlying measurement properties.
The table below shows why identifying the research purpose and variable types should occur together.
| Research Purpose | Typical Data Structure | Common Test to Consider |
|---|---|---|
| Compare a continuous outcome between two independent groups | Continuous outcome, two independent groups | Independent-samples t-test |
| Compare a continuous outcome measured twice on the same participants | Continuous outcome, two related measurements | Paired-samples t-test |
| Compare a continuous outcome across three or more independent groups | Continuous outcome, three or more independent groups | One-way ANOVA |
| Test association between two categorical variables | Two categorical variables | Chi-square test of independence |
| Examine a linear relationship between two continuous variables | Two continuous variables | Pearson correlation |
| Examine a monotonic relationship involving ordinal or suitable non-normal data | Ordinal or ranked variables | Spearman rank correlation |
| Model a continuous outcome from one or more predictors | Continuous outcome with predictor variables | Linear regression |
| Model a binary outcome | Binary outcome with predictor variables | Binary logistic regression |
The table is a decision aid rather than an automatic selection tool. Each procedure has additional requirements, and more specialised designs may require techniques not included here. Students should therefore use the table to identify a candidate test and then check whether its assumptions and study-design requirements are satisfied.
When Should You Use an Independent-Samples t-Test?
An independent-samples t-test is commonly considered when a researcher wants to compare the mean of a continuous outcome between two independent groups. For example, a dissertation might compare mean academic engagement scores between students receiving face-to-face teaching and students receiving online teaching. The important structural features are one continuous outcome and two groups containing different observations or participants.
Independence matters because the observations in one group should not simply be repeated measurements of the observations in the other group. If the same students are measured before and after an intervention, the observations are paired rather than independent. Treating paired observations as independent ignores information about the relationship between measurements and changes the statistical problem.
The t-test also requires appropriate consideration of its assumptions. These include independence and assumptions relating to the distribution of the model and, depending on the version used, equality of variances. Students should not mechanically report that "the data were normal" without identifying what assumption is relevant to the analysis and how it was assessed.
If the data and research design do not support an independent t-test, an alternative such as the Mann–Whitney U test may be considered for an appropriate two-group comparison. However, non-parametric procedures should not be selected simply because a normality test produces a particular p-value. The nature of the variables, distributions, sample size, estimand, and purpose of the comparison should all inform the decision.
When Should You Use a Paired-Samples t-Test?
A paired-samples t-test is used for a different design: two measurements are related. The most familiar example is a before-and-after study in which the same participants provide a score before an intervention and another score afterwards. The analysis focuses on the differences within pairs rather than treating the two sets of observations as unrelated groups.
Paired data can also arise through matching. For example, researchers may deliberately match participants according to relevant characteristics and analyse the resulting pairs. The essential feature is that observations have a meaningful one-to-one relationship that the statistical analysis needs to preserve.
A common dissertation error is choosing between independent and paired t-tests based only on the number of groups displayed in SPSS. Both procedures involve two sets of measurements, but their study designs are fundamentally different. The correct question is whether the observations in one condition are statistically independent of, or meaningfully paired with, observations in the other.
Where the assumptions for a paired t-test are not appropriate, the Wilcoxon signed-rank test may be considered for suitable paired data. Again, the alternative should be selected because its statistical structure matches the data and research question, not merely because it is labelled "non-parametric."
When Should You Use ANOVA?
Analysis of variance, or ANOVA, is commonly used when researchers need to compare a continuous outcome across three or more groups. For example, a dissertation might investigate whether mean student satisfaction differs among face-to-face, hybrid, and fully online teaching formats. Conducting repeated pairwise t-tests would increase the risk of false-positive findings unless the multiple-comparison problem is addressed appropriately.
A statistically significant omnibus ANOVA indicates evidence that not all relevant group means are equal, but it does not by itself identify which specific groups differ. Where appropriate, researchers therefore need planned contrasts or post-hoc comparisons to investigate the location of the differences while controlling the relevant error rate. Reporting only the ANOVA p-value can leave the substantive research question incompletely answered.
ANOVA also has several forms. One-way ANOVA addresses one grouping factor, factorial ANOVA can examine multiple factors and their interactions, and repeated-measures ANOVA is designed for appropriate repeated observations. The study design must therefore be understood before choosing an option from a statistical software menu.
If an independent-groups comparison is ordinal or does not support the intended parametric procedure, the Kruskal–Wallis test may sometimes be considered as an alternative. For related measurements across three or more conditions, the Friedman test is a common non-parametric option. These tests answer related but not necessarily identical statistical questions, so switching between procedures should always be justified.
When Should You Use a Chi-Square Test?
The chi-square test of independence is commonly used to examine whether two categorical variables are associated. For example, a dissertation might investigate whether preferred learning format is associated with programme type, or whether employee turnover status is associated with employment category. Unlike a t-test or ANOVA, the analysis concerns frequencies or counts across categories rather than differences between numerical means.
The data are usually arranged in a contingency table showing the observed number of cases in each combination of categories. The chi-square procedure compares these observed counts with the counts expected if the variables were independent. A statistically significant result provides evidence of association, but it does not by itself establish causation or explain why the association exists.
Expected cell frequencies also matter. If expected counts are too small, the usual chi-square approximation may be unsuitable, and an exact procedure such as Fisher's exact test may be considered in appropriate settings. Researchers should therefore inspect the diagnostic information produced by their statistical software instead of reporting only the final p-value.
Students should also distinguish a chi-square test of independence from a chi-square goodness-of-fit test. The former examines the relationship between categorical variables, whereas the latter evaluates whether observed category frequencies differ from specified expected proportions. Similar names do not mean that the procedures answer the same research question.
When Should You Use Pearson or Spearman Correlation?
Correlation is appropriate when the research question concerns the relationship between variables rather than differences between groups. Pearson's correlation coefficient is commonly used to quantify the strength and direction of a linear relationship between two suitable continuous variables. A dissertation might, for example, investigate the relationship between weekly study hours and an academic performance measure.
Pearson correlation requires more than two columns of numerical data. Researchers should examine whether the relationship is approximately linear, whether influential outliers distort the association, and whether relevant assumptions for inference are satisfied. A weak Pearson correlation does not necessarily mean that no relationship exists because a strong nonlinear relationship can still produce a small linear correlation coefficient.
Spearman's rank correlation is commonly considered when variables are ordinal or when a monotonic relationship is of interest and Pearson's requirements are unsuitable. It is based on ranks and therefore answers a somewhat different statistical question. Choosing Spearman should be a reasoned methodological decision rather than an automatic response whenever a normality test is statistically significant.
Most importantly, correlation does not demonstrate causation. Two variables can be strongly associated because one influences the other, because the causal direction is reversed, because both are influenced by other factors, or because of features of the data and study design. A statistically significant correlation should never be described automatically as evidence that one variable causes another.
When Should You Use Regression Analysis?
Regression becomes useful when the research question concerns how an outcome relates to one or more predictors. Simple linear regression considers a continuous outcome and one predictor, while multiple linear regression can estimate associations involving several predictors simultaneously. This allows dissertations to address questions that go beyond whether two variables are correlated.
For example, a study may examine whether academic engagement is associated with study hours, perceived lecturer support, employment hours, and age. A multiple regression model can estimate each predictor's relationship with the outcome conditional on the other variables included in the model. However, including many predictors without theoretical justification does not automatically create a stronger analysis.
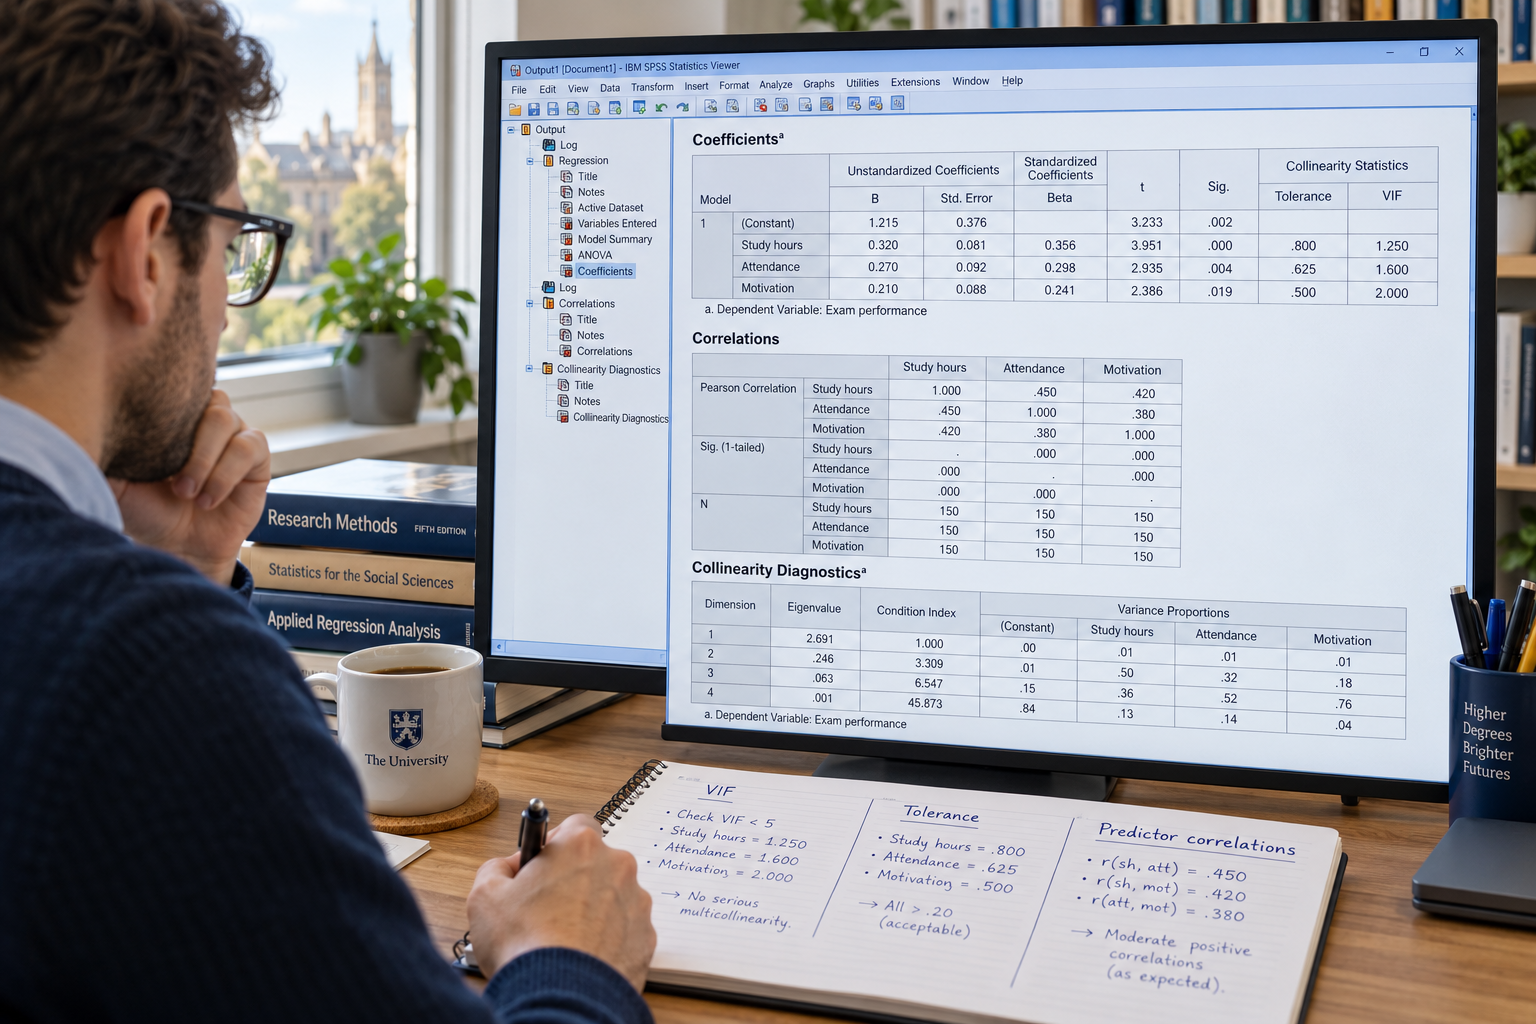
Linear regression has assumptions and diagnostic requirements involving matters such as functional form, independence, variance of residuals, influential observations, and the behaviour of model errors. The exact checks depend on the model and data. Students should therefore plan regression diagnostics as part of the analysis rather than treating regression as a single button that produces a coefficients table.
The outcome variable also determines the appropriate regression family. A binary outcome, such as whether a participant completed a programme, is not normally analysed using ordinary linear regression simply because predictors are numerical. Binary logistic regression is commonly used for binary outcomes, while other outcome structures can require other modelling approaches.
Parametric vs Non-Parametric Tests: How Should You Decide?
Students often encounter a simplified rule that "normal data require parametric tests and non-normal data require non-parametric tests." This can be misleading. Statistical assumptions apply differently to different models, and issues such as independence, measurement level, sample structure, outliers, residual behaviour, and variance can be as important as distributional shape.
Parametric procedures such as t-tests, ANOVA, Pearson correlation, and linear regression make assumptions that need to be considered in the context of the particular test. Non-parametric procedures can be valuable where their structure better matches the data or when important assumptions of a proposed parametric method are untenable. However, they are not assumption-free substitutes.
The following table shows several commonly discussed parametric procedures and related alternatives. These pairings are practical starting points rather than claims that the tests are mathematically interchangeable.
| Research Situation | Common Parametric Test | Common Alternative to Consider |
|---|---|---|
| Two independent groups | Independent-samples t-test | Mann–Whitney U test |
| Two related measurements | Paired-samples t-test | Wilcoxon signed-rank test |
| Three or more independent groups | One-way ANOVA | Kruskal–Wallis test |
| Three or more related measurements | Repeated-measures ANOVA | Friedman test |
| Association between suitable continuous variables | Pearson correlation | Spearman rank correlation |
The decision should be based on what the alternative procedure actually tests. For example, switching from a t-test to a rank-based procedure can change the interpretation of the comparison. Researchers should therefore explain why the chosen procedure matches both the research question and the characteristics of the data.
A Step-by-Step Statistical Test Decision Guide
Students can make test selection more systematic by moving through a fixed sequence of questions. This reduces the temptation to choose a test based on what appears easiest in SPSS or what another dissertation happened to use. It also creates a decision trail that can later be explained in the methodology chapter.
The following process covers many common undergraduate and postgraduate quantitative dissertation analyses:
- State exactly what the research question or hypothesis asks.
- Decide whether the objective is description, comparison, association, or prediction.
- Identify the outcome variable and any grouping or predictor variables.
- Classify each relevant variable as categorical, ordinal, or continuous as appropriate.
- For comparisons, determine how many groups or conditions are involved.
- Determine whether observations are independent, paired, matched, or repeatedly measured.
- Identify a candidate statistical test that matches this structure.
- Check the assumptions and diagnostic requirements of that specific test.
- Consider an appropriate alternative if important requirements are not adequately satisfied.
- Plan how effect sizes, uncertainty, test statistics, and relevant diagnostic information will be reported.
This process reflects the principle used in established statistical decision guides: test selection depends jointly on the research objective, variable types, number and relationship of groups, and statistical assumptions. It should occur during methodology planning wherever possible rather than being improvised after data collection.
Quick Statistical Test Selection Table for Dissertation Research
A decision table can help students identify which statistical family deserves further investigation. It is particularly useful during dissertation planning when the researcher knows the variables and hypotheses but has not yet selected the final analysis. The table below covers common situations rather than every statistical design.
| If Your Question Asks... | Data Structure | Test Commonly Considered |
|---|---|---|
| Is one sample mean different from a specified value? | One suitable continuous outcome | One-sample t-test |
| Do two independent groups differ? | Continuous outcome, two independent groups | Independent-samples t-test |
| Did the same participants change between two measurements? | Continuous outcome, paired observations | Paired-samples t-test |
| Do three or more independent groups differ? | Continuous outcome, multiple independent groups | One-way ANOVA |
| Are two categorical variables associated? | Categorical variables | Chi-square test of independence |
| Are two suitable continuous variables linearly related? | Two continuous variables | Pearson correlation |
| Are ordinal variables monotonically related? | Ordinal or ranked data | Spearman correlation |
| How is a continuous outcome related to predictors? | Continuous outcome, one or more predictors | Linear regression |
| How is a binary outcome related to predictors? | Binary outcome, one or more predictors | Logistic regression |
Students should resist treating this table as a substitute for statistical reasoning. For example, identifying "three groups" does not automatically justify ANOVA if the outcome and design do not meet the relevant requirements. The table identifies a candidate procedure; the assumptions and research design determine whether that candidate remains defensible.
Why Statistical Assumptions Must Be Checked Before Finalising the Test
Statistical tests rely on assumptions that allow their estimates, standard errors, test statistics, or p-values to be interpreted appropriately. The exact assumptions vary by procedure. Independence, distributional properties, linearity, homogeneity of variance, expected cell counts, and model specification are examples of issues that can become relevant depending on the chosen analysis.
Assumption checking should therefore be test-specific. For linear regression, for example, attention is commonly given to the behaviour of residuals, linearity, constant error variance, independence, influential observations, and model specification. For chi-square analysis, expected cell frequencies become relevant. For independent group comparisons, the structure and independence of observations are fundamental.
Students should also avoid turning assumption testing into an automatic sequence of significance tests. Graphical diagnostics, descriptive statistics, study design, sample size, and substantive knowledge can all contribute to evaluating whether a model is reasonable. A single normality-test p-value should not dictate the entire analytical strategy without considering these wider factors.
If an assumption is violated, the response depends on what has failed and how seriously. Researchers may consider a more appropriate model, a robust procedure, a justified transformation, a non-parametric method, or another analytical strategy. Do not change tests solely to obtain a statistically significant result; changes must be justified by the research design and properties of the data.
How Sample Size Affects Statistical Test Selection
Sample size influences statistical analysis because small datasets may provide limited precision and statistical power. A test can be mathematically possible with a small sample yet produce estimates that are too uncertain to support the intended inference. Sample-size planning should therefore occur before data collection whenever the design allows it.
Larger samples do not automatically solve methodological problems. A large convenience sample can still be biased, a poorly measured variable remains poorly measured, and dependent observations do not become independent simply because there are many of them. Statistical power and research validity address different aspects of study quality.
Sample size also interacts with assumptions. Some procedures are reasonably robust to certain departures under appropriate conditions, while small samples can make distributional problems or sparse categorical cells more consequential. Researchers should avoid simplistic rules such as assuming every sample above a particular number automatically satisfies all requirements for parametric analysis.
Where formal power analysis is relevant, it should reflect the proposed statistical test, expected effect, significance level, desired power, and design structure. The required information differs across tests, which is another reason why researchers should identify the intended analysis before collecting data rather than after the dataset is complete.
How to Report the Statistical Test in Your Dissertation
The methodology chapter should explain which statistical procedures were selected and why they were appropriate for the research questions and data. Simply writing that "the data were analysed using SPSS" is insufficient because SPSS is software rather than an analytical method. Epic Essay's guide to quantitative thesis research explains that a quantitative methodology should identify the statistical techniques used alongside the wider research design, sample, instruments, and analytical process.
The findings chapter should then report the results of those procedures accurately and selectively. Relevant information may include descriptive statistics, test statistics, degrees of freedom, p-values, confidence intervals, coefficients, effect sizes, and other measures appropriate to the test and disciplinary convention. A p-value alone rarely communicates everything readers need to understand the result.
Results should also be connected explicitly to the research question or hypothesis. A statistical test is useful because it answers a substantive question, not because it generates a table of numbers. Epic Essay's guide to dissertation findings and discussion explains how statistical outcomes should subsequently be presented and interpreted in relation to the study's research questions and wider literature.
Researchers should distinguish statistical significance from substantive importance. A small effect can be statistically significant in a sufficiently large dataset, while an uncertain result in a small sample may still contain information worth discussing cautiously. Interpretation should therefore consider effect magnitude, uncertainty, design limitations, and context rather than reducing the entire finding to whether p is below a conventional threshold.
Common Mistakes When Choosing Statistical Tests
A frequent mistake is selecting a test because it appeared in a previous dissertation. Another study may have a similar topic but different variables, measurement levels, sample structure, hypotheses, or research design. Statistical methods should be transferred only when the underlying analytical problem is genuinely comparable.
Another error is choosing a test according to the software menu. Students sometimes decide to "use ANOVA" or "run regression" before identifying what their variables represent. This places software before methodology and can result in an analysis that is technically executable but conceptually inappropriate.
Students may also run multiple tests until one becomes statistically significant. This data-driven search increases the risk of misleading conclusions and makes the final analysis difficult to justify. Where multiple testing is genuinely required, it should form part of a planned analytical strategy with appropriate attention to the consequences of conducting numerous comparisons.
Finally, some dissertations report assumption checks without showing how those checks affected the analytical decision. If a diagnostic reveals a genuine problem, the researcher should explain what was done and why. Methodological transparency is stronger than presenting a checklist of tests whose implications are never discussed.
Choosing a Statistical Test You Can Defend in Your Dissertation
Choosing the right statistical test for a dissertation is ultimately a process of alignment. Begin with the research question, identify whether the analysis concerns description, comparison, association, or prediction, and then classify the variables involved. From there, consider the number of groups, whether observations are independent or related, and which statistical procedures match that structure.
The next step is to evaluate assumptions rather than assuming that the first candidate test is automatically appropriate. T-tests, ANOVA, chi-square tests, correlations, regression models, and non-parametric procedures each answer particular questions under particular conditions. A simpler method that matches the design is academically stronger than an advanced technique selected without methodological justification.
Finally, plan statistical analysis before collecting data whenever possible and explain the reasoning clearly in the dissertation methodology. Check assumptions, report results with appropriate measures of magnitude and uncertainty, and interpret statistical evidence in relation to the research question rather than the software output alone. When every analytical decision can be traced back to the design and purpose of the study, the statistical test becomes a defensible part of the research rather than an isolated calculation.
Comments