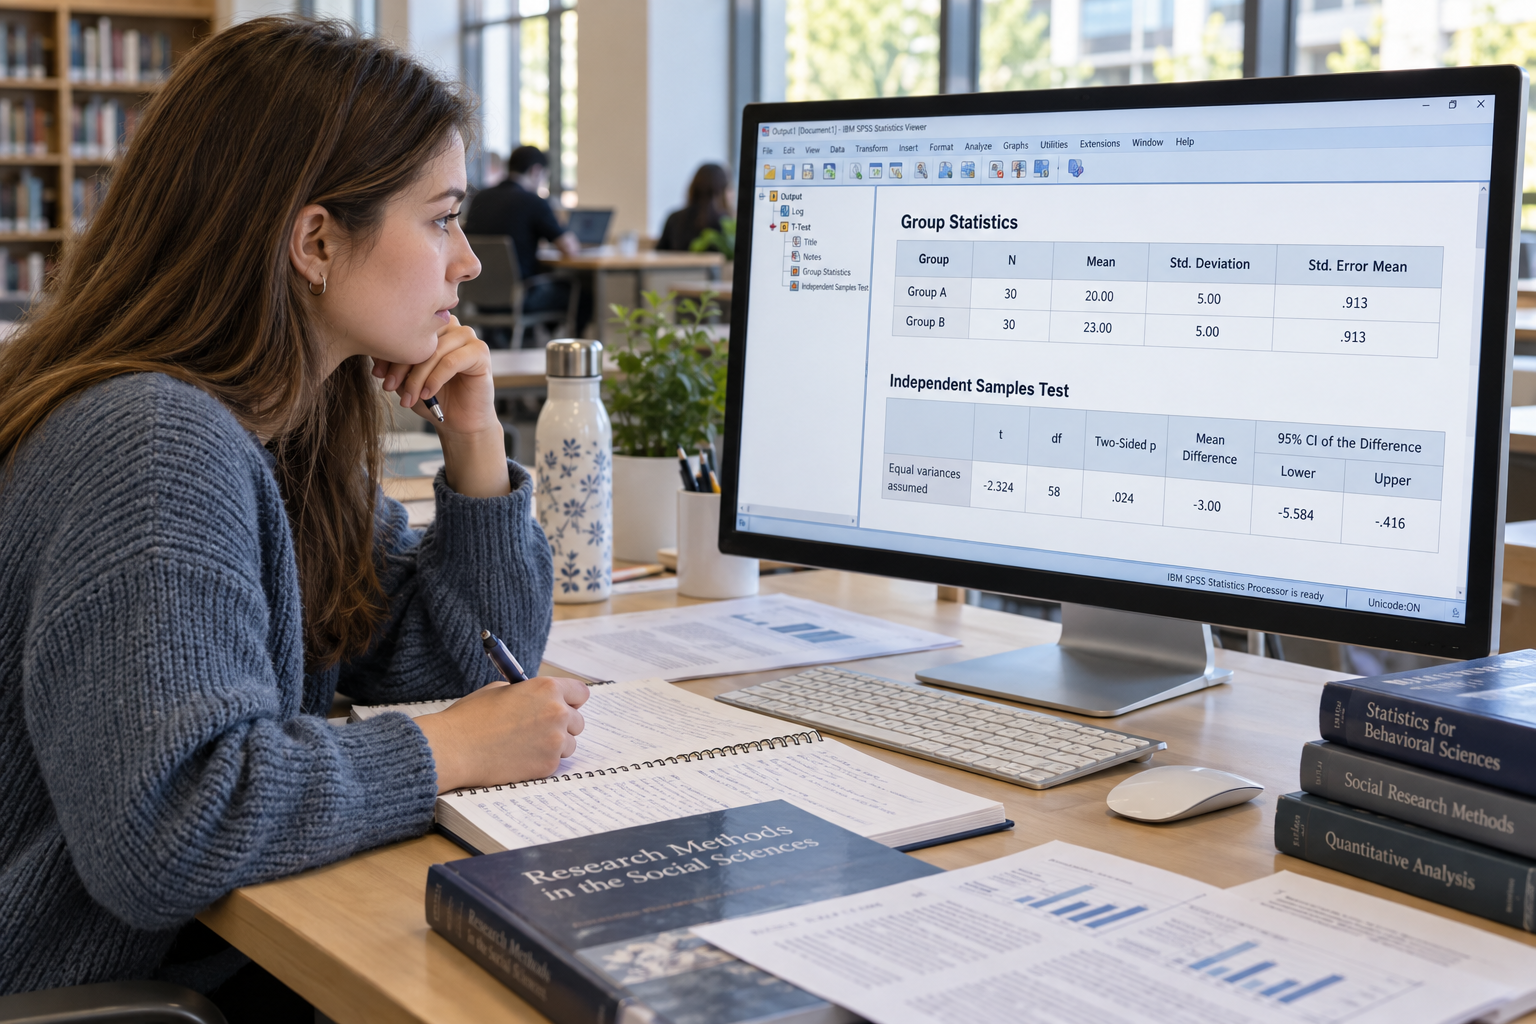
Comparing two groups is one of the most common tasks in quantitative research. A psychology student might compare anxiety scores between an intervention and control group, a business researcher might compare job satisfaction between remote and office employees, and an education researcher might compare examination scores between students taught using two different methods. When the outcome is quantitative and the two groups are independent, an independent samples t-test is often an appropriate statistical procedure.
An independent samples t-test in SPSS does more than produce a single p-value. The output provides descriptive statistics for each group, a test of the equality of variances, the estimated difference between means, the t statistic, degrees of freedom, significance information, confidence intervals, and, in current SPSS versions, options for estimating effect size. Correct interpretation requires these pieces of evidence to be considered together rather than treating statistical significance as the entire result.
Students often find the SPSS procedure relatively easy to run but struggle with the output. Questions commonly arise about which row to use after Levene’s test, what a negative t value means, how to interpret Sig. (2-tailed) or two-sided p values, and how to convert the output into a concise academic results paragraph. This guide works through the independent samples t-test step by step, from deciding whether the test is appropriate to interpreting and writing up a complete result.
What Is an Independent Samples t-Test?
An independent samples t-test compares the means of a quantitative outcome between two independent groups. IBM describes the SPSS Independent-Samples T Test procedure as a method for comparing means for two groups of cases. Each participant belongs to one group rather than contributing a paired observation to both groups.
For example, suppose a researcher investigates whether students receiving online tutoring have different examination scores from students receiving classroom tutoring. Teaching format is the grouping variable with two independent categories, while examination score is the quantitative test variable. The independent samples t-test evaluates whether the difference between the two sample means provides sufficient evidence of a difference between the corresponding population means under the assumptions of the test.
The test should be selected because it matches the research question and design, not simply because the dataset contains two columns of numbers. Epic Essay's guide to quantitative thesis research and data analysis explains that statistical methods should correspond to the research question, variables, and analytical purpose. This alignment is essential when justifying the test in a dissertation methodology chapter.
An independent samples t-test asks whether the means of two independent groups differ beyond what would reasonably be expected from sampling variability under the null hypothesis.
When Should You Use an Independent Samples t-Test?
The test is appropriate when the research question concerns a difference in a quantitative outcome between two independent groups. The dependent or test variable should be measured numerically in a way for which a mean is meaningful, while the grouping variable must identify two separate groups. Examples include treatment versus control, employed versus unemployed participants, or students from two independent teaching conditions.
Independence is particularly important. A participant should not appear in both groups, and observations should not be naturally paired. If the same participants are measured before and after an intervention, the observations are related and a paired samples t-test is generally the relevant t-test structure rather than an independent samples test.
The distinction can be summarised as follows.
| Research Situation | Typical Test | Example |
|---|---|---|
| One sample compared with a specified value | One-sample t-test | Mean student score compared with a benchmark of 70 |
| Two separate groups compared | Independent samples t-test | Intervention group compared with control group |
| Two related measurements compared | Paired samples t-test | Pre-test and post-test scores from the same students |
The independent samples test is therefore defined by the study design as much as by the number of groups. Two measurements do not automatically imply an independent samples t-test; researchers must determine whether those measurements come from different independent cases or from related observations.
What Are the Assumptions of an Independent Samples t-Test?
Statistical assumptions describe conditions under which the test's inferential calculations have their intended interpretation. IBM's documentation states that the equal-variance version assumes independent observations drawn from normal populations with the same population variance. The unequal-variance version does not require equal population variances, while independence and distributional considerations remain relevant.
Normality should be considered within the groups rather than by looking only at the pooled outcome variable. IBM notes that the two-sample t-test is fairly robust to departures from normality and recommends looking graphically for symmetry and outliers. The importance of a departure depends on factors such as sample size, imbalance between groups, severity of skewness, and influential observations.
Students should therefore avoid treating assumptions as a mechanical pass-or-fail checklist. A single normality-test p-value does not fully describe a distribution, and an isolated outlier should not automatically be deleted. Histograms, Q-Q plots, boxplots, descriptive statistics, study design, and the source of unusual observations all contribute to an informed assessment.
The main considerations before interpreting an independent samples t-test include:
- A quantitative dependent variable for which comparing means is meaningful
- A grouping variable containing two independent groups
- Independent observations
- Distributional characteristics within each group that do not seriously undermine the analysis
- Assessment of unusual or influential outliers
- Equality of variances when interpreting the pooled equal-variance version of the test
These assumptions should also be connected to the methodology. Epic Essay's guide to writing a dissertation methodology chapter emphasises that data-analysis techniques should be described and justified rather than merely named. Explaining why an independent samples t-test matched the variables and research design strengthens methodological transparency.
How to Run an Independent Samples t-Test in SPSS
Before running the test, the data should be structured correctly. IBM specifies that the quantitative test variable is stored in a single column, while a grouping variable separates cases into two groups. For example, examination scores could appear in one column and teaching group could be coded as 1 for online teaching and 2 for classroom teaching.
In current SPSS Statistics, IBM gives the menu route as Analyze, Compare Means, Independent-Samples T Test. The researcher selects the quantitative outcome as the test variable and the categorical variable as the grouping variable. The two group codes must then be defined so that SPSS knows which categories should be compared.
A practical workflow is:
- Check that the outcome variable and grouping variable are coded correctly.
- Inspect missing values and obvious data-entry errors.
- Examine descriptive statistics and relevant distributional plots.
- Select Analyze > Compare Means > Independent-Samples T Test.
- Move the quantitative outcome into the Test Variable area.
- Move the two-category variable into the Grouping Variable area.
- Define the two group codes used in the dataset.
- Request the homogeneity of variance test where required.
- Request effect-size estimates if available and relevant.
- Run the analysis and interpret the output systematically.
SPSS can perform separate independent samples t-tests for multiple quantitative test variables, but researchers should not add outcomes indiscriminately. Every test should have a clear relationship to the research question or hypotheses, and multiple testing may require additional methodological consideration.
How to Read the SPSS Group Statistics Table
The Group Statistics output should be examined before the inferential test. It normally reports the sample size, mean, standard deviation, and standard error for each group. These values show the observed direction and size of the difference that the t-test subsequently evaluates.
Consider a hypothetical study comparing examination scores between online and classroom teaching groups. Suppose 40 students are included in each group, the online group has a mean of 74.80 with SD = 8.20, and the classroom group has a mean of 69.10 with SD = 9.00. The observed mean difference is therefore 5.70 points in favour of the online group.
| Teaching Group | N | Mean | Standard Deviation |
|---|---|---|---|
| Online teaching | 40 | 74.80 | 8.20 |
| Classroom teaching | 40 | 69.10 | 9.00 |
These descriptive statistics establish what happened in the sample but do not by themselves establish statistical significance. The inferential portion of the output evaluates the mean difference relative to its uncertainty. This is why a strong write-up normally reports both group descriptives and the t-test result.
How to Interpret Levene's Test in SPSS
SPSS can provide Levene's test for equality of variances as part of the independent samples analysis. Its null hypothesis concerns equality of the population variances. The result helps determine whether the pooled equal-variance t-test is appropriate or whether the unequal-variance result should be used.
A common classroom decision rule uses an alpha level of .05. If Levene's test is not statistically significant at the chosen alpha level, there is insufficient evidence against the equal-variance assumption and the equal-variances result is commonly reported. If Levene's test is statistically significant, the unequal-variances result, often associated with the Welch adjustment to the degrees of freedom, is generally preferred.
The logic can be summarised as follows.
| Levene's Test Result | Variance Interpretation | Result to Use |
|---|---|---|
| p greater than the chosen alpha, commonly .05 | Insufficient evidence that the population variances differ | Equal-variances t-test result is commonly used |
| p less than the chosen alpha, commonly .05 | Evidence against equality of population variances | Unequal-variances or Welch result is generally used |
Levene's test should not be confused with the t-test itself. It addresses the variance assumption, not the primary hypothesis about the difference between group means. A significant Levene's test does not mean that the two group means are significantly different. The mean comparison must still be interpreted from the appropriate t-test result.
How to Interpret t, Degrees of Freedom, and the p-Value
The t statistic represents the observed mean difference relative to the estimated standard error of that difference. A larger absolute t value indicates that the observed difference is larger relative to its estimated sampling uncertainty. However, t should not be interpreted using a universal magnitude rule because its inferential meaning depends on the degrees of freedom and the reference distribution.
Degrees of freedom, shown as df, contribute to determining the relevant t distribution. Under the conventional equal-variance independent samples t-test, df is based on the two sample sizes. Under the unequal-variance approach, SPSS can report a non-integer adjusted df because the calculation accounts for differences in group variances and sample sizes.
The p-value addresses the compatibility of the observed result with the null hypothesis under the assumptions of the statistical model. If a pre-specified significance level is .05 and the relevant two-sided p-value is below .05, researchers conventionally reject the null hypothesis of equal population means. If it is above .05, the analysis does not provide sufficient evidence to reject that null hypothesis at that threshold.
Statistical significance should nevertheless be worded carefully. A p-value of .032 does not mean there is a 96.8% probability that the research hypothesis is true. Likewise, p = .18 does not prove that the two populations have identical means. The result should be interpreted alongside the estimated difference, confidence interval, effect size, study design, and uncertainty.
What Does a Negative t Value Mean?
A negative t statistic often worries students because it can look like evidence of a negative or unsuccessful result. In an independent samples t-test, the sign primarily reflects the direction in which the group difference was calculated. If SPSS calculates Group 1 minus Group 2 and Group 1 has the lower mean, the mean difference and t statistic will generally be negative.
Suppose Group 1 has a mean score of 62 and Group 2 has a mean of 70. The calculated mean difference is 62 - 70 = -8. Reversing the order of the groups would change the direction of the difference and therefore the sign of t, while the two-sided significance conclusion would remain unchanged.
The sign should therefore be interpreted with the group means. A negative value tells the researcher about direction under the chosen coding order, not whether the result is statistically significant. Significance comes from the inferential test and associated p-value.
This is another reason to inspect Group Statistics before reading the t-test table. The descriptive means make the direction of the difference immediately understandable and prevent the sign of t from being interpreted in isolation.
How to Interpret the Mean Difference and Confidence Interval
The mean difference translates the comparison back into the units of the outcome variable. If the online-teaching group has a mean of 74.80 and the classroom group has a mean of 69.10, the difference is 5.70 points when SPSS subtracts the second group from the first. This is often easier to understand substantively than the t statistic alone.
SPSS can also report a confidence interval for the difference between means. IBM states that the procedure provides the difference in means, its standard error, and a confidence interval whose confidence level can be specified. A 95% confidence interval provides a range of values compatible with the estimated population mean difference under the model and sampling assumptions.
For a conventional two-sided test at alpha = .05, a 95% confidence interval for the mean difference that excludes zero corresponds to statistical significance at that level. An interval containing zero indicates that zero remains among the values compatible with the data at that confidence level. The interval also communicates precision: a narrow interval estimates the difference more precisely than a wide interval.
Confidence intervals should therefore receive more attention than they sometimes do in student assignments. A p-value provides a threshold-oriented inferential result, while the confidence interval shows both the direction of the estimated difference and the uncertainty surrounding its magnitude.
Why Effect Size Matters Alongside Statistical Significance
A statistically significant result does not automatically imply a large or practically important difference. With sufficiently large samples, relatively small differences can produce small p-values. Conversely, a potentially meaningful difference in a small sample may be estimated imprecisely and fail to reach a conventional significance threshold.
Effect sizes help quantify the magnitude of the group difference on a standardised scale. Current IBM SPSS documentation states that the Independent-Samples T Test procedure can estimate t-test effect sizes. Depending on the version and settings, researchers may have effect-size information available directly in the output.
Cohen's d is a commonly reported standardised mean difference, although alternative estimators may be preferable in some settings. Interpretation should consider the discipline, measurement scale, previous research, and practical implications rather than applying small, medium, and large labels mechanically.
Statistical significance asks whether the data provide evidence of a difference under the model; effect size asks how large the estimated difference is. A strong results section considers both questions.
Independent Samples t-Test SPSS Interpretation Example
Consider a hypothetical dissertation investigating whether online tutoring is associated with different examination performance from classroom tutoring. Forty students are included in each group. The online group obtains M = 74.80, SD = 8.20, while the classroom group obtains M = 69.10, SD = 9.00.
Suppose Levene's test produces p = .412, so the equal-variance result is used under the conventional .05 decision rule. The independent samples t-test then produces t(78) = 2.96, p = .004, with a mean difference of 5.70 points and a hypothetical 95% confidence interval from 1.86 to 9.54. These values indicate evidence of a difference in mean examination scores between the two groups, with the sample mean higher in the online group.
| Output | Example Value | Interpretation |
|---|---|---|
| Online group mean | 74.80 | Average score for Group 1 |
| Classroom group mean | 69.10 | Average score for Group 2 |
| Levene's test p | .412 | No evidence against equal variances at alpha = .05 |
| t | 2.96 | Test statistic for the mean comparison |
| df | 78 | Degrees of freedom |
| Two-sided p | .004 | Statistically significant at alpha = .05 |
| Mean difference | 5.70 | Online group scored 5.70 points higher on average |
| 95% confidence interval | 1.86 to 9.54 | Interval estimate for the population mean difference |
The correct interpretation combines these elements rather than stating only that "p is less than .05." Readers need to know which group scored higher, the approximate magnitude of the difference, and the uncertainty surrounding that estimate.
How to Write Up an Independent Samples t-Test in a Dissertation
A results paragraph should normally identify the groups, provide relevant descriptive statistics, report the inferential test, and state the direction of the result. Depending on institutional requirements, an effect size and confidence interval may also be included. The wording should remain objective and avoid causal language unless the research design genuinely supports a causal interpretation.
Using the hypothetical results above, an academic write-up could state: "Students in the online tutoring group achieved higher examination scores (M = 74.80, SD = 8.20) than students in the classroom tutoring group (M = 69.10, SD = 9.00). An independent samples t-test indicated that the mean difference was statistically significant, t(78) = 2.96, p = .004, mean difference = 5.70, 95% CI [1.86, 9.54]."
This paragraph communicates the essential result without copying the entire SPSS table. Epic Essay's guide to dissertation findings and discussion explains that quantitative findings should be presented clearly and systematically, while the discussion should interpret their meaning and connect them with the research questions and existing literature.
The results section should therefore avoid unsupported explanations such as claiming that online tutoring caused higher scores when the study was merely observational. The wording must reflect the research design. IBM itself notes that when groups are not randomly assigned, other factors can mask or enhance observed mean differences, which is an important caution when interpreting non-experimental comparisons.
How to Write Up a Non-Significant Independent Samples t-Test
A non-significant result should be reported with the same care as a significant result. Suppose Group A has M = 67.20, SD = 7.90 and Group B has M = 65.80, SD = 8.30, with t(68) = 0.72 and p = .474. The appropriate conclusion is that the analysis did not provide statistically significant evidence of a difference at the chosen significance level.
It would be inaccurate to write that "there was absolutely no difference between the groups." The sample means do differ numerically, and a non-significant test does not prove that the population means are exactly equal. Confidence intervals can be particularly useful because they show the range of differences compatible with the observed data.
A suitable write-up might state: "Mean scores were slightly higher in Group A (M = 67.20, SD = 7.90) than in Group B (M = 65.80, SD = 8.30), but the difference was not statistically significant, t(68) = 0.72, p = .474." If a confidence interval and effect size are available, reporting them provides additional information about the magnitude and precision of the estimate.
Do not translate p greater than .05 into proof that two groups are identical. Report the estimated difference, its uncertainty, and the statistical evidence without making a stronger claim than the analysis supports.
How to Report the Test When Levene's Test Is Significant
When the equal-variance assumption is not supported, the unequal-variance version of the independent samples t-test should generally be interpreted. This approach adjusts the standard error and degrees of freedom rather than pretending that the two population variances are equal. The resulting degrees of freedom may therefore contain decimal places.
Suppose Levene's test gives p = .012 and the unequal-variance result produces t = 2.31, df = 56.47, and p = .025. The write-up would use these unequal-variance statistics rather than copying the equal-variance row simply because its degrees of freedom look more familiar.
A concise report might state that the variance assumption was not supported and that the unequal-variance t-test was therefore interpreted. The group means and standard deviations should still be provided because they communicate the direction and variability of the observed scores.
The key principle is to make the analytical choice transparent. Readers should be able to see that the researcher recognised the variance issue and interpreted the appropriate test rather than selecting whichever SPSS row produced the preferred p-value.
Independent Samples t-Test vs Paired t-Test vs ANOVA
Students sometimes choose an independent samples t-test simply because their research involves mean comparisons. The number of groups and relationship between observations determine whether another procedure is more suitable. A paired t-test addresses two related measurements, while analysis of variance is commonly used when comparing means across more than two groups.
For example, comparing satisfaction between employees in two independent departments could fit an independent samples t-test. Measuring satisfaction in the same employees before and after organisational change creates paired observations. Comparing satisfaction across four departments introduces more than two groups and may call for an ANOVA framework.
Choosing the test before considering the research design can lead to an analysis that answers the wrong statistical question. Epic Essay's guide to dissertation research methods emphasises that analytical methods need to align with the type of data and the research questions being addressed.
This alignment should be established during research planning rather than after data collection whenever possible. A clearly formulated hypothesis and analysis plan make later SPSS decisions much easier to justify.
Common Independent Samples t-Test Mistakes in SPSS
A frequent error is interpreting the wrong SPSS result after Levene's test. Students may automatically use the first result displayed without checking the variance assumption. The selected result should reflect whether the equal-variance model is appropriate under the analytical approach being used.
Another mistake is reporting only the p-value. Writing "p = .03, therefore there is a significant difference" omits the group means, variability, direction of the difference, t statistic, degrees of freedom, and information about magnitude. A statistically complete write-up should provide enough evidence for readers to understand the comparison.
Researchers can also confuse statistical significance with practical importance or causation. A small mean difference may be statistically detectable in a large sample but have limited substantive importance. Similarly, a significant difference between naturally occurring groups does not by itself establish that group membership caused the outcome.
Finally, some students modify the analysis repeatedly until a p-value falls below .05. Do not choose assumptions, delete observations, reverse hypotheses, or switch statistical tests simply to obtain statistical significance. Analytical decisions should be based on the research design, data characteristics, and pre-specified methodological reasoning.
A Step-by-Step SPSS t-Test Interpretation Checklist
Interpreting the output in a fixed order reduces mistakes. Begin with the research question and study design, then move from descriptive statistics to assumptions and finally to inferential results. This prevents the p-value from dominating the entire analysis.
A practical sequence is:
- Confirm that the research question compares two independent groups.
- Check that the dependent variable is suitable for a mean comparison.
- Verify that each case belongs to the appropriate group and that observations are independent.
- Inspect missing values, descriptive statistics, distributions, and unusual observations.
- Read the Group Statistics table and identify which group has the higher mean.
- Examine the variance assumption and determine the appropriate t-test result.
- Report the t statistic and degrees of freedom.
- Interpret the relevant two-sided p-value against the pre-specified significance level.
- Report the mean difference and confidence interval where appropriate.
- Report and interpret an appropriate effect size when required.
- State the result in relation to the research question without overstating causality.
- Present the statistics clearly rather than pasting raw SPSS output into the dissertation.
This sequence produces a more defensible analysis because every inferential statement is supported by descriptive and methodological context. It also creates a natural structure for moving from SPSS output to an academic results paragraph.
Interpreting and Writing Up an Independent Samples t-Test Correctly
An independent samples t-test in SPSS is most useful when the statistical procedure, study design, and academic interpretation remain connected. The analysis begins by confirming that two genuinely independent groups are being compared on an appropriate quantitative outcome. Descriptive statistics then establish the observed direction and variability before the inferential test evaluates the evidence for a population mean difference.
SPSS output should be interpreted systematically. Examine the group means and standard deviations, assess the relevant assumptions, use the appropriate equal- or unequal-variance result, and report t, degrees of freedom, the p-value, mean difference, confidence interval, and effect size where appropriate. No single statistic should carry the entire interpretation.
The final write-up should tell the reader what was compared, which group had the higher or lower mean, how large the estimated difference was, how uncertain that estimate remains, and what the statistical test indicates. When these elements are reported accurately and without overstating significance or causality, the independent samples t-test becomes more than an SPSS procedure: it becomes a transparent and defensible part of the dissertation's quantitative argument.
Comments