Correlation analysis is one of the most widely used techniques in quantitative research because many research questions concern relationships between variables. A psychology student may investigate whether stress is related to academic performance, a business researcher may examine the relationship between advertising expenditure and sales, and a health researcher may study whether physical activity is associated with blood pressure. Choosing an appropriate correlation coefficient is essential because different coefficients describe different forms of association.
The Pearson vs Spearman correlation decision is particularly important for university students because the two tests are sometimes treated as interchangeable. Pearson's product-moment correlation coefficient, usually represented by r, measures the strength and direction of a linear relationship between two quantitative variables. Spearman's rank-order correlation, commonly represented by rho or ρ, works with ranked values and assesses whether two variables have a monotonic relationship.
The correct choice therefore depends on more than whether data are "normal" or "non-normal." Researchers should consider measurement level, the shape of the relationship, influential outliers, independence of observations, and the actual research question. This guide explains these distinctions step by step and shows how to choose, interpret, and report Pearson or Spearman correlation without relying on oversimplified decision rules.
What Is Correlation Analysis?
Correlation analysis examines how two variables vary together. A positive association means that larger values of one variable tend to occur with larger values of the other, while a negative association means that larger values of one tend to occur with smaller values of the other. A coefficient near zero indicates little evidence of the particular form of association measured by that coefficient.
Correlation coefficients also describe the strength of a relationship on a standardised scale. Pearson's r ranges from -1 to +1, and Spearman's rho also ranges from -1 to +1. Values closer to either endpoint indicate a stronger relationship of the relevant type, while the sign indicates direction.
Correlation is particularly useful in non-experimental quantitative research where researchers want to investigate associations without manipulating variables. Epic Essay's guide to quantitative thesis research and data analysis identifies correlational research as an important quantitative approach for examining relationships between variables. However, the coefficient chosen must match the characteristics of those variables and the relationship being investigated.
Correlation describes association, not causation. A strong Pearson or Spearman coefficient does not by itself establish that changes in one variable caused changes in the other.
What Is Pearson Correlation?
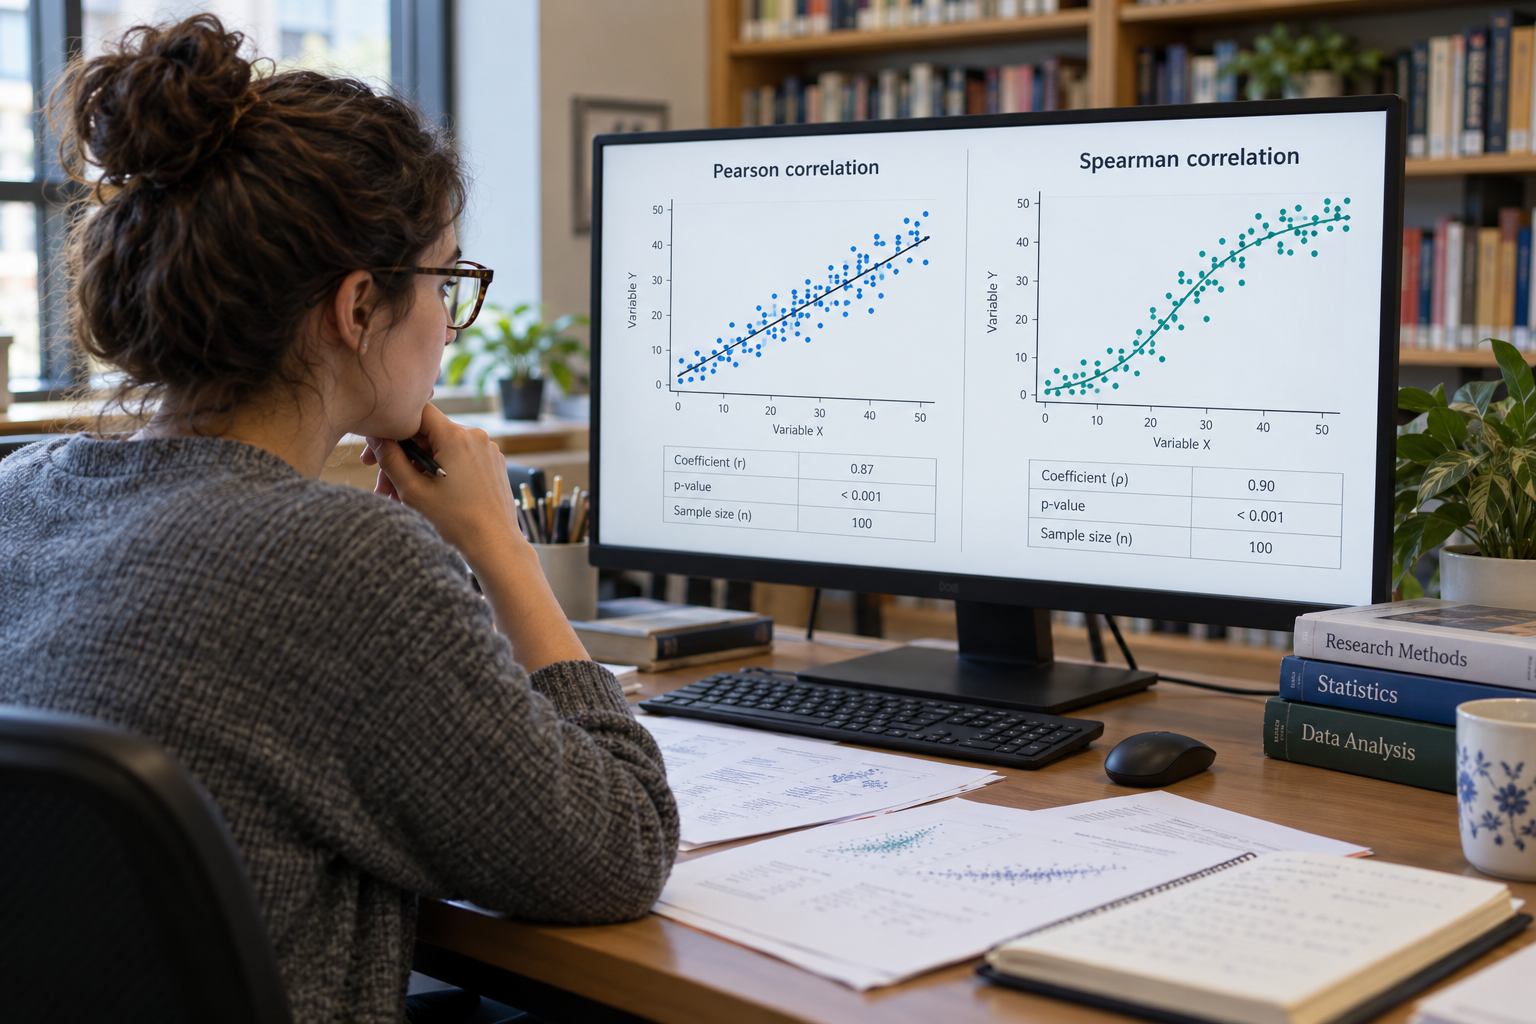
Pearson correlation measures the strength and direction of a linear relationship between two quantitative variables. A linear relationship is one that can be meaningfully represented by a straight-line pattern: as one variable changes, the other tends to change at a relatively consistent rate. Pearson's coefficient is sensitive to both the direction and strength of this linear pattern.
Consider a study examining weekly study hours and examination scores. If students who study more hours generally obtain higher scores and the scatterplot follows an approximately straight upward pattern, Pearson correlation may provide an appropriate summary. A positive coefficient would indicate that higher study time tends to accompany higher examination performance.
Pearson correlation is not simply a test for "two numerical variables." The shape of the relationship matters. A strong curved relationship can exist even when Pearson's r is relatively small because Pearson specifically summarises linear association rather than every possible form of dependence.
Epic Essay's guide to choosing statistical tests similarly describes Pearson correlation as a method for examining linear relationships between continuous variables. This is why inspecting the data visually should accompany statistical calculations rather than treating the coefficient as a complete description of the relationship.
What Is Spearman Correlation?
Spearman's rank correlation measures the strength and direction of a monotonic relationship using the ranks of observations rather than relying directly on their original numerical distances. A monotonic relationship means that as one variable increases, the other tends consistently to increase or consistently to decrease, although the rate of change does not need to remain constant.
The University of Texas guidance on Spearman's rank correlation explains that Spearman correlation is appropriate for monotonic relationships and can be useful when outliers or non-linear patterns make Pearson correlation unsuitable. The relationship can curve while remaining monotonic, provided it does not repeatedly reverse direction.
Spearman correlation is also commonly considered when variables are ordinal. For example, a researcher might examine the association between students' ranked satisfaction levels and ranked perceptions of teaching quality. Because the meaningful information lies primarily in ordering rather than equal numerical distances between categories, a rank-based approach can be more appropriate than treating the scores as conventional continuous measurements.
Spearman should not be described simply as "Pearson for bad data." It answers a related but distinct question because it measures association between ranks. The choice should therefore follow from the variables and relationship structure rather than being made automatically whenever one assumption check produces a statistically significant result.
Pearson vs Spearman Correlation: What Is the Main Difference?
The central distinction is the form of relationship each coefficient describes. Pearson's r measures linear association using the original quantitative values. Spearman's rho measures monotonic association using the ranked ordering of values.
This difference has practical consequences. Imagine that income and expenditure increase together, but expenditure rises rapidly at lower income levels and then increases more slowly as income becomes high. The relationship may remain consistently increasing without following a straight line. Spearman can capture the monotonic ordering even when Pearson does not describe the curved pattern as effectively.
The main differences are summarised below.
| Feature | Pearson Correlation | Spearman Correlation |
|---|---|---|
| Main coefficient | Pearson's r | Spearman's rho or ρ |
| Relationship assessed | Linear | Monotonic |
| Values analysed | Original quantitative values | Ranks of values |
| Typical measurement level | Quantitative variables | Ordinal or quantitative variables suitable for ranking |
| Sensitivity to influential outliers | Greater | Generally less affected because values are ranked |
| Perfect positive relationship | r = +1 | ρ = +1 |
| Perfect negative relationship | r = -1 | ρ = -1 |
Neither coefficient is universally superior. Pearson can preserve important information about numerical distances when its conditions match the research problem, while Spearman can be valuable when rank ordering and monotonic association are more appropriate. Statistical choice should be based on what the researcher intends to measure.
Linear vs Monotonic Relationships Explained
Understanding linearity and monotonicity is the most important conceptual step in choosing between Pearson and Spearman correlation. A linear relationship follows an approximately straight-line pattern. The outcome tends to change by a relatively consistent amount as the other variable changes.
A monotonic relationship is broader. As X increases, Y consistently tends either to increase or to decrease, but the amount of change can vary. The relationship might be steep at first and then flatten, for example, while still maintaining the same overall direction.
A relationship can therefore be monotonic without being linear. However, a relationship that rises and then falls is not monotonic across its full range. In that situation, neither a simple Pearson coefficient nor a Spearman coefficient may adequately summarise the underlying pattern.
Do not choose Spearman merely because a scatterplot is curved. Spearman still requires a meaningful monotonic pattern if it is to summarise the relationship appropriately.
What Assumptions Should You Check for Pearson Correlation?
Pearson correlation requires more than entering two variables into statistical software. The observations should be appropriately independent, the variables should be quantitative for the intended Pearson analysis, and the relationship should be approximately linear. Influential outliers also require particular attention because they can substantially alter the coefficient.
Distributional assumptions become especially relevant when conducting inferential tests or constructing confidence intervals for Pearson correlation. Students often reduce this issue to the statement that "both variables must be normally distributed," but the statistical assumptions for inference are more precisely connected with the joint distribution and model underlying the test. Course-specific requirements may nevertheless ask students to document normality using prescribed procedures.
Homoscedasticity is another feature commonly examined. This concerns whether the spread of one variable around the linear relationship remains reasonably consistent across values of the other. A scatterplot can help identify strong changes in spread as well as departures from linearity and unusual observations.
A practical Pearson assessment should therefore consider:
- Whether the variables are quantitative and appropriate for a Pearson analysis
- Whether observations are independent
- Whether the relationship is approximately linear
- Whether influential outliers are present
- Whether the distributional conditions required for the intended inference are sufficiently supported
- Whether serious heteroscedasticity or other unusual patterns are visible
These checks should be connected to the research design rather than treated as boxes to tick after analysis. Epic Essay's guide to dissertation methodology emphasises that analytical methods should be justified according to the research questions and data rather than simply named.
What Assumptions Should You Check for Spearman Correlation?
Spearman correlation is less dependent on distributional form because it operates on ranks. It does not require the variables to have a linear relationship or follow the same parametric distributional conditions commonly associated with Pearson inference. This makes it useful in several situations where Pearson is not a good representation of the relationship.
However, Spearman is not assumption-free. Observations should still be independent under the study design, variables need to provide meaningful ordering, and the relationship should be monotonic if the coefficient is being used to summarise association. A scatterplot remains valuable because statistical software cannot determine the substantive appropriateness of the relationship for the researcher.
Tied ranks can occur when several observations have the same value, particularly with ordinal scales containing only a few response categories. Statistical software accounts for ties in its calculation, but heavy ties can affect the information available in the rankings. Researchers should therefore understand the structure of their variables rather than assuming that every ordinal dataset automatically produces an informative Spearman coefficient.
Spearman's reduced sensitivity to extreme numerical distances can be useful when genuine outliers are present, but it should not be used to conceal data-quality problems. An extreme observation caused by a data-entry error should be corrected where possible rather than simply choosing a rank-based test to reduce its influence.
Does Non-Normal Data Automatically Mean You Should Use Spearman?
One of the most common student decision rules is "normal data equals Pearson; non-normal data equals Spearman." This rule is attractive because it is simple, but it can produce poor statistical choices. The form of the relationship, measurement level, sample characteristics, outliers, and inferential objective all matter.
A large quantitative dataset may contain variables that are somewhat skewed while still displaying a clear linear relationship for which Pearson's r is substantively meaningful. Conversely, two approximately normal variables can have a strongly curved relationship for which Pearson's coefficient provides an incomplete summary. Normality alone therefore cannot determine the choice.
Students should also distinguish the descriptive correlation coefficient from the assumptions involved in significance testing. Statistical inference about Pearson's population correlation involves assumptions beyond simply examining separate normality tests for X and Y. A methodology should reflect the analytical framework actually used rather than a memorised decision tree.
Choose Pearson or Spearman from the measurement level, relationship shape, outliers, design, and inferential requirements together—not from a normality p-value alone.
How Outliers Affect Pearson and Spearman Correlation
Pearson correlation can be highly sensitive to influential observations because it uses the original numerical values. A single extreme case can strengthen, weaken, or even reverse the apparent linear association. This makes scatterplot inspection particularly important before reporting Pearson's r.
Spearman correlation replaces original values with ranks, so an extreme numerical distance does not exert the same influence. The highest observation is primarily represented as the highest rank regardless of whether its original value is 100 or 10,000. This often makes Spearman more resistant to extreme magnitudes.
However, the presence of an outlier does not automatically justify deleting it or switching tests. Researchers should first determine whether the value represents a recording error, an impossible observation, a genuine member of the population, or evidence of a more complicated relationship. Each possibility has different methodological implications.
Never remove an outlier solely because its removal produces a stronger correlation or a statistically significant p-value. Decisions about unusual observations require transparent, defensible criteria.
Can You Use Pearson or Spearman with Likert Scale Data?
Likert-type data require careful distinction between individual items and composite scale scores. A single Likert item such as a five-point response from "strongly disagree" to "strongly agree" is ordinal because the categories have a meaningful order but equal numerical spacing is not guaranteed. Spearman correlation is often considered when analysing relationships involving such ordinal variables.
Composite scores created from several well-designed items raise a more nuanced issue. In many applied disciplines, researchers analyse multi-item scale totals or averages as approximately quantitative variables when the measurement properties and methodological conventions support doing so. The choice of Pearson or Spearman then requires consideration of scale construction, distribution, relationship shape, and disciplinary practice.
Researchers should therefore explain what their scores represent rather than simply saying "Likert data were analysed." A five-category individual item and a 20-item validated scale score are not statistically identical simply because both originated from questionnaire responses.
The methodology chapter should document how variables were operationalised and why the selected correlation coefficient was suitable. This creates a more defensible analysis than choosing Spearman automatically for everything collected through a questionnaire.
Pearson vs Spearman Decision Guide
A useful decision process begins with the research question and measurement structure before examining the statistical output. Researchers should identify whether they want to quantify a linear relationship between quantitative measurements or a monotonic relationship based on ordering. They should then inspect the data to determine whether the intended coefficient provides a meaningful summary.
The following table provides a practical guide rather than an automatic rule.
| Data Situation | Usually Consider | Reason |
|---|---|---|
| Two quantitative variables with an approximately linear relationship | Pearson | Directly measures linear association using original values |
| Two meaningfully ranked variables | Spearman | Works with rank ordering |
| Monotonic but clearly non-linear relationship | Spearman | Does not require a straight-line relationship |
| Influential genuine extreme values make Pearson misleading | Consider Spearman | Ranks reduce the influence of numerical extremes |
| Relationship rises and then falls | Neither simple coefficient may be sufficient | The relationship is not consistently linear or monotonic |
| Two well-behaved quantitative variables with a clear linear scatterplot | Pearson | Preserves information in original numerical distances |
This table should not replace statistical judgement. The strongest justification combines the theoretical research question, measurement level, visual data pattern, assumptions, and intended interpretation.
How to Run Pearson and Spearman Correlation in SPSS
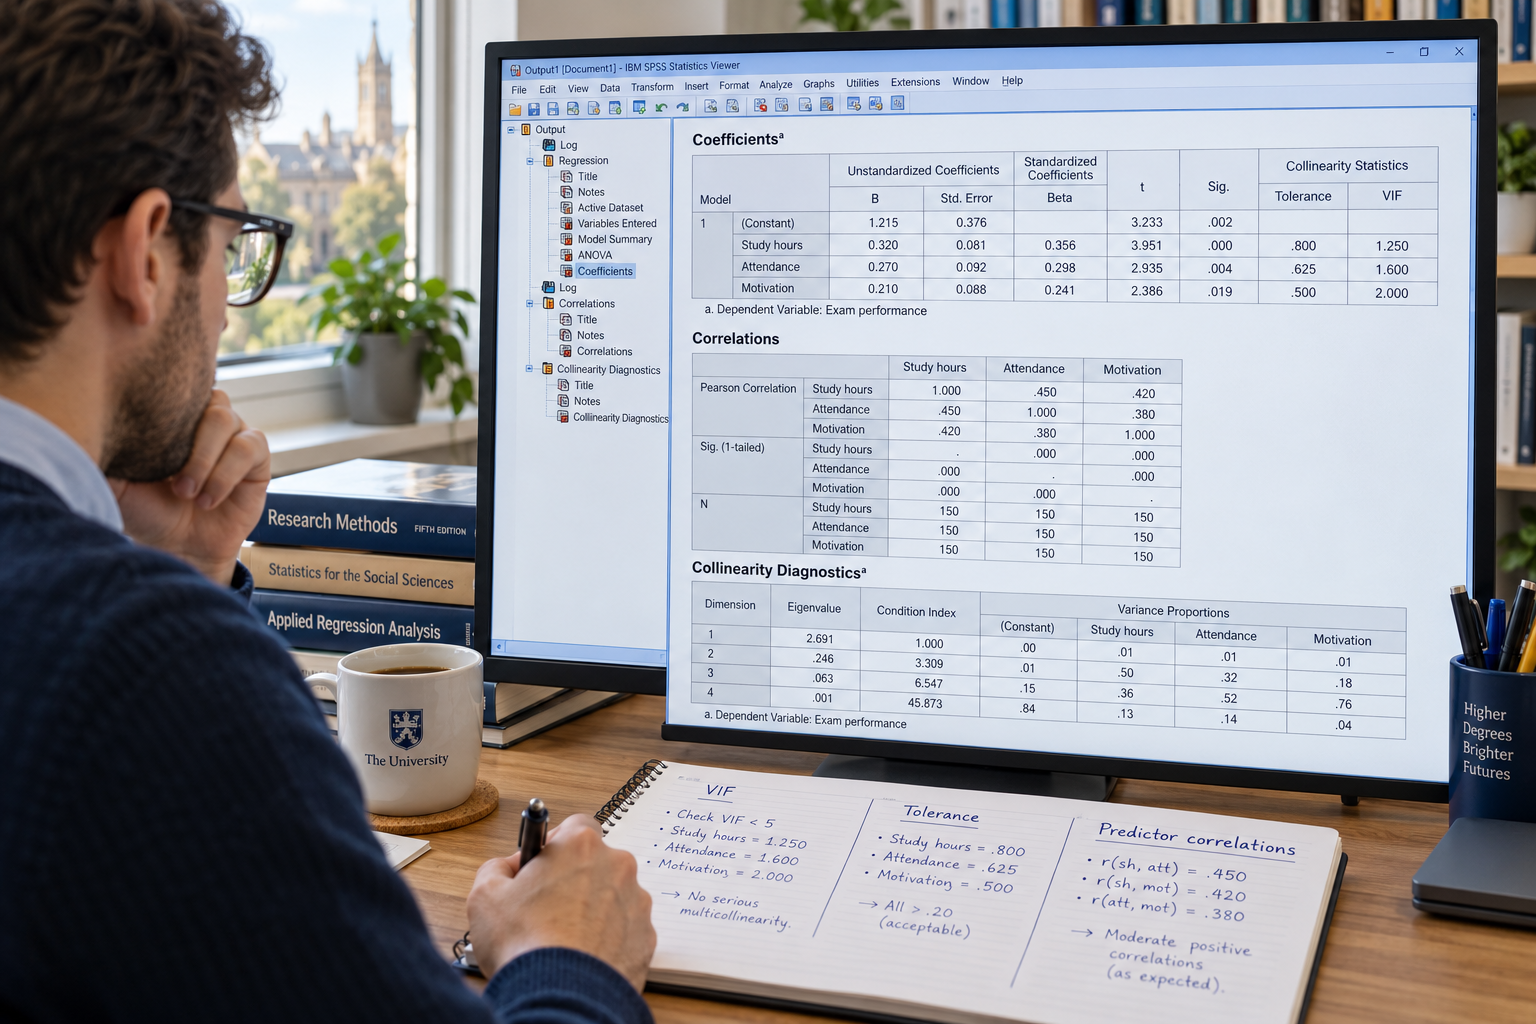
SPSS allows both coefficients to be requested through the bivariate correlation procedure. Researchers normally select Analyze, Correlate, and Bivariate, then move the relevant variables into the analysis box. Pearson and Spearman can be selected according to the analytical plan.
Running both coefficients simply to choose whichever produces the smaller p-value is poor practice. The decision should ideally be established from the research question, measurement properties, diagnostic assessment, and analysis plan. Comparing coefficients may sometimes be methodologically informative, but it should not become a strategy for significance hunting.
A defensible workflow is:
- Define the relationship being investigated from the research question.
- Identify the measurement level of both variables.
- Inspect data quality and missing values.
- Create a scatterplot where meaningful.
- Assess whether the relationship is linear, monotonic, or more complex.
- Investigate potentially influential observations.
- Consider the assumptions required for the planned inference.
- Select Pearson or Spearman based on this evidence.
- Run the chosen bivariate correlation in SPSS.
- Interpret the coefficient, direction, p-value, and substantive context together.
Epic Essay's guide to SPSS analysis and academic reporting emphasises that SPSS assignments assess interpretation and test selection rather than merely the ability to generate software output. Correlation analysis should therefore be explained, not simply pasted from SPSS.
How to Interpret Pearson's r and Spearman's rho
Both coefficients use their sign to indicate direction. A positive coefficient indicates that higher values or ranks on one variable tend to accompany higher values or ranks on the other. A negative coefficient indicates that higher values on one tend to accompany lower values on the other.
The absolute magnitude indicates the strength of the measured relationship. A coefficient of .80 represents a stronger association of the relevant type than .20, while a coefficient of -.80 is equally strong in magnitude but opposite in direction. The substantive importance of these values depends on the research context.
Researchers sometimes classify coefficients using fixed labels such as weak, moderate, and strong. Such conventions can provide orientation when they are justified, but they should not replace disciplinary interpretation. A correlation of .20 might be important in a context involving complex human behaviour but less informative in another setting where much stronger relationships are normally expected.
Interpretation must also retain the distinction between Pearson and Spearman. Pearson r = .70 describes a strong positive linear association, whereas Spearman ρ = .70 describes a strong positive monotonic association in the ranks. The numerical similarity does not make the coefficients conceptually identical.
How to Interpret the p-Value in Correlation Analysis
The significance test commonly accompanying a correlation evaluates a null hypothesis that the relevant population correlation is zero. If the p-value falls below a pre-specified alpha level such as .05, the researcher conventionally rejects that null hypothesis. The result provides evidence of an association of the type measured by the chosen coefficient.
A small p-value does not indicate the strength of the relationship. A weak correlation can become statistically significant in a sufficiently large sample, while a stronger sample correlation may remain uncertain in a small dataset. The coefficient and p-value therefore answer different questions.
A p-value also does not represent the probability that the null hypothesis is true. Writing "p = .02 means there is a 98% chance that the variables are related" is incorrect. Statistical significance should be reported without translating it into unsupported probability claims about hypotheses.
Researchers should therefore report the coefficient alongside the p-value and, where required, a confidence interval. This allows readers to evaluate direction, magnitude, statistical evidence, and precision rather than seeing significance as a binary outcome.
Pearson vs Spearman Correlation Examples
Examples help clarify how the research question and data structure affect the choice. The scenarios below illustrate typical decisions rather than universal rules. Real datasets should still be inspected before the final analytical method is justified.
| Research Question | Data Pattern | Likely Choice |
|---|---|---|
| Is study time related to examination score? | Two quantitative variables with an approximately linear scatterplot | Pearson |
| Is satisfaction rank associated with service-quality rank? | Ordered variables with a monotonic pattern | Spearman |
| Is income associated with expenditure? | Quantitative variables with a clear linear pattern and no influential extremes | Pearson |
| Is symptom severity rank associated with quality-of-life rank? | Ordered measurements with a decreasing monotonic pattern | Spearman |
| Is experience related to productivity? | Productivity rises and then falls at high experience levels | Neither coefficient alone may adequately describe the pattern |
The final example is particularly important. Students sometimes assume that every two-variable relationship must end with either Pearson or Spearman. A complex non-monotonic relationship may require graphical description, transformation, regression modelling, or another analytical approach appropriate to the research question.
How to Report Pearson Correlation Results
A correlation write-up should identify the variables, coefficient, direction, magnitude, sample information where required, and statistical significance. It should also use language that matches the observational or experimental design. Words such as "associated with" or "correlated with" are usually safer than causal expressions when the design is correlational.
Suppose a hypothetical study of 120 students produces Pearson r = .46 between weekly study hours and examination scores, with p < .001. A concise report could state: "There was a statistically significant positive linear correlation between weekly study hours and examination scores, r = .46, p < .001, indicating that students who reported more study time tended to obtain higher examination scores."
This statement communicates the statistical pattern without claiming that additional study hours necessarily caused the higher scores. Other variables, such as prior attainment, motivation, course difficulty, or study quality, could contribute to the observed association.
When presenting correlation findings in a dissertation, the broader explanation should be developed in the discussion rather than embedded entirely in the statistical result. Epic Essay's guide to dissertation findings and discussion explains how numerical findings can be separated from their theoretical interpretation and comparison with previous research.
How to Report Spearman Correlation Results
Spearman results should be reported in a similar structure while identifying the coefficient correctly. The write-up should describe the association as monotonic or rank-based where this distinction matters. Using the symbol or name required by the institution also helps prevent Spearman results from being confused with Pearson's r.
Suppose a hypothetical study finds Spearman ρ = -.52 between ranked stress and ranked wellbeing scores, with p < .001. A suitable report could state: "A Spearman rank-order correlation identified a statistically significant negative monotonic association between stress and wellbeing scores, ρ = -.52, p < .001. Higher stress rankings tended to be associated with lower wellbeing rankings."
The negative sign communicates direction rather than poor statistical quality. A coefficient of -.52 can represent a meaningful association; it simply indicates that the variables tend to move in opposite directions. The magnitude should be interpreted according to the substantive research context.
As with Pearson correlation, the result should not be converted into a causal statement. A statistically significant Spearman coefficient demonstrates evidence of monotonic association, not proof that one variable produces changes in the other.
Common Mistakes When Choosing Pearson or Spearman
The most common mistake is choosing solely from a normality test. Students often run Shapiro-Wilk tests and automatically select Pearson when p is above .05 or Spearman when p is below .05. This ignores the relationship shape, measurement level, outliers, sample characteristics, and purpose of the analysis.
A second mistake is failing to inspect a scatterplot. A single coefficient can hide curvature, clusters, influential observations, or separate subgroups. Two datasets can produce similar correlation coefficients while having dramatically different visual patterns.
A third mistake is using Spearman whenever an outlier exists without investigating the observation. Rank correlation may reduce the numerical influence of an extreme value, but data errors still need correction and genuine unusual observations still require explanation. Statistical procedures should not be used to avoid understanding the dataset.
Finally, students frequently interpret correlation as causation. Neither Pearson nor Spearman correlation proves that one variable causes another. Causal inference requires appropriate design, temporal reasoning, control of alternative explanations, and often analytical methods beyond a bivariate correlation coefficient.
A Step-by-Step Checklist for Choosing Pearson or Spearman
A reliable decision should move from the research question to the data rather than from the SPSS significance table backwards. This creates a transparent methodological justification and reduces the temptation to select whichever coefficient produces the preferred result.
Before conducting the final analysis, work through the following sequence:
- Define exactly what relationship the research question asks about.
- Identify the measurement level of both variables.
- Determine whether meaningful numerical distances or primarily ranks are being analysed.
- Check the independence and structure of observations.
- Inspect descriptive statistics and data quality.
- Examine an appropriate scatterplot.
- Determine whether the relationship appears linear, monotonic, or neither.
- Investigate influential outliers rather than automatically deleting them.
- Consider the distributional assumptions required for the planned inference.
- Choose Pearson for an appropriate linear quantitative relationship or Spearman for an appropriate monotonic rank-based relationship.
- Report the coefficient, direction, magnitude, and p-value clearly.
- Interpret association without making unsupported causal claims.
This process also provides material for the methodology chapter. Instead of writing only that "Spearman correlation was used," the researcher can explain why the variable characteristics and relationship structure justified that choice.
Choosing Pearson or Spearman Correlation with Statistical Justification
The Pearson vs Spearman correlation decision should not be reduced to a single normality rule. Pearson's r is designed to summarise linear relationships using original quantitative values, whereas Spearman's rho summarises monotonic relationships through ranks. The distinction concerns what kind of association is being measured as much as it concerns statistical assumptions.
A defensible choice therefore combines measurement level, research design, scatterplot shape, outliers, distributional considerations, and the purpose of the analysis. Pearson is often appropriate when quantitative variables display a meaningful linear relationship and its analytical conditions are sufficiently supported. Spearman becomes valuable when ranking is substantively appropriate, the relationship is monotonic rather than linear, or extreme numerical values make a rank-based analysis more informative.
Whichever coefficient is selected, interpretation should report its direction and magnitude alongside statistical evidence and remain consistent with the research design. Correlation tells researchers how variables vary together; it does not establish why that relationship exists. By choosing the coefficient from the structure of the data rather than from the desired p-value, students can produce correlation analyses that are both statistically defensible and academically credible.
Comments