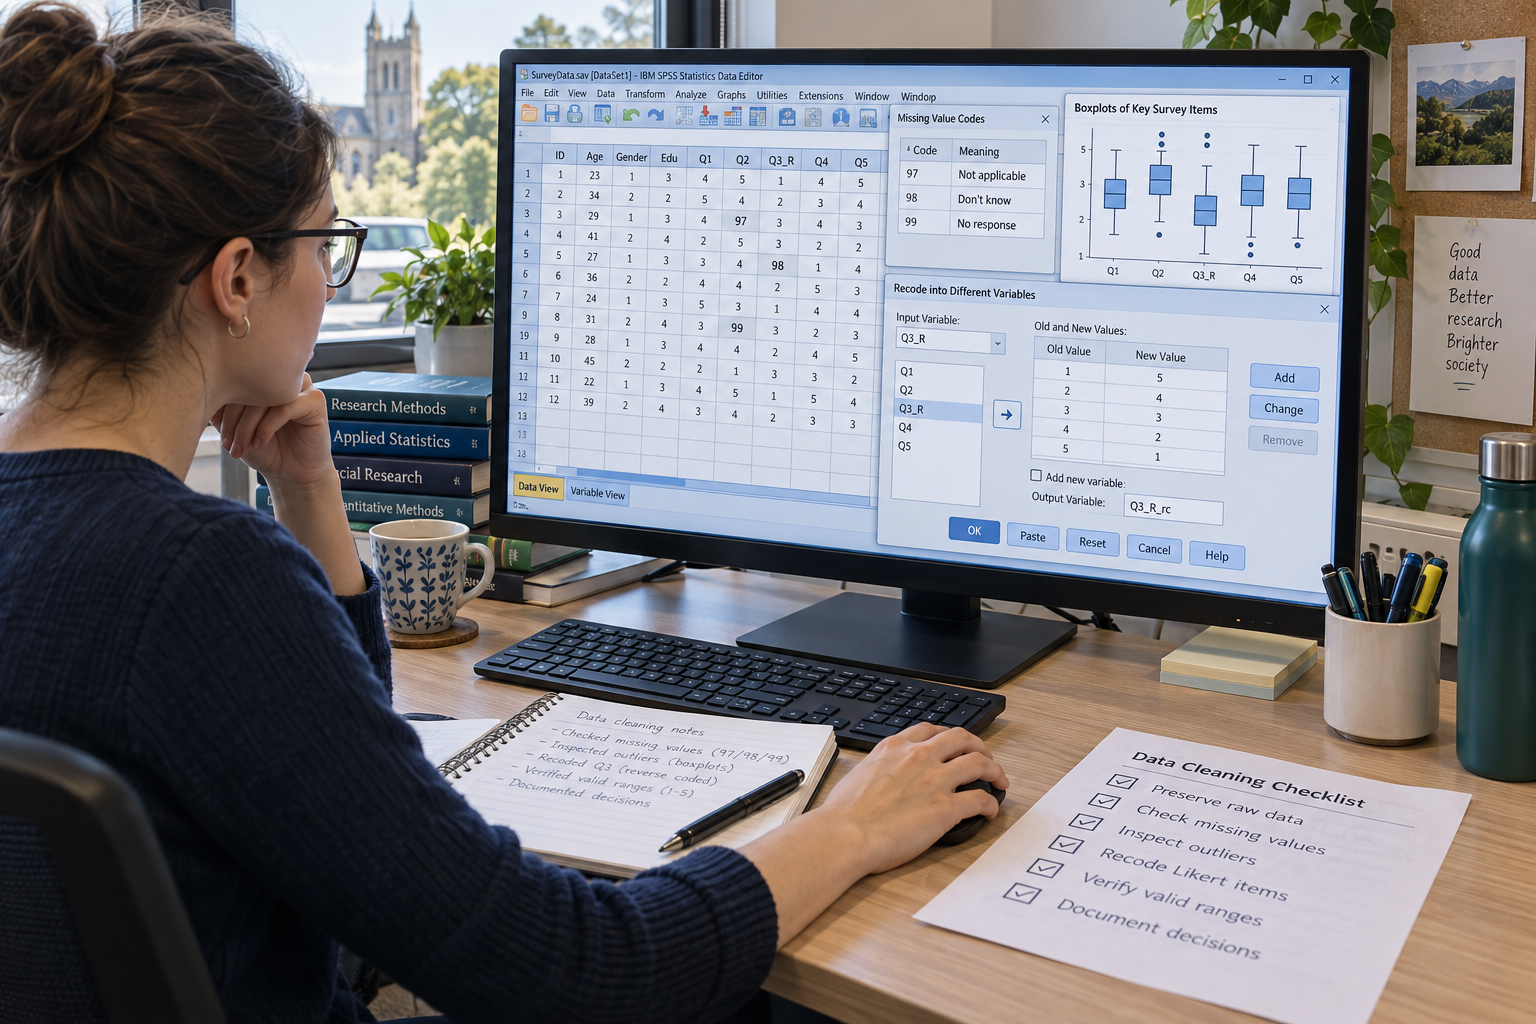
Survey research often appears straightforward: distribute a questionnaire, export the responses, open the file in SPSS, and begin analysing. In practice, raw survey data are rarely ready for inferential statistics. Respondents may skip questions, online platforms may export text instead of numeric codes, reverse-worded items may still point in the wrong direction, impossible values may have been entered manually, and a small number of unusual cases can substantially influence means, correlations, or regression coefficients.
Knowing how to clean survey data before SPSS analysis is therefore a methodological requirement rather than an optional technical task. Data cleaning means checking whether the dataset accurately represents the responses that were collected and preparing those responses for the statistical procedures specified in the research design. The objective is not to make the dataset look statistically convenient, but to identify errors, document defensible transformations, and preserve legitimate variation.
A strong dissertation should be able to explain how missing values were coded, how invalid responses were detected, whether reverse-scored questionnaire items were recoded, how outliers were evaluated, and how composite variables were created. This guide presents a systematic workflow that students can use before descriptive statistics, reliability analysis, t-tests, ANOVA, correlation, regression, or other SPSS procedures.
Why Survey Data Should Be Cleaned Before Statistical Analysis
Statistical software assumes that the numbers supplied to it represent the variables the researcher intends to analyse. SPSS cannot automatically know that a value of 77 is impossible on a 1-to-5 Likert item, that 99 means "not applicable," or that one negatively worded questionnaire item should be reverse scored. If those problems remain in the dataset, SPSS may calculate perfectly correct statistics from incorrectly prepared data.
Data cleaning also protects the interpretation of later results. A miscoded value can distort a mean, an undeclared missing-value code can alter a correlation, and an incorrectly scored reverse item can lower the reliability of an otherwise coherent scale. Problems discovered after hypothesis testing may require the entire analysis to be repeated.
Epic Essay's guide to quantitative thesis research emphasises that statistical analysis should follow structured and transparent data collection procedures. Cleaning sits between those stages: it converts collected responses into an analysable dataset while preserving the logic of the original research instrument.
Data cleaning is not the process of removing inconvenient observations. It is the process of checking whether the data have been coded, recorded, and prepared accurately enough to support the intended analysis.
What Should a Clean SPSS Survey Dataset Look Like?
In a conventional respondent-level survey dataset, each row normally represents one participant and each column represents one variable. Variables should have clear names, understandable labels, consistent coding, appropriate measurement levels, and correctly defined missing values. Questionnaire items that will later form scales should remain separately identifiable until reverse coding and reliability checks have been completed.
SPSS Variable View is especially important at this stage because it stores attributes such as variable names, types, labels, value labels, user-defined missing values, and measurement levels. A dataset may look visually acceptable in Data View while still containing incorrect variable definitions that affect later analyses.
Before analysing anything, create or retain a codebook explaining what each variable represents. The codebook should show the variable name, question wording or construct, response values, missing codes, scale direction, and any planned transformations. This makes later cleaning decisions traceable instead of relying on memory.
| Area | What to Check | Example Problem |
|---|---|---|
| Structure | One respondent per row and appropriate variables in columns | Pre-test and post-test cases stored as unrelated participants |
| Variable names | Clear and consistent naming | Several columns all labelled simply Q1 or Score |
| Value coding | Codes match questionnaire response options | Agree coded 4 in one item but 2 in another unintentionally |
| Missing values | Missing codes are identified correctly | 99 treated as a genuine survey score |
| Range | Values fall within possible limits | 7 entered for a 1-to-5 Likert item |
| Reverse items | Negatively keyed items are identified | A disagreement response points in the wrong construct direction |
| Outliers | Unusual values are checked rather than deleted automatically | Age recorded as 250 instead of 25 |
| Scale scoring | Composite scores are created only after item checks | Mean scale calculated before reverse coding |
The table shows that data cleaning involves both technical and conceptual checks. A value can be numerically valid yet still be conceptually wrong if the response coding does not match the questionnaire.
Start with a Backup of the Original Survey Data
The original exported dataset should be preserved before any transformations are performed. Keep an untouched copy of the file received from Qualtrics, Google Forms, Microsoft Forms, REDCap, Excel, or another survey platform. Cleaning should occur in a separate working file so that every change can be traced back to the source data.
This becomes particularly important when recoding variables. SPSS allows values to be recoded either into the same variable or into a different variable. Creating a new variable is often safer for important transformations because the original response remains available for comparison if an error is discovered later.
A useful naming convention makes this transparent. For example, the original negatively worded item Q8 can remain unchanged while the reverse-scored version is stored as Q8R. Likewise, a raw age variable can remain AgeRaw while a grouped version is stored separately as AgeGroup.
Never make irreversible cleaning changes to your only copy of the original survey dataset. Preserve the raw data and perform transformations in a documented working file.
Check Variable Types, Labels, and Measurement Levels
Survey exports can contain both numeric and string variables. A gender variable might appear as text such as "Female," "Male," and "Prefer not to say," while another platform may export the same categories as 1, 2, and 3. SPSS procedures differ in what they accept, so variable types should be reviewed before analysis.
Value labels can make numerically coded categories much easier to interpret. Instead of seeing only 1, 2, 3, 4, and 5 in Data View, value labels can identify them as Strongly disagree through Strongly agree. Numeric coding supports analysis while the labels preserve the substantive meaning of the responses.
Measurement level should also be checked. A participant ID is not a meaningful scale variable merely because it contains numbers. Similarly, categorical codes such as 1 = undergraduate and 2 = postgraduate should not be interpreted as continuous quantities. The SPSS measurement setting does not replace statistical judgement, but correct classification improves data organisation and reduces avoidable errors.
Run Frequency Tables to Detect Coding Errors
One of the most effective first checks for survey data is a frequency table. Frequencies reveal every observed category and therefore make impossible codes easy to identify. For a questionnaire item that should range from 1 to 5, the appearance of values such as 0, 6, 55, or 99 immediately deserves investigation.
Frequency tables are also useful for categorical variables. If the codebook states that programme level is coded 1 = undergraduate, 2 = master's, and 3 = doctoral, an unexpected category 4 may represent a legitimate option missing from the codebook or an incorrect entry. The correct response is to investigate the original questionnaire or survey export rather than simply deleting the value.
This first-pass inspection should be performed before calculating means or composite scores. Epic Essay's SPSS analysis guide stresses that interpretation depends on correctly prepared variables and an appropriate statistical procedure. Descriptive screening is therefore part of the analysis rather than a separate administrative task.
How to Handle Missing Values in Survey Data
Missing survey data can occur for different reasons. A participant may accidentally skip an item, deliberately refuse to answer, encounter a question that does not apply, leave the survey early, or be routed past an item through skip logic. These situations should not automatically be represented by the same substantive response.
SPSS distinguishes between system-missing and user-defined missing values. A blank numeric field can appear as system-missing, whereas researchers can designate specific numeric codes such as 97, 98, or 99 as user-missing. IBM's guidance on SPSS missing values notes that user-defined missing values are normally excluded from most calculations after they have been declared as missing.
This declaration is critical. Suppose a satisfaction item ranges from 1 to 5 and "not applicable" was exported as 99. If 99 is not defined as missing, SPSS may treat it as an ordinary numerical response, severely inflating the mean and standard deviation.
| Survey Situation | Possible Representation | Cleaning Consideration |
|---|---|---|
| Question accidentally skipped | System-missing | Confirm the platform truly exported no response |
| Respondent selected "Prefer not to answer" | Defined user-missing code | Retain the distinction if methodologically relevant |
| Question did not apply because of skip logic | Defined not-applicable code or structural missingness | Do not confuse with respondent nonresponse |
| Survey terminated before completion | Multiple missing fields | Evaluate completion rules and analytical eligibility |
| Placeholder code such as 99 | User-defined missing value | Declare it missing before statistical calculations |
The table illustrates why missingness should be understood before it is "fixed." Not applicable, refused, and accidentally omitted responses can represent different processes even if all are ultimately excluded from a particular calculation.
Check the Amount and Pattern of Missing Data
After missing codes have been identified correctly, determine how much information is missing from each variable and participant. UCLA's SPSS guidance on missing-data patterns demonstrates why researchers should examine missingness by both variable and case rather than simply noticing blank cells during analysis.
A variable with two missing responses in a sample of 400 creates a different problem from a scale item missing for 40% of participants. Similarly, one respondent skipping a single question differs from a respondent completing only the first page of a questionnaire. Reporting the overall sample size without examining the usable sample for each analysis can therefore be misleading.
The mechanism behind missingness also matters. Data may be described conceptually as missing completely at random, missing at random conditional on observed information, or missing in a way related to unobserved values. These distinctions influence whether complete-case analysis, imputation, model-based methods, or another strategy is defensible.
Students should avoid replacing every missing response with the variable mean simply because SPSS can perform the calculation. Mean substitution reduces natural variability and can distort relationships among variables. The missing-data strategy should reflect the amount, pattern, likely mechanism, research design, and requirements of the planned statistical procedure.
Perform Range Checks for Every Survey Variable
A range check asks whether each observed value is possible according to the questionnaire or measurement instrument. If age eligibility was restricted to 18–60 years, a value of 6 or 600 is impossible. If a Likert item ranges from 1 to 5, an observed value of 8 requires investigation.
Invalid values can result from manual entry mistakes, spreadsheet formatting, incorrect recoding, or problematic imports. When an impossible value is discovered, return to the original survey record where possible. If the correct response can be verified, correct the working dataset and document the change. If it cannot be recovered, treating the value as missing may be more defensible than inventing a replacement.
Range checks should be defined from the research instrument, not from what happens to appear in the dataset. If all observed ages happen to fall between 19 and 45, that does not mean the acceptable range was 19–45. The validation rule should come from the questionnaire, eligibility criteria, or variable definition.
Use Logic Checks to Find Inconsistent Responses
Some errors are not visible from ranges because each individual response is technically valid. Logic checks compare responses across variables to determine whether the combination makes sense. For example, a respondent might answer "No" to having used a service but later provide a satisfaction score for that service.
Survey routing provides another example. If only participants who answered "Yes" to employment should receive questions about working hours, a value of 40 working hours for a respondent coded as unemployed deserves investigation. The problem may reflect a survey-routing error, coding issue, or legitimate situation that requires a more nuanced variable definition.
Logical inconsistencies should not be resolved automatically. Check the questionnaire design and raw record first. In some cases, later questions intentionally permit answers that initially appear contradictory, while in other cases one response is clearly impossible under the survey structure.
Reverse Code Negatively Worded Likert Items Before Scale Scoring
Multi-item questionnaires sometimes contain negatively worded items to reduce acquiescence or capture the construct from the opposite direction. If higher scores on most items represent more of the construct, a negatively keyed item must usually be reverse scored before the items are combined into a scale.
For a 1-to-5 item, reverse coding typically changes 1 to 5, 2 to 4, 3 remains 3, 4 becomes 2, and 5 becomes 1. A general rule for a bounded integer scale is new score = minimum + maximum - original score. Students should still use the scoring instructions supplied with validated instruments where those instructions specify a particular procedure.
| Original Response Code | Reverse-Scored Code |
|---|---|
| 1 | 5 |
| 2 | 4 |
| 3 | 3 |
| 4 | 2 |
| 5 | 1 |
In SPSS, using Transform and Recode into Different Variables preserves the original item while creating a reversed copy. This is generally easier to audit than overwriting the original response. The new variable should be labelled clearly, for example Q7R rather than another ambiguous version of Q7.
Reverse coding should happen before internal-consistency analysis or composite scoring. Epic Essay's Cronbach alpha interpretation guide explains that poorly aligned scale items can weaken internal consistency. An unreversed negatively keyed item is a classic reason an otherwise coherent scale can appear unreliable.
When Should You Recode Categorical Variables?
Some survey variables need recoding because the exported format is unsuitable for the intended analysis. Text categories may need numeric codes, broad age groups may be created from a continuous age variable, or an outcome may need to be reorganised according to a prespecified analytical plan.
Recoding should not be used to manufacture statistical significance. Collapsing a five-category variable into two groups changes the information contained in the data and should therefore be justified theoretically or methodologically. Repeatedly trying different cut points until one produces p < .05 is poor analytical practice.
When recoding is necessary, retain the source variable and create a new one. IBM's SPSS documentation on recoding into different variables specifically allows transformed values to be stored in a new variable, preserving the original data for verification.
How to Detect Outliers in Survey Data
An outlier is an observation that lies unusually far from the rest of the data or behaves differently from the general pattern. In survey datasets, an outlier might be a genuinely extreme respondent, a data-entry error, an impossible value, or a case from a different population. These possibilities have very different methodological implications.
Start with descriptive statistics and graphical checks. Histograms, boxplots, scatterplots, minimum and maximum values, and standardised scores can help identify unusual cases. The NIST guidance on outliers recommends investigating unusual observations carefully because they may contain important information about the underlying process or reveal problems in data collection.
SPSS boxplots often flag observations beyond conventional interquartile-range fences. These points should be treated as candidates for investigation rather than automatic exclusions. A perfectly legitimate high-income respondent, for example, can be statistically unusual without being erroneous.
Should Outliers Be Deleted?
Outliers should not be removed simply because deleting them improves normality or changes a p-value. First determine whether the value is impossible, incorrectly entered, incorrectly coded, or genuinely observed. An obvious transcription error should be corrected from the source record when possible.
If an extreme observation is genuine, the researcher must consider its influence and relevance to the target population. Deleting valid extreme cases without a defensible rule can bias the sample and make results artificially tidy. Sensitivity analysis can sometimes be useful by comparing results with and without an influential case while transparently explaining why the comparison was performed.
The decision also depends on the intended analysis. In regression, an observation can be unusual in its outcome, predictor values, or influence on the fitted model. Consequently, univariate boxplots alone cannot identify every influential regression case. Later model diagnostics may require residuals, leverage, Cook's distance, or related statistics.
An outlier flag means "investigate this case." It does not mean "delete this respondent."
Check for Duplicate and Ineligible Survey Responses
Online surveys can contain duplicate submissions when a respondent submits more than once, refreshes the form, or deliberately participates repeatedly. Duplicate detection may involve unique IDs, timestamps, permitted technical metadata, or highly similar response patterns. The criterion should be defined before cases are removed.
Eligibility should also be checked. A survey restricted to postgraduate students should not retain a respondent who clearly identifies as outside the target population unless the approved sampling design permits that case. Screening questions should be applied consistently rather than selectively after the outcomes are inspected.
Incomplete surveys require a documented decision rule as well. A respondent missing one item should not automatically be treated in the same way as someone who answered only 10% of the questionnaire. The threshold for retaining partial cases should reflect the analytical needs and, where relevant, scoring rules of validated instruments.
Check Straight-Lining and Suspicious Response Patterns Carefully
Some respondents may choose the same answer across a long sequence of Likert items. This pattern is often called straight-lining. It can indicate disengagement, but it can also represent a genuine respondent who consistently holds the same view, particularly when questionnaire items are conceptually similar.
Response-pattern indicators should therefore be used cautiously. Extremely short completion times, logically contradictory answers, repeated identical responses across unrelated scales, and failure of prespecified attention checks may together provide stronger evidence of poor-quality responding than any one indicator alone.
Cases should not be removed simply because their responses appear unusual to the researcher. Exclusion criteria should be transparent, justifiable, and applied consistently across the dataset.
Create Composite Scale Scores Only After Cleaning Individual Items
Questionnaire scales are often constructed by summing or averaging several items. This calculation should occur only after item coding, missing values, reverse scoring, and eligibility have been checked. Otherwise, errors in one item can propagate directly into the composite score.
Researchers should also decide how many valid item responses are required before calculating a participant's scale score. Computing a mean from two answered items on a ten-item scale may not be defensible simply because SPSS can calculate it. Validated instruments often provide explicit scoring instructions that should take priority over generic rules.
Reliability analysis should then examine whether the intended items behave coherently as a scale. A surprising Cronbach's alpha, negative corrected item-total correlation, or dramatic alpha increase after item deletion can reveal remaining coding problems, especially forgotten reverse-scored items. Statistical findings should prompt investigation rather than automatic item deletion.
Document Every Important Data-Cleaning Decision
Reproducibility requires more than saving the final .sav file. Keep a cleaning log that records what was changed, why it was changed, which variables were affected, and how many cases were involved. SPSS syntax can provide an especially useful record because transformations can be rerun consistently if the raw dataset is updated.
A cleaning log might record that Q12 was reverse coded to Q12R, values of 99 were defined as missing for Q4–Q10, two impossible age values were checked against source records, and three duplicate submissions were removed according to a prespecified ID rule. This creates an audit trail that can be explained in the dissertation methodology without listing every mouse click.
The methodology chapter should summarise decisions that could influence the results. Epic Essay's dissertation methodology example demonstrates the importance of explaining how quantitative data were collected and analysed clearly enough for readers to evaluate the research process.
| Issue | Action | Reason | Record to Retain |
|---|---|---|---|
| Q6 contained code 99 | Defined 99 as user-missing | Questionnaire defined 99 as Not applicable | Codebook and SPSS missing-value definition |
| Q12 was negatively worded | Created Q12R | Scale required all items to point in the same direction | Original Q12 and recoding syntax |
| Age = 250 | Checked source and corrected to 25 | Verified data-entry error | Cleaning log entry |
| Two identical respondent IDs | Applied prespecified duplicate rule | Duplicate submission confirmed | Case identifiers and decision rule |
| Extreme valid income | Retained and assessed for influence | No evidence of coding or entry error | Outlier diagnostic record |
A transparent cleaning log protects the credibility of the study because transformations can be distinguished from arbitrary alterations made after statistical results were seen.
A Step-by-Step Survey Data Cleaning Workflow Before SPSS Analysis
A consistent cleaning sequence reduces the risk of correcting one issue while accidentally creating another. The exact workflow can vary by research design, but the following order works well for many student survey datasets.
- Save an untouched copy of the original survey export.
- Create a codebook for every variable and response code.
- Check that rows represent the correct analytical cases.
- Review variable names, labels, data types, and measurement levels.
- Run frequencies for categorical and Likert-type variables.
- Check minimum and maximum values for continuous variables.
- Compare observed codes with the questionnaire's permitted responses.
- Define system and user-missing values correctly.
- Calculate missingness by variable and participant.
- Investigate patterns of missing data before choosing a treatment method.
- Perform range and cross-variable logic checks.
- Identify duplicate or ineligible submissions using prespecified rules.
- Reverse score negatively keyed items into new variables.
- Recode categories only where the analytical plan justifies doing so.
- Inspect boxplots, histograms, and descriptive statistics for unusual values.
- Investigate outliers against the source data before considering exclusion.
- Apply documented rules for incomplete questionnaires.
- Create composite scale scores only after item-level cleaning.
- Run reliability checks for multi-item scales where appropriate.
- Save the cleaned dataset under a new version name.
- Retain syntax or a detailed cleaning log so every transformation can be reproduced.
This workflow should be completed before the main hypothesis testing begins. Assumption checks specific to t-tests, ANOVA, regression, correlation, or other procedures then follow using the cleaned analytical dataset.
Common Survey Data Cleaning Mistakes to Avoid
One common mistake is leaving missing-value codes such as 99 or -9 as ordinary numeric values. Unless those codes are explicitly defined as missing, SPSS may include them in calculations. A mean of a five-point scale can therefore become meaningless even though the software produces no error message.
Another mistake is overwriting original variables during recoding. If a reverse-scoring or categorisation rule is entered incorrectly, reconstructing the original responses becomes difficult. New variables provide a safer and more transparent audit trail.
Students also sometimes delete every observation flagged by a boxplot. This confuses unusual values with erroneous values. Legitimate outliers may contain important information and should be investigated before any exclusion decision.
Finally, researchers can become so focused on statistical cleaning that they alter legitimate data to make assumptions look better. Removing inconvenient cases, repeatedly changing category boundaries, or transforming variables simply to obtain significance undermines the credibility of the research.
The purpose of cleaning is to improve data accuracy, not to manufacture cleaner-looking or more statistically significant results.
How to Report Data Cleaning in a Dissertation Methodology
The methodology should explain the important cleaning decisions without becoming a diary of every SPSS operation. Report how the data were screened, how invalid and missing values were treated, whether incomplete cases were excluded, how reverse items were coded, and how composite measures were created. Decisions with the potential to change the analytical sample deserve particular attention.
A concise example might state that survey responses were screened using frequency and range checks, designated missing-response codes were defined as missing in SPSS, negatively keyed scale items were reverse scored before composite calculation, and unusual observations were inspected against source records rather than removed automatically. The methodology can then explain any case-exclusion rule and the final sample available for analysis.
If missing-data treatment or outlier decisions materially affected the results, these choices may also need sensitivity analysis or discussion as limitations. Transparency is more credible than presenting a cleaned dataset as though no judgement was required during preparation.
Preparing Clean Survey Data for Reliable SPSS Results
Cleaning survey data before SPSS analysis requires more than removing blank rows. A defensible workflow checks the dataset's structure, coding, missing-value definitions, ranges, logical consistency, reverse-scored items, duplicate submissions, incomplete cases, outliers, and scale construction before the main statistical tests are performed.
Missing values should be identified according to what they actually represent rather than replaced automatically. Outliers should be investigated rather than deleted mechanically. Recoding should preserve the original data wherever possible, and composite scores should be calculated only after item direction and missingness have been checked.
The strongest survey analysis is therefore built on a documented chain from questionnaire to codebook, raw export, cleaned dataset, composite variables, and final statistical model. When each cleaning decision is reproducible and theoretically justified, SPSS output becomes easier to trust, easier to interpret, and much easier to defend in a dissertation methodology or results chapter.
Comments