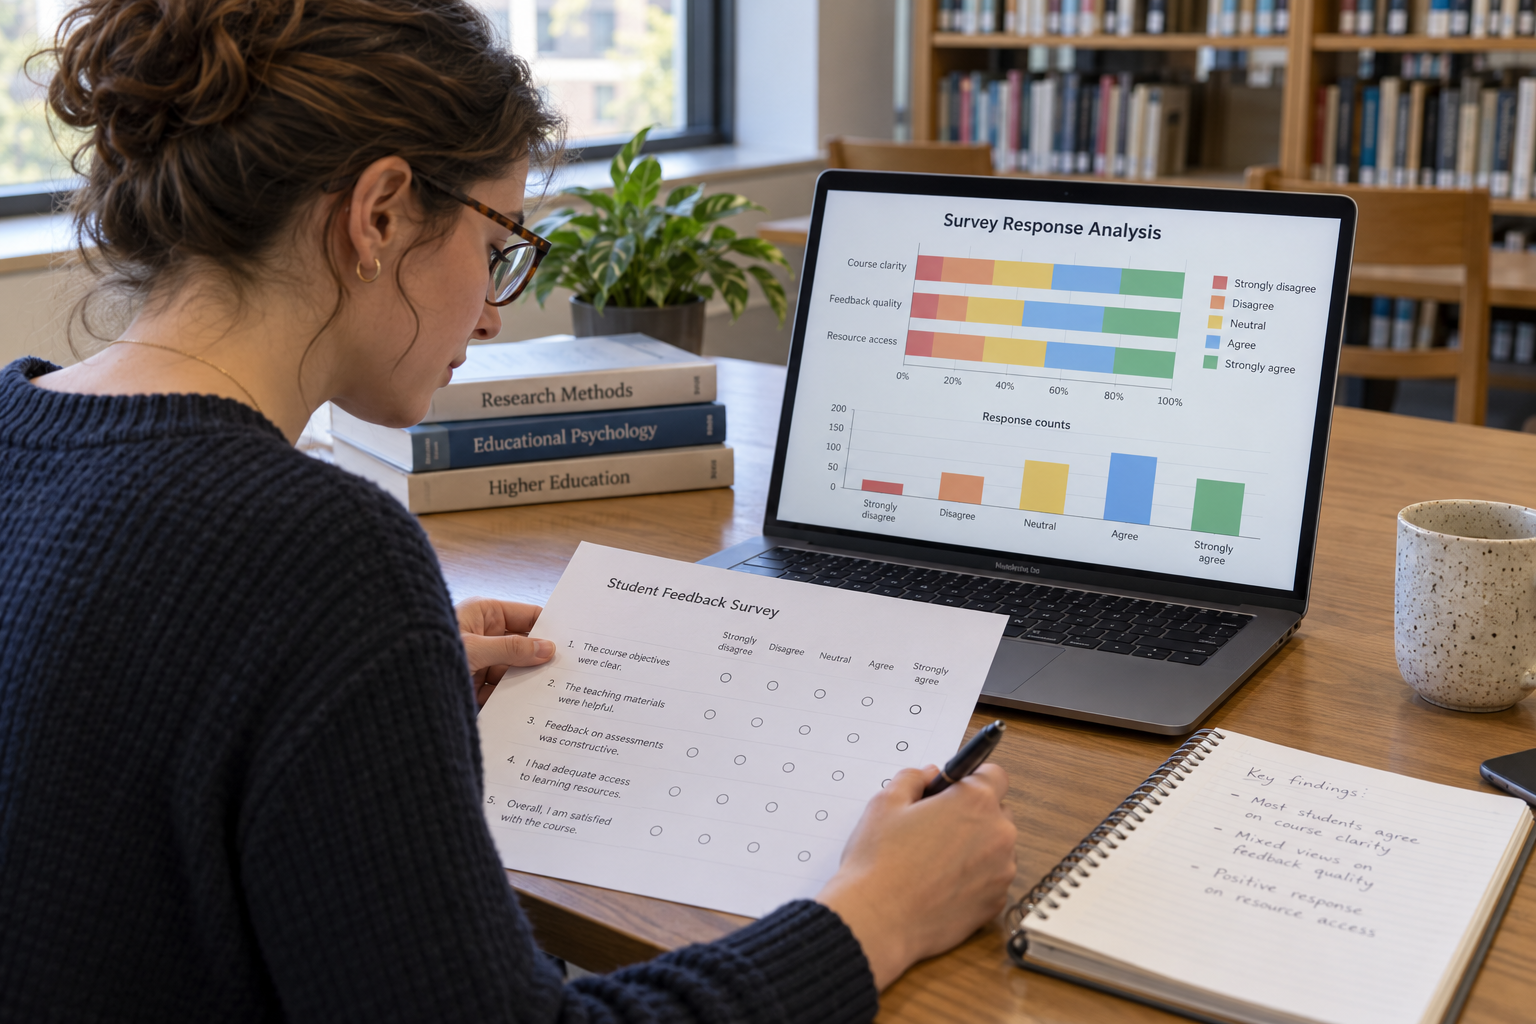
Questionnaires frequently need to measure concepts that cannot be observed directly. Researchers studying student satisfaction, employee motivation, trust, perceived usefulness, academic engagement, service quality, or attitudes cannot usually represent these constructs with a simple yes-or-no question. Likert scale questions provide a structured way for respondents to indicate degrees of agreement, frequency, satisfaction, importance, or another ordered response.
Using a Likert scale, however, involves more than placing five options beneath a statement. The wording of each item, number and meaning of response categories, treatment of neutral responses, direction of scoring, relationship between individual items and the wider construct, and planned statistical analysis all influence the quality of the resulting evidence. A poorly designed scale can produce numerical data that appear precise while measuring the intended construct inadequately.
This guide explains Likert scale questions from questionnaire design through data analysis. It distinguishes individual Likert-type items from multi-item Likert scales, provides practical examples, explains five-point and seven-point response formats, examines scoring and reverse-coded items, and shows how reliability and statistical analysis should be approached. The aim is to help university students design scales that are methodologically defensible rather than simply convenient to administer.
What Is a Likert Scale Question?
A Likert-type question presents respondents with an ordered set of response categories representing increasing or decreasing levels of a particular dimension. Agreement is the most familiar example, with responses ranging from strongly disagree to strongly agree. The same general structure can also measure frequency, satisfaction, importance, confidence, likelihood, or other ordered judgments when the labels match the construct being investigated.
A useful distinction exists between a single Likert-type item and a Likert scale composed of several related items. One statement such as "I am satisfied with the academic support provided by my university" produces one ordered response. A broader student satisfaction scale might contain several items addressing academic support, feedback, learning resources, communication, and other theoretically relevant dimensions before combining appropriate responses into a composite measure.
This distinction matters because many research constructs are too broad to be represented adequately by one question. Epic Essay's guide to operational definitions of variables explains how abstract constructs must be translated into observable indicators before measurement. Likert items are one possible measurement tool within that larger operationalisation process rather than a substitute for defining the construct itself.
A Likert response format does not automatically create a valid scale. The items must first represent the construct the researcher intends to measure.
Likert Scale Examples for University Research
The response labels used in a Likert question should correspond directly to what the question asks respondents to judge. Agreement categories should measure agreement, while frequency questions should use categories representing frequency. Mixing dimensions within the same response scale can make interpretation difficult because respondents are no longer answering along a consistent continuum.
For example, a dissertation investigating online learning could measure perceived usefulness using agreement statements, frequency of platform use using frequency categories, and satisfaction with support using satisfaction categories. Although all three can contain five ordered responses, they represent different constructs. Researchers should therefore describe them accurately rather than calling every ordered questionnaire response an agreement scale.
The following examples illustrate common Likert-style response formats and their appropriate uses.
| Measurement Purpose | Example Question or Statement | Example Response Categories |
|---|---|---|
| Agreement | The online learning platform is easy to use. | Strongly disagree, Disagree, Neither agree nor disagree, Agree, Strongly agree |
| Frequency | How often do you participate in online class discussions? | Never, Rarely, Sometimes, Often, Always |
| Satisfaction | How satisfied are you with the feedback provided by your lecturer? | Very dissatisfied, Dissatisfied, Neither satisfied nor dissatisfied, Satisfied, Very satisfied |
| Importance | How important is flexible access to recorded lectures? | Not at all important, Slightly important, Moderately important, Very important, Extremely important |
| Confidence | How confident are you in analysing quantitative research data? | Not at all confident, Slightly confident, Moderately confident, Very confident, Extremely confident |
The table demonstrates that the number of response categories alone does not define what is being measured. The labels establish the meaning of the response continuum. Clear labels also reduce the amount of interpretation respondents must perform when deciding which option best represents their position.
How to Write Effective Likert Scale Questions
Each Likert item should measure one interpretable idea. A statement such as "My lecturer provides clear and timely feedback" combines clarity and timeliness. A respondent may consider the feedback clear but consistently late, making it impossible to determine what an agreement or disagreement response actually represents. The two concepts should therefore be measured with separate items when both are relevant.
Wording should also be neutral. A statement such as "The university's excellent support services help students succeed" embeds a positive evaluation before the participant responds. A more defensible item would focus on one specific proposition, such as whether academic support helps the respondent address study difficulties, without telling the respondent how the service should be perceived.
Items should be understandable to the target population without requiring unnecessary specialist terminology. Complex wording can introduce measurement error because respondents may interpret the same statement differently. Researchers should also be cautious with absolute words such as "always" and "never" unless those absolutes are genuinely necessary for the construct.
A useful item-writing check includes the following questions:
- Does the item measure only one idea?
- Is the wording neutral rather than leading?
- Can the intended respondents understand the terminology?
- Does the statement relate directly to the construct being measured?
- Are vague qualifiers and unnecessary absolutes avoided?
- Can every response option be interpreted consistently?
These rules should be applied before data collection rather than used to repair problematic items afterwards. Once respondents have answered an ambiguous question, statistical software cannot determine which interpretation they had in mind. Questionnaire quality therefore begins with measurement design rather than with the eventual statistical analysis.
Should You Use a 5-Point or 7-Point Likert Scale?
Five-point and seven-point scales are both common in academic research, and neither is automatically correct for every study. A five-point agreement scale might run from strongly disagree to strongly agree with a neutral midpoint. A seven-point version introduces additional intermediate categories, potentially allowing respondents to express more finely differentiated positions.
The choice should reflect the construct, target population, established measurement instrument, and analytical purpose. More categories can provide greater differentiation, but additional distinctions are useful only if respondents can meaningfully distinguish between them. A scale becomes less useful if participants cannot consistently interpret the difference between several closely spaced response categories.
Researchers using an established validated scale should be especially cautious about altering its response format. Changing a five-point instrument into a seven-point instrument, removing a midpoint, rewriting response anchors, or modifying items can change the measurement properties of the instrument. Such changes may therefore require justification and additional evaluation rather than being treated as cosmetic formatting decisions.
| Consideration | 5-Point Scale | 7-Point Scale |
|---|---|---|
| Number of choices | Lower | Higher |
| Response differentiation | Moderate | More finely differentiated |
| Respondent simplicity | Generally straightforward | Requires distinguishing more categories |
| Neutral midpoint | Can be included | Can be included |
| Best choice | Depends on construct and instrument | Depends on construct and instrument |
The correct conclusion is not that seven categories are inherently more academic or that five categories are always easier. Scale length should be justified according to measurement needs. Where previous validated research already uses a particular response format successfully with a comparable population, preserving that format can also strengthen comparability.
Should a Likert Scale Include a Neutral Midpoint?
A neutral midpoint gives respondents an option between the positive and negative sides of a scale, such as "neither agree nor disagree." It can be appropriate when neutrality represents a legitimate position on the construct. A participant may genuinely hold no positive or negative view, and forcing that participant to select a direction can introduce measurement error.
However, midpoint responses are not always expressions of genuine neutrality. Some respondents may select the middle option because they are uncertain, lack sufficient knowledge, do not understand the question, or want to complete the questionnaire quickly. These situations represent different states even though they can produce the same recorded response.
Removing the midpoint does not automatically solve the problem. A forced-choice scale requires respondents to select one side even when their genuine position is neutral. Researchers should therefore decide whether neutrality is conceptually meaningful for the question rather than removing or retaining a midpoint merely because a preferred survey template uses one.
An additional "not applicable" or "do not know" option may sometimes be necessary, but it should not be confused with the midpoint. Someone who has never used a university counselling service cannot meaningfully report neutral satisfaction with it. Distinguishing lack of experience from genuine neutrality improves the interpretability of the resulting data.
How to Score Likert Scale Questions
Likert responses are commonly assigned numerical codes to support data management and analysis. A five-point agreement item might be coded from 1 for strongly disagree through 5 for strongly agree. These numbers provide an ordered representation of the response categories, but researchers should remember that numerical coding does not by itself establish equal distances between categories.
Multi-item instruments may combine responses into a total or average score when the items have been designed and justified as indicators of the same construct. For example, five items measuring academic engagement could potentially be combined into an engagement score after appropriate theoretical and measurement checks. The resulting composite measure then represents more than any individual response.
Before combining items, researchers need to verify that all items point in the same scoring direction. If high scores usually indicate greater engagement but one item is phrased so that agreement represents lower engagement, that item requires appropriate treatment before the scores are combined. Otherwise, the item will mathematically work against the direction of the other items.
A simple five-point coding structure can be represented as follows.
| Response | Example Code |
|---|---|
| Strongly disagree | 1 |
| Disagree | 2 |
| Neither agree nor disagree | 3 |
| Agree | 4 |
| Strongly agree | 5 |
This coding convention is convenient but should not be mistaken for a universal requirement. Researchers may use different numerical codes provided that coding is consistent, documented, and interpreted correctly. The meaning of the categories is determined by the questionnaire design, not by the spreadsheet numbers assigned to them.
What Are Reverse-Coded Likert Items?
A reverse-keyed item is phrased so that endorsement represents the opposite direction of the construct compared with other items. Suppose a scale measuring confidence contains positive items where stronger agreement indicates greater confidence. An item such as "I doubt my ability to complete difficult research tasks" moves in the opposite conceptual direction and therefore requires reverse scoring if it is to contribute to a composite score in the same direction.
For a five-point scale coded from 1 to 5, reverse scoring commonly transforms 1 into 5, 2 into 4, 3 remains 3, 4 becomes 2, and 5 becomes 1. This transformation changes the numerical direction of the item while preserving the respondent's original substantive answer. It must be completed before calculating a composite score that assumes all items point in the same direction.
Reverse-worded items have sometimes been used in an attempt to reduce automatic agreement or detect inattentive responding. However, negatively phrased items can also create confusion, especially when sentences contain complex negation. Researchers should not add reverse wording mechanically; clarity and measurement quality remain more important than creating artificial variation in sentence direction.
Never combine positively and negatively keyed items into a total score without first checking whether the required items have been reverse-coded correctly.
How to Test the Reliability of a Likert Scale
When several Likert items are intended to measure the same underlying construct, researchers often assess their internal consistency. Cronbach's alpha is one widely used coefficient for this purpose. It evaluates how closely related a set of items are as a group, helping researchers examine whether the items behave consistently enough to support their proposed use as a scale.
Reliability analysis should not be reduced to chasing a threshold. Epic Essay's Cronbach alpha interpretation guide explains that alpha is influenced by both inter-item relationships and the number of items in a scale. Very high values can sometimes reflect repetitive items rather than an exceptionally strong instrument.
Students should also avoid treating reliability as evidence of validity. A set of questions can produce highly consistent responses while systematically measuring the wrong construct. Reliability concerns consistency, whereas validity concerns whether the interpretation of the measurement is appropriate for what the study claims to measure.
Item-total statistics can help identify items that behave differently from the rest of a scale, but deletion decisions should not be based on software output alone. Removing an item because alpha increases slightly may damage the conceptual coverage of the construct. Statistical evidence should therefore be considered alongside the theory, wording, content, and original purpose of the measurement instrument.
How to Analyse Individual Likert Scale Questions
An individual Likert-type item produces ordered categorical data. The categories have a meaningful order, but the distance between adjacent responses cannot automatically be assumed to represent equal quantities in the same way as a physical measurement. This distinction is important when deciding how individual items should be summarised and analysed.
Frequencies and percentages provide a clear starting point because they show how respondents are distributed across the response categories. A student can report, for example, what proportion agreed or strongly agreed with a statement while still preserving the structure of the responses. Medians and other ordinal summaries may also be appropriate depending on the research purpose and institutional conventions.
Researchers should be cautious about automatically calculating a mean for every individual Likert item simply because the responses have been coded 1 to 5. In practice, treatment of Likert data varies across disciplines and analytical traditions. The appropriate decision should reflect whether the analysis concerns a single ordinal item or a defensibly constructed multi-item scale, as well as the assumptions of the planned statistical procedure.
A basic workflow for individual items can therefore include:
- Check coding and identify missing or invalid responses.
- Produce frequencies and percentages for each response category.
- Inspect the distribution for clustering, skew, or unusual patterns.
- Select summary measures appropriate to the level and purpose of measurement.
- Choose inferential procedures only after considering their assumptions.
- Report the results in language that accurately reflects what respondents were asked.
This approach prevents the coding system from dictating the statistical method. Numbers assigned to response categories make data easier to process, but the measurement properties and research question should determine how those numbers are analysed.
How to Analyse Multi-Item Likert Scale Data
Analysis changes when several items have been deliberately developed or adopted to measure a common construct. After checking item direction, missing values, reliability, and the measurement structure, researchers may calculate a composite score according to the instrument's established scoring procedure. This may involve summing responses or calculating an average across relevant items.
A composite score can provide a more stable representation of a construct than a single question because information is drawn from multiple indicators. However, combining items is defensible only when there is a theoretical and measurement basis for treating them together. Researchers should not average unrelated questionnaire questions merely because all of them use the same five-point response format.
The subsequent statistical analysis depends on the research question and characteristics of the composite measure. Descriptive statistics may summarise the overall score, while correlation, regression, group comparisons, or other procedures may be considered when their assumptions and the research design support them. Epic Essay's guide to quantitative thesis research and data analysis provides broader context for selecting statistical techniques in survey-based studies.
Students should explain these decisions in their methodology rather than simply stating that questionnaire data were analysed in SPSS, R, Excel, Stata, or another package. Epic Essay's methodology section guide notes that survey research should identify the questionnaire administration process, scale types, and analytical techniques. Software performs calculations; methodological justification explains why those calculations are appropriate.
Common Likert Scale Design and Analysis Mistakes
One frequent mistake is treating every question with five response options as a Likert scale. Multiple-choice questions, numerical ratings, and categorical responses may also contain five options, but their measurement logic can differ substantially. Researchers should identify the construct and response continuum rather than classifying an item according to the number of boxes displayed on the questionnaire.
A second problem is inconsistent response labelling. If 1 means strongly disagree in one section but strongly agree in another without a clear reason, data coding becomes vulnerable to error. Similarly, switching casually between agreement, satisfaction, frequency, and importance labels can confuse respondents and make composite scoring inappropriate.
A third mistake is combining items before checking whether they genuinely represent the same construct. A questionnaire may contain ten Likert-type items without those ten items constituting one coherent scale. Theoretical justification, instrument design, reliability evidence, and where appropriate further measurement analysis should determine which items can reasonably be combined.
Finally, students sometimes allow statistical software to determine the research story. A mean, correlation, reliability coefficient, or significance value does not interpret itself. The analysis must remain connected to the original construct, item wording, research question, and limitations of the measurement instrument.
How to Report Likert Scale Data in a Dissertation
The methodology chapter should explain how the scale was designed or sourced, what construct it measures, how many relevant items it contains, what response format was used, and how responses were coded. If an established instrument was adopted or adapted, its source and any modifications should be documented. Newly developed scales require a clear explanation of item development, review, piloting, and relevant reliability or validity procedures.
The findings chapter should then report the evidence at the level appropriate to the research questions. Individual items may be presented through frequencies, percentages, or carefully selected tables, while composite scales may require descriptive statistics and further inferential analysis. Large blocks of raw statistical output should not replace selective academic reporting.
Interpretation should also use language proportionate to the evidence. If respondents agreed that a learning platform was easy to use, the finding concerns their reported perception of usability. It does not by itself prove that the platform is objectively usable, improve academic achievement, or cause greater engagement unless the study contains evidence capable of supporting those additional claims.
Clear reporting therefore preserves the chain from construct to item, response to score, score to analysis, and analysis to conclusion. When those stages are transparent, readers can judge whether the evidence supports the claims being made rather than simply accepting numerical output at face value.
Designing Likert Scale Questions That Produce Defensible Data
Strong Likert scale questions begin with a clearly defined construct rather than a preferred set of response boxes. Researchers need to decide what they intend to measure, identify suitable indicators, write focused and neutral items, and select response categories that represent the intended continuum. Decisions about midpoints, scale length, reverse coding, and composite scoring should then follow from that measurement logic.
Analysis requires the same level of care. Individual Likert-type items and multi-item scales should not automatically be treated as identical forms of data, and numerical coding does not eliminate the need to consider measurement assumptions. Reliability analysis can provide useful evidence about internal consistency, but it does not establish validity or replace theoretical justification.
For dissertation and university research, the most defensible approach is to plan analysis before collecting responses, preserve the structure of established instruments where appropriate, document all scoring decisions, and report findings according to what the scale can genuinely support. When design and analysis are connected in this way, Likert scale data become meaningful research evidence rather than simply a collection of numbers from a questionnaire.
Comments