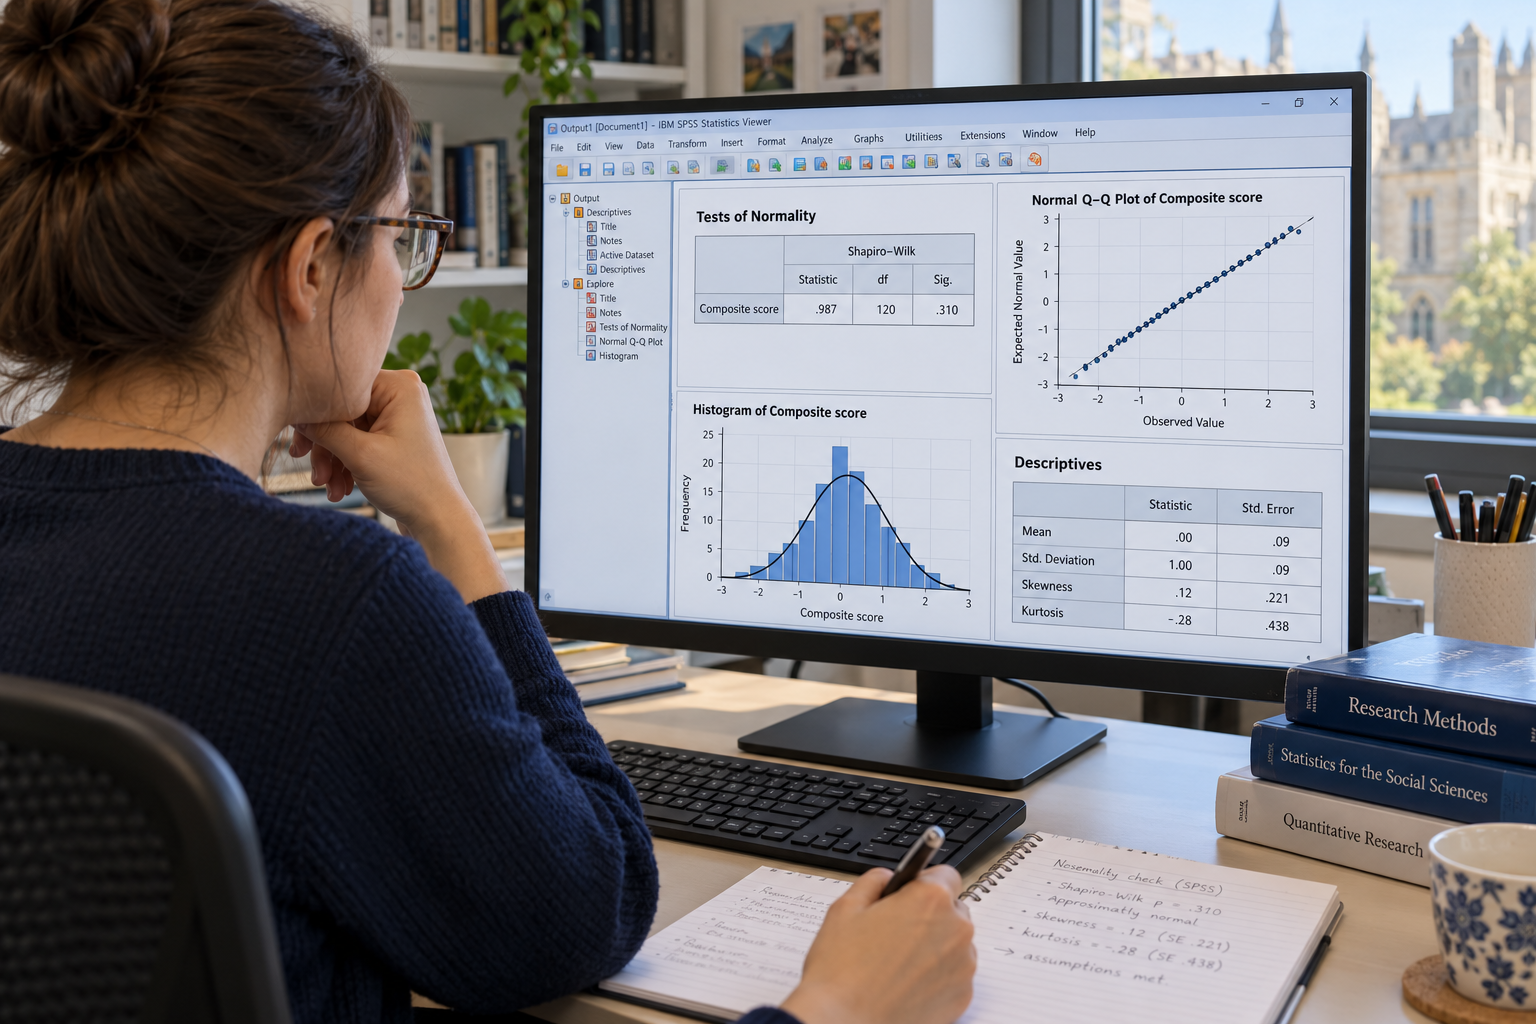
Normality is one of the most frequently checked assumptions in quantitative university research, yet it is also one of the most frequently misunderstood. Students often run a Shapiro-Wilk test in SPSS, find a p-value below .05, and immediately conclude that their data are unusable for parametric analysis. Others rely on a single skewness cutoff or expect a histogram to reproduce a perfect bell-shaped curve.
Normality tests are more useful when they are treated as a collection of diagnostic evidence rather than a pass-or-fail exercise. Shapiro-Wilk tests whether the observed distribution departs detectably from normality, Q-Q plots reveal the shape and location of departures, and skewness and kurtosis quantify particular characteristics of distribution shape. Sample size, outliers, research design, and the statistical test ultimately being used also affect how these diagnostics should be interpreted.
This guide explains Shapiro-Wilk, Q-Q plots, skewness and kurtosis in practical terms, including how to check them in SPSS and how to report the findings in a dissertation. More importantly, it explains what should actually be normally distributed for different analyses, why p < .05 does not automatically require a non-parametric test, and how to make a defensible decision when several normality indicators appear to disagree.
What Does Normality Mean in Statistical Analysis?
A normal distribution is a continuous, symmetrical distribution in which observations cluster around the centre and become progressively less frequent toward both tails. In an ideal normal distribution, the mean, median, and mode coincide, skewness is zero, and the distribution has a characteristic bell-shaped form. Many classical statistical procedures use normal-distribution theory when deriving standard errors, confidence intervals, and hypothesis tests.
However, statistical analysis rarely requires every raw variable in a dataset to look perfectly normal. The relevant assumption depends on the analytical procedure. For example, a paired samples t-test concerns the distribution of the paired difference scores, while ordinary linear regression commonly focuses on the behaviour of the model residuals for conventional inference rather than demanding normally distributed predictor variables.
This distinction is important because students often test every column in SPSS and treat any significant Shapiro-Wilk result as evidence that the planned analysis is invalid. Epic Essay's guide to choosing statistical tests explains that assumptions must be interpreted in relation to the particular statistical method, research design, and variables involved.
Normality is an assumption attached to a statistical model or sampling distribution, not a universal requirement that every variable in a dataset must form a perfect bell curve.
What Is the Shapiro-Wilk Test?
The Shapiro-Wilk test evaluates whether a sample shows evidence of departure from a normal distribution. Its null hypothesis is that the data are consistent with normality. The test produces a W statistic and a p-value, which SPSS displays in the Tests of Normality table.
When p is below the chosen significance level, commonly .05, the test provides evidence against the null hypothesis of normality. When p is above .05, researchers fail to reject that null hypothesis. The latter result should not be described as proof that the population distribution is perfectly normal, because a non-significant test may also reflect limited statistical power.
A common interpretation framework is therefore:
- p < .05: evidence of a detectable departure from normality.
- p ≥ .05: insufficient evidence to reject normality.
The wording matters. Saying that p = .21 "proves the data are normally distributed" is stronger than the test supports. A more defensible statement is that the Shapiro-Wilk test did not identify a statistically significant departure from normality.
Why Sample Size Changes the Meaning of Shapiro-Wilk
Shapiro-Wilk is sensitive to sample size. With a small sample, the test may have limited ability to detect genuine departures from normality. A non-significant result can therefore occur even when a histogram or Q-Q plot shows noticeable skewness, heavy tails, or unusual observations.
With a large sample, the opposite problem can occur. Very small deviations from a mathematically perfect normal distribution can become statistically detectable even when those deviations have little practical consequence for the planned analysis. A large dataset can therefore produce p < .001 while the Q-Q plot appears reasonably straight and the statistical procedure remains sufficiently robust for the research purpose.
This is why normality should not be assessed using the Shapiro-Wilk p-value alone. Statistical significance in a normality test tells you that a departure is detectable; it does not tell you whether that departure is large enough to threaten the validity of the analysis.
Do not automatically abandon a parametric test simply because Shapiro-Wilk produces p < .05. Examine the distribution, sample size, outliers, Q-Q plot, and the robustness of the intended statistical procedure.
What Is a Q-Q Plot and How Do You Read It?
A normal Q-Q plot compares the observed quantiles of the sample with the quantiles expected under a normal distribution. If the observed distribution is approximately normal, the plotted points should lie reasonably close to the diagonal reference line. The plot therefore allows researchers to see not only whether a departure exists but how the departure occurs.
The Curtin University SPSS normality guide demonstrates this graphical interpretation by combining the Shapiro-Wilk test with histograms and Q-Q plots. Points that remain reasonably close to the reference line support approximate normality, whereas systematic curvature suggests a structured departure.
Different patterns provide different information. A pronounced curve concentrated toward one side can indicate skewness, while systematic departures at both tails may indicate heavier or lighter tails than expected. A small number of isolated points far from the line can indicate possible outliers rather than a broad distributional problem.
Q-Q plots are especially valuable in large samples because they help distinguish statistically detectable but minor departures from obvious and potentially important distributional problems. They also prevent normality assessment from being reduced to a single significance threshold.
What Does Skewness Tell You About Normality?
Skewness describes asymmetry in a distribution. A perfectly symmetrical normal distribution has skewness of zero. Positive skewness indicates a longer right-hand tail, while negative skewness indicates a longer left-hand tail.
For example, personal income frequently shows positive skew because most observations occur at lower or middle values while a smaller number of very high incomes extend the upper tail. An unusually easy examination might instead produce negative skew if most students receive high marks and a smaller number of low scores form the left tail.
SPSS reports skewness together with its standard error. IBM's SPSS documentation identifies skewness as a measure of asymmetry and notes that values substantially larger than their standard errors can indicate departure from symmetry. Some researchers therefore calculate a skewness z statistic by dividing skewness by its standard error.
However, fixed rules such as absolute skewness below 1, 2, or another value should be treated as rough heuristics rather than universal requirements. The consequences of skewness depend on sample size, the analysis being performed, the severity of the asymmetry, and whether extreme observations are responsible for the pattern.
What Does Kurtosis Tell You?
Kurtosis describes characteristics of the tails of a distribution and the occurrence of extreme observations relative to a normal distribution. SPSS reports excess kurtosis, meaning that a normal distribution has a kurtosis value of zero rather than three. Positive values indicate more extreme tail behaviour than the normal reference distribution, while negative values indicate lighter tails.
This point matters because different textbooks and software can use different kurtosis conventions. A student may encounter a source saying that normal kurtosis equals three while SPSS displays values relative to zero. Both conventions can refer to the same distribution but use different definitions.
IBM's SPSS documentation on skewness and kurtosis explicitly states that its reported normal-distribution kurtosis is zero and describes this as excess kurtosis. Students should therefore interpret SPSS output according to the software's definition rather than comparing it blindly with a threshold taken from another program.
Kurtosis is particularly relevant when distributions contain unusually extreme observations. Even a fairly symmetrical distribution can have heavy tails, meaning that skewness alone cannot provide a complete assessment of normality.
| Diagnostic | Main Question | Useful Evidence | Main Limitation |
|---|---|---|---|
| Shapiro-Wilk | Is there statistically detectable departure from normality? | W statistic and p-value | Strongly affected by sample size |
| Q-Q plot | How does the distribution depart from normality? | Pattern relative to the diagonal line | Requires informed visual judgement |
| Skewness | Is the distribution asymmetric? | Direction and degree of asymmetry | Does not describe all forms of non-normality |
| Kurtosis | Are the tails unusually heavy or light? | Extent of tail behaviour and extreme observations | Can be influenced strongly by extreme cases |
No row in the table provides a complete normality diagnosis on its own. The strongest assessment combines formal testing, graphical evidence, distribution-shape statistics, and knowledge of the intended analysis.
Should Skewness and Kurtosis Be Divided by Their Standard Errors?
SPSS reports standard errors for both skewness and kurtosis. Dividing each statistic by its standard error produces an approximate z statistic that can be compared with conventional critical values such as approximately ±1.96 for a two-sided 5% criterion. IBM documentation notes this approach as one way of assessing whether skewness or kurtosis departs substantially from a normal reference.
For example, suppose SPSS reports skewness = 0.54 and a standard error of 0.24. The approximate z value is 2.25, which exceeds 1.96. This suggests statistically detectable asymmetry under that diagnostic approach.
The same sample-size problem still applies. Standard errors become smaller as sample size grows, so relatively small departures can generate large z statistics in large datasets. Students should therefore avoid replacing one rigid significance test with another rigid significance test.
Skewness and kurtosis z values can contribute to the evidence, but the histogram, Q-Q plot, sample size, outliers, and intended model remain necessary for a defensible interpretation.
Which Variable Should Actually Be Tested for Normality?
The answer depends on the statistical analysis. Testing every raw variable simply because it appears in SPSS can lead to unnecessary transformations or inappropriate changes in analytical strategy. Normality should be assessed at the level relevant to the inferential procedure.
| Analysis | Relevant Normality Consideration | Common Student Error |
|---|---|---|
| One-sample t-test | Distribution of the quantitative outcome in the sampled population | Assuming any visible imperfection makes the test impossible |
| Independent samples t-test | Outcome distribution within the groups, especially when samples are small | Testing the pooled raw scores without considering groups |
| Paired samples t-test | Distribution of the paired difference scores | Testing pre-test and post-test variables separately instead of their differences |
| ANOVA | Model errors or outcome distributions within groups under the ANOVA assumptions | Testing only the overall dependent-variable distribution |
| Linear regression | Residual behaviour for conventional model inference | Demanding normally distributed predictors |
This distinction is particularly important in regression. UCLA's SPSS regression diagnostics guidance demonstrates normality assessment using residuals rather than demanding that every original predictor follow a normal distribution.
Students designing quantitative studies can place these diagnostics within the broader analytical sequence described in Epic Essay's quantitative thesis research guide. Statistical assumptions should be connected directly to the method chosen to answer each research question.
How to Test Normality in SPSS
SPSS provides a useful combination of formal and graphical diagnostics through the Explore procedure. This route produces descriptive statistics, normality tests, histograms, and normal Q-Q plots in one analysis. It is usually more informative than requesting a normality test without visual evidence.
The basic procedure is:
- Select Analyze.
- Select Descriptive Statistics.
- Select Explore.
- Move the variable being assessed into the Dependent List.
- If relevant, place the grouping variable into the Factor List.
- Select Plots.
- Select Histogram if a distribution graph is required.
- Select Normality plots with tests.
- Select Continue and then OK.
- Review descriptive statistics, Tests of Normality, the histogram, and the normal Q-Q plot together.
Current IBM documentation confirms that the SPSS normal-probability option produces normal and detrended Q-Q plots together with normality testing. The important analytical step occurs after SPSS generates the tables: the researcher must decide whether any observed departure is meaningful for the intended statistical procedure.
How to Interpret Normality Output in SPSS
Consider a hypothetical dissertation measuring academic stress among 150 postgraduate students. Suppose SPSS reports Shapiro-Wilk W = .981, p = .031, skewness = .38, and excess kurtosis = .21. The normal Q-Q plot shows points remaining close to the reference line with only small deviations near the upper tail.
A mechanical interpretation would state that the distribution is non-normal because p < .05. A more critical interpretation recognises that the sample is reasonably large, the skewness and kurtosis are modest, and the graphical departure is limited. Depending on the statistical procedure, these findings may not represent a practically important violation.
Now consider a second variable with W = .83, p < .001, skewness = 2.40, excess kurtosis = 8.10, and a strongly curved Q-Q plot with several extreme observations. Here, the formal test, shape statistics, and graphical diagnostics all point toward substantial non-normality. The problem deserves considerably more investigation.
| Diagnostic | Variable A | Variable B |
|---|---|---|
| Sample size | 150 | 150 |
| Shapiro-Wilk | W = .981, p = .031 | W = .830, p < .001 |
| Skewness | .38 | 2.40 |
| Excess kurtosis | .21 | 8.10 |
| Q-Q plot | Points mostly follow the reference line | Clear systematic departure with extreme observations |
| Overall assessment | Minor detectable departure requiring contextual judgement | Substantial non-normality requiring investigation |
The example demonstrates why the magnitude and shape of the departure matter more than simply counting whether a p-value crossed .05.
What Should You Do If Shapiro-Wilk Is Significant but the Q-Q Plot Looks Normal?
This situation is common in larger samples. The formal test can detect subtle departures that are difficult to see graphically and may have little effect on a robust statistical procedure. The correct response is not to ignore the Shapiro-Wilk result, but neither is it automatically necessary to discard the planned analysis.
Describe the evidence transparently. You might report that Shapiro-Wilk indicated a statistically detectable departure while graphical inspection showed only minor deviation from the theoretical normal line. Then explain why the chosen procedure remains appropriate, where such a justification is supported by the analysis and methodological literature.
The reverse situation can occur with a small sample. Shapiro-Wilk may be non-significant because statistical power is limited while a Q-Q plot reveals obvious asymmetry or a severe outlier. A non-significant test should therefore not override compelling graphical evidence.
Normality assessment works best when statistical and graphical diagnostics are interpreted together rather than made to compete for authority.
What Should You Do When Data Are Clearly Non-Normal?
The first step is to understand why the distribution is non-normal. Check for data-entry errors, impossible values, miscoded missing data, duplicate cases, and genuine extreme observations. A score entered as 500 instead of 50 can create severe apparent skewness that has nothing to do with the population being studied.
If unusual observations are genuine, they should not be deleted merely to improve a normality test. Researchers should investigate their influence and determine whether exclusion is justified by a predefined methodological rule, a measurement problem, or another defensible reason. Removing valid observations only because they make a histogram unattractive can bias the analysis.
Possible responses to genuine non-normality include:
- Using a statistical procedure that is sufficiently robust for the observed departure.
- Transforming a variable when the transformation has a meaningful analytical justification.
- Using an appropriate non-parametric procedure.
- Using robust or resampling methods where suitable.
- Reconsidering whether the selected statistical model matches the data-generating process.
The correct solution depends on the research question. A transformation changes the scale of analysis, while a non-parametric test may answer a different inferential question from its parametric counterpart. Methodological decisions should therefore be justified rather than presented as automatic SPSS corrections.
Does a Large Sample Mean You Can Ignore Normality?
Larger samples often make many classical estimators and sampling distributions more stable, and the central limit theorem helps explain why some inferential procedures can perform well even when individual observations are not normally distributed. However, "large samples solve normality" is an oversimplification.
Severe skewness, extremely heavy tails, influential outliers, dependence, heteroscedasticity, or an inappropriate model can still create important problems. A large sample can even make a poorly specified analysis appear highly statistically significant because estimates become precise around the wrong model.
The practical implication is that sample size should modify how normality diagnostics are interpreted, not determine whether diagnostics are ignored. Large datasets particularly benefit from graphical examination because formal normality tests can become hypersensitive to minor imperfections.
Good quantitative analysis asks whether the specific departure threatens the particular statistical inference being made. That is more useful than applying a universal sample-size rule.
Should You Use a Non-Parametric Test Whenever Data Are Non-Normal?
Non-parametric methods can be valuable when the assumptions of a parametric test are not defensible, but they should not be treated as automatic replacements after a significant Shapiro-Wilk test. Different procedures can target different parameters or aspects of the distribution, meaning that changing tests can also change the research question.
For example, the Mann-Whitney U test is often described casually as the non-parametric equivalent of the independent t-test. However, its interpretation is not simply "a t-test without normality." The hypotheses and assumptions governing rank-based procedures should be understood before making the switch.
Similarly, the Wilcoxon signed-rank test is commonly considered for paired observations when parametric assumptions are unsuitable, but it is not mathematically identical to testing a population mean difference. Epic Essay's statistical test selection guide emphasises that alternatives should be selected because they fit the design and data rather than because one assumption-test p-value was significant.
Statistical maturity therefore involves asking what the alternative procedure tests, not simply whether it avoids the word "normality."
Common Normality Testing Mistakes Students Make
The most common mistake is treating Shapiro-Wilk as an automatic decision rule. A significant result identifies a detectable departure from normality but does not quantify whether the violation is severe enough to invalidate the planned analysis. Sample size and graphical evidence must be considered.
A second mistake is claiming that p > .05 proves normality. Failure to reject a normality null hypothesis is not the same as demonstrating that the population is exactly normal. Small samples can simply lack enough information to detect important departures.
Another frequent error is testing the wrong quantity. Students may test each raw variable before regression even though the relevant distributional diagnostic concerns residuals, or test pre-test and post-test scores separately when a paired t-test concerns the difference scores.
Finally, students sometimes use rigid skewness and kurtosis cutoffs without acknowledging context. Values such as ±1, ±2, or z statistics based on ±1.96 can be useful diagnostic conventions, but no single cutoff replaces graphical inspection, sample-size considerations, or model-specific reasoning.
Normality should never be declared "met" or "violated" from one number without considering what is being tested and why normality matters for the planned analysis.
How to Report Normality Testing in a Dissertation
A dissertation does not usually need a long paragraph listing every number generated by SPSS. The goal is to explain what was assessed, which evidence was considered, and whether the assumption was sufficiently supported for the intended analysis. Where a meaningful departure occurred, explain the response.
For example, a straightforward report could state: "Normality was assessed using Shapiro-Wilk tests and inspection of normal Q-Q plots. The test was non-significant for the outcome within both groups (p > .05), and the Q-Q plots showed no substantial systematic departures from the reference line."
For a larger sample with a significant formal test, a more nuanced report might state: "Shapiro-Wilk indicated a statistically significant departure from normality (p < .001); however, inspection of the Q-Q plot showed only minor tail deviations, while skewness and kurtosis were modest. The planned analysis was retained after consideration of sample size and the robustness of the procedure."
If reporting in an APA-style results section, Epic Essay's guide to writing an APA results section places assumption checking before the main inferential results, allowing readers to see how the validity of the statistical procedure was evaluated.
A Practical Normality Assessment Checklist
Normality assessment becomes clearer when students use a consistent sequence rather than searching immediately for the Shapiro-Wilk significance column. The following checklist keeps the diagnostic process tied to the statistical analysis.
- Identify the statistical procedure you intend to use.
- Determine exactly what quantity is subject to a normality assumption.
- Check the data for entry errors and impossible values.
- Inspect descriptive statistics and potential outliers.
- Run Shapiro-Wilk where appropriate.
- Inspect the normal Q-Q plot rather than relying only on the p-value.
- Examine skewness and its direction.
- Examine kurtosis using the convention reported by your software.
- Consider sample size when interpreting significance tests.
- Investigate isolated extreme observations.
- Determine whether the observed departure is substantively severe.
- Consider how robust the intended statistical procedure is to that departure.
- Use transformations only when they are methodologically meaningful.
- Choose non-parametric or robust alternatives only when they answer the research question appropriately.
- Report both the diagnostic evidence and the final analytical decision transparently.
This approach demonstrates stronger statistical reasoning than merely writing "Shapiro-Wilk p > .05, therefore normality was satisfied." Examiners are interested in whether students understand what the assumption means and how it affects the credibility of the analysis.
Interpreting Shapiro-Wilk, Q-Q Plots, Skewness, and Kurtosis Together
Normality tests are most informative when they are interpreted as complementary evidence. Shapiro-Wilk can identify statistically detectable departures, Q-Q plots reveal the form and severity of those departures, skewness describes asymmetry, and kurtosis provides information about tail behaviour and extreme observations. No single diagnostic answers every relevant question.
Sample size is especially important. A large sample can make a trivial departure statistically significant, while a small sample can fail to detect substantial non-normality. The researcher therefore needs to interpret formal tests alongside visual evidence, descriptive statistics, outliers, and the robustness of the intended analysis.
For dissertation research, the objective is not to prove that data are perfectly normal. It is to determine whether the distributional assumptions required by the chosen statistical procedure are sufficiently reasonable for credible inference. When Shapiro-Wilk, Q-Q plots, skewness, kurtosis, sample size, and model-specific requirements are evaluated together, normality testing becomes a defensible analytical judgement rather than a mechanical SPSS checkbox.
Comments