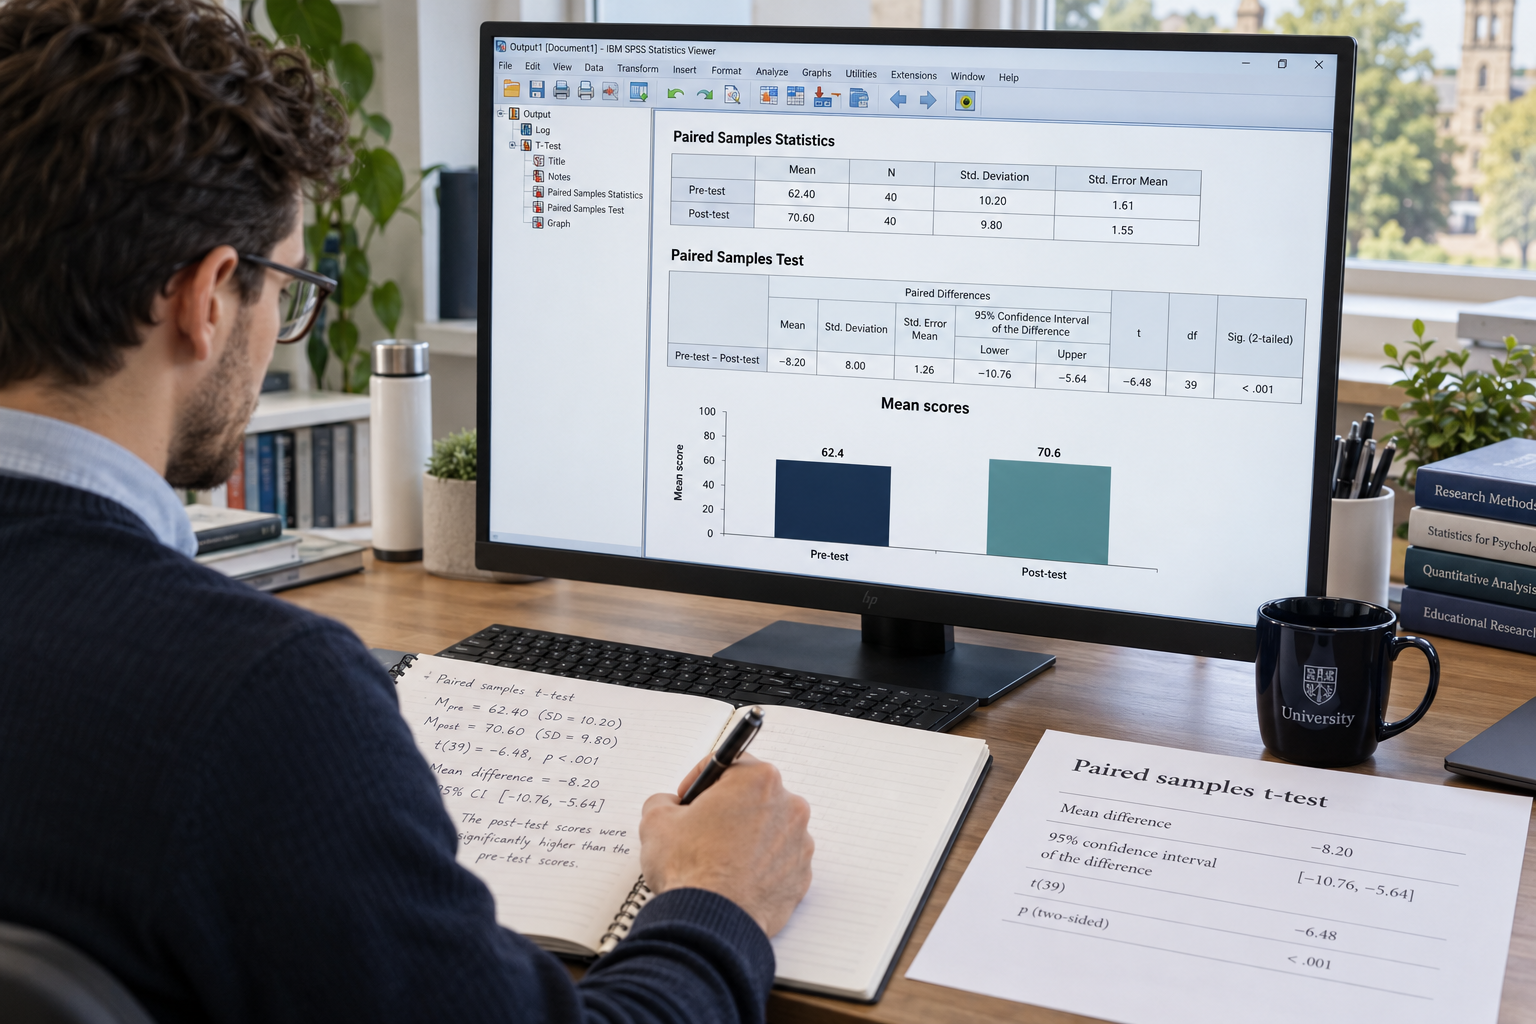
Comparing two means is one of the most common tasks in quantitative research, but choosing the correct statistical test depends on how the observations were generated. When the same participants are measured twice, or when observations have been deliberately matched into pairs, the two sets of scores are related rather than independent. Analysing them as though they came from unrelated groups ignores this structure and can produce an inappropriate statistical test.
A paired samples t-test in SPSS is designed specifically for two related measurements of a continuous outcome. Typical examples include students' scores before and after an intervention, patients' blood pressure before and after treatment, employees' productivity under two conditions, or measurements collected from matched participants. The test evaluates whether the average difference between the paired observations is sufficiently different from zero to provide evidence of a population-level change or difference.
Students often know how to click through SPSS but struggle with the more important questions: whether the paired t-test is appropriate, which assumptions apply, how to interpret the sign of the mean difference, what the confidence interval means, and how much information belongs in the final write-up. This guide addresses the complete analytical process from research design to dissertation reporting rather than treating SPSS output as a collection of numbers to copy into a results chapter.
What Is a Paired Samples t-Test?
A paired samples t-test, also called a dependent t-test or related-samples t-test, compares the means of two measurements that are meaningfully linked. Instead of comparing the two raw means independently, the test calculates a difference score for every pair and examines whether the mean of those differences differs significantly from zero. The statistical unit being analysed is therefore the within-pair difference.
For example, imagine that 40 students complete an academic-skills test before a training programme and then complete the same type of assessment afterwards. Each student's post-test score belongs specifically with that student's pre-test score. The paired t-test preserves this relationship by asking whether the average change across the 40 students is greater than would reasonably be expected from sampling variation alone.
This logic is consistent with IBM's SPSS documentation for the Paired-Samples T Test, which describes the procedure for two quantitative variables measured as a pair and reports the average difference, its standard error, confidence interval, t statistic, and related information. The test is therefore fundamentally about differences within pairs rather than two unrelated group means.
A paired samples t-test tests whether the mean of the paired difference scores is equal to zero. It does not simply ask whether two descriptive means look different.
When Should You Use a Paired Samples t-Test?
The test is appropriate when the research question concerns two related measurements of the same continuous variable. The most obvious design is a before-and-after study in which every participant contributes two observations. It can also be used when the same participants experience two different conditions or when separate individuals have been deliberately matched according to characteristics relevant to the study.
The relationship between the observations is what distinguishes the paired t-test from an independent samples t-test. If one group of students receives an intervention and an entirely different group serves as the control, the observations are independent rather than paired. By contrast, if the same students are assessed before and after the intervention, their scores form related pairs.
Epic Essay's guide to choosing statistical tests emphasises that analytical methods must match the structure of the variables and research design. Choosing between paired and independent tests is therefore a methodological decision made before opening SPSS, not merely a software option.
| Research Situation | Paired t-Test? | Reason |
|---|---|---|
| Students tested before and after a teaching intervention | Yes | The same students provide both measurements |
| Patients' blood pressure measured before and after treatment | Yes | Each patient's measurements form a pair |
| Employees perform a task under Condition A and Condition B | Yes | The same employees experience both conditions |
| Matched case-control participants | Potentially | Each case is deliberately paired with a matched control |
| Treatment group compared with a different control group | No | The observations belong to independent groups |
| Measurements taken at three or more time points | Usually no | A repeated-measures or longitudinal method is normally more appropriate |
| Two related ordinal measurements | Usually no | A non-parametric related-samples procedure may be more suitable |
The final two rows are particularly important. Running multiple paired t-tests across three or more time points increases the number of hypothesis tests and can inflate the probability of false-positive findings. A repeated-measures ANOVA, mixed model, or another design-appropriate method may provide a better analysis.
What Hypotheses Does the Paired t-Test Examine?
For a two-sided paired t-test, the null hypothesis states that the population mean difference between the paired measurements is zero. The alternative hypothesis states that the population mean difference is not zero. If the study is comparing pre-test and post-test measurements, this means testing whether the average change differs from no change.
Suppose the difference is defined as Pre minus Post. A negative mean difference then indicates that post-test scores were higher on average. If the variables are entered into SPSS in the opposite order, the numerical difference becomes positive, but the substantive conclusion about whether the measurements differ does not change.
This is why students should inspect how the pair is ordered before interpreting the sign of the SPSS mean difference. A negative value does not automatically mean that performance deteriorated; its meaning depends entirely on which variable was subtracted from which.
Never interpret the sign of a paired mean difference without first checking the order in which the two variables were entered into the SPSS pair.
What Are the Assumptions of a Paired Samples t-Test?
A valid paired t-test depends on both the research design and the statistical characteristics of the difference scores. The dependent variable should be quantitative and measured at an interval or ratio level. The two measurements must also be genuinely related, such as repeated observations from the same participant or appropriately matched observations.
A critical assumption concerns normality. The paired t-test does not require each of the two raw variables to be perfectly normally distributed. Instead, the distribution of the difference scores between the paired measurements should be approximately normal. This distinction is frequently misunderstood by students who run separate normality tests on Pre and Post and assume that those tests alone establish the assumption.
Extreme outliers in the difference scores also deserve attention because the mean and t statistic can be strongly influenced by unusual observations. In addition, one participant's pair should be independent of another participant's pair. Repeated measurements within one participant are intentionally dependent, but the different participants should not improperly influence one another.
| Assumption | What It Means | How to Evaluate It |
|---|---|---|
| Continuous outcome | The paired measurements are quantitative | Check the measurement scale and research instrument |
| Related observations | Each score in one condition has a meaningful partner in the other | Confirm the study design and data structure |
| Independent pairs | One participant's pair does not improperly determine another participant's pair | Evaluate sampling and study design |
| No problematic extreme outliers | Difference scores are not dominated by extreme cases | Inspect a boxplot of the calculated differences |
| Approximate normality of differences | The paired difference scores are approximately normally distributed | Inspect histogram or Q-Q plot and, where appropriate, a normality test |
The importance of normality should also be considered alongside sample size, the degree of departure from normality, and the presence of extreme outliers rather than reduced mechanically to one p-value. Visual examination of the difference scores can reveal patterns that a single normality test may not adequately communicate.
How to Check the Difference Scores in SPSS
Checking assumptions is easier when the paired differences are created explicitly. Suppose the dataset contains variables named PreScore and PostScore. In SPSS, the researcher can select Transform, then Compute Variable, create a variable such as Difference, and define it as PostScore minus PreScore or the reverse, depending on the intended interpretation.
The difference variable can then be examined through descriptive statistics, a histogram, boxplot, and Q-Q plot. If a Shapiro-Wilk test is used, its result should be considered alongside these visual diagnostics. A statistically significant normality test does not automatically mean that a paired t-test must be abandoned, particularly in a larger sample with only mild departures from normality.
More serious concerns arise when the differences are strongly skewed, contain influential extreme outliers, or the outcome is fundamentally ordinal rather than continuous. In such situations, the Wilcoxon signed-rank test may be considered when its own assumptions and research question are appropriate. The alternative should be selected because it fits the data and inferential question, not simply because a normality p-value happened to fall below .05.
Students designing a quantitative dissertation can place this assumption checking within the wider analytical strategy described in Epic Essay's quantitative thesis research guide, where statistical analysis should be justified according to the variables, hypotheses, and research design.
How Should Paired Data Be Entered in SPSS?
For a conventional repeated-measures design, each row in SPSS should represent one participant and each measurement should occupy its own variable column. A student measured before and after an intervention therefore has both scores on the same row. This structure allows SPSS to calculate the within-participant difference correctly.
For example, Participant 001 might have a PreScore of 61 and a PostScore of 69 in the same case. Participant 002 then appears on the next row with their own two scores. Entering pre-test participants in one block of rows and post-test participants in another would destroy the pairing and make the standard paired-samples procedure inappropriate.
Missing observations also require attention. If a participant has a pre-test measurement but no corresponding post-test measurement, that case cannot contribute a complete pair to that particular paired t-test. Researchers should therefore inspect the number of valid pairs in the SPSS output rather than assuming that the test used every participant originally recruited.
Transparent reporting should distinguish the total recruited sample from the number of complete paired observations actually analysed whenever missingness reduces the analytical sample.
How to Run a Paired Samples t-Test in SPSS
Once the data structure and assumptions have been checked, the analysis itself is straightforward. In current SPSS versions, the paired-samples procedure is available through the Compare Means menu. IBM's official documentation identifies the route as Analyze, Compare Means, then Paired-Samples T Test.
The basic procedure is:
- Open the dataset and confirm that both related measurements are stored in separate columns.
- Select Analyze.
- Select Compare Means.
- Select Paired-Samples T Test.
- Select the first and second variables that form the pair.
- Move them into the Paired Variables area in the intended order.
- Review the available options and confidence interval settings where required.
- Run the analysis.
- Inspect the descriptive statistics before interpreting significance.
- Interpret the paired difference, confidence interval, t statistic, degrees of freedom, and p-value.
The procedure should not be treated as complete merely because SPSS produces output. Statistical software performs the calculation requested by the researcher, but it does not determine whether the design justified that calculation. The methodological responsibility remains with the student.
How to Read the Paired Samples Statistics Table
The Paired Samples Statistics table provides descriptive information for the two measurements, typically including their means, sample sizes, standard deviations, and standard errors. This table should be examined before the hypothesis-test table because it shows the direction and approximate magnitude of the observed change.
Imagine a hypothetical study of 40 students. Their mean pre-intervention score is 62.40 with a standard deviation of 8.10, while the mean post-intervention score is 68.90 with a standard deviation of 7.60. Descriptively, scores improved by 6.50 points. The inferential test is needed to determine how strongly the sample supports a non-zero population mean difference.
The means and standard deviations are useful reporting statistics, but they are not themselves evidence of statistical significance. A visually large mean difference can be statistically uncertain when variability is high or the sample is small, while a modest difference can be estimated precisely in a large or highly consistent sample.
Researchers should therefore report both descriptive and inferential evidence rather than stating only that one mean was higher than another.
What Does the Paired Samples Correlations Table Mean?
SPSS may report the correlation between the two paired measurements. This describes how strongly participants' scores at one measurement tend to be associated with their scores at the other. For example, students who performed relatively well before an intervention may also tend to perform relatively well afterwards.
This correlation does not test whether the mean changed. Two variables can be strongly correlated while having very different means, and they can have similar means while being weakly correlated. The paired t-test and the paired correlation therefore answer different statistical questions.
Students occasionally report the correlation coefficient as though it were evidence that the intervention caused change. That interpretation is incorrect. The hypothesis about mean change should be evaluated from the Paired Samples Test output, while the correlation can be reported separately only if it is substantively useful.
Keeping these functions distinct prevents a common SPSS interpretation error: mistaking every table generated by the software for part of the same hypothesis test.
How to Interpret the Paired Samples Test Table
The Paired Samples Test table contains the main inferential result. It reports the mean difference, standard deviation and standard error of the differences, confidence interval for the mean difference, t statistic, degrees of freedom, and significance level. Recent versions of SPSS can also provide effect-size information within the paired-samples procedure or associated output.
Using the hypothetical student example, suppose the pair is entered as PreScore minus PostScore. The mean difference is therefore -6.50, the standard deviation of the differences is 6.20, and the standard error is approximately 0.98. With 40 complete pairs, the degrees of freedom are 39 and the resulting statistic is approximately t = -6.63.
The corresponding two-sided p-value is below .001, providing strong evidence against a population mean difference of zero under the assumptions of the test. The 95% confidence interval for the Pre minus Post difference is approximately -8.48 to -4.52. Because zero is not contained within the interval, the confidence interval and two-sided significance test lead to the same inferential conclusion at the .05 level.
| Statistic | Result | Interpretation |
|---|---|---|
| Pre-test | M = 62.40, SD = 8.10 | Average score before the intervention |
| Post-test | M = 68.90, SD = 7.60 | Average score after the intervention |
| Mean difference: Pre - Post | -6.50 | Post-test scores were 6.50 points higher on average |
| 95% CI for difference | [-8.48, -4.52] | Plausible range for the population mean Pre - Post difference |
| t statistic | -6.63 | Difference expressed relative to its standard error |
| Degrees of freedom | 39 | Based on 40 complete pairs |
| p-value | < .001 | Evidence against a zero mean difference |
The table should not be interpreted as proving that the intervention caused the increase. Causal conclusions depend on the overall research design, including control conditions, randomisation, potential confounding variables, measurement validity, and other threats to inference. Statistical significance answers a narrower question than causality.
What Does the Confidence Interval Tell You?
The confidence interval provides more information than a binary significant or non-significant label. It gives a range of values compatible with the estimated population mean difference under the statistical model. In the hypothetical example, the estimated Pre minus Post difference lies between approximately -8.48 and -4.52 points at the 95% confidence level.
Expressed in the more intuitive Post minus Pre direction, the improvement would correspond to approximately 4.52 to 8.48 points. This gives readers information about the likely magnitude and precision of the effect rather than only whether p crossed the .05 threshold.
A narrow interval indicates greater precision than a very wide interval. Consequently, researchers should discuss whether the plausible values are substantively important in the context of the study. Statistical significance does not automatically establish educational, clinical, organisational, or practical importance.
Confidence intervals are therefore central to interpretation rather than optional decoration. They help move the results section beyond mechanical p-value reporting.
Should You Report an Effect Size for a Paired t-Test?
An effect size helps communicate the magnitude of the paired difference in standardised terms. This complements the p-value, which is influenced by both effect magnitude and sample size. A statistically significant finding can still represent a small practical change, while a meaningful effect may fail to reach conventional significance in an underpowered study.
One common standardised measure for paired data is Cohen's dz, calculated by dividing the mean difference by the standard deviation of the difference scores. In the hypothetical example, 6.50 divided by 6.20 gives an absolute dz of approximately 1.05. The sign simply reflects the chosen subtraction direction, while the magnitude represents the standardised within-pair difference.
Researchers should state which version of a paired effect size they have calculated because several standardisation approaches exist for repeated-measures designs. Reporting only "Cohen's d" without explaining the denominator can create ambiguity. Where SPSS supplies an effect-size table, the student should understand exactly which estimate has been produced before reproducing it in an assignment.
Effect sizes should also be interpreted within the discipline rather than treated mechanically through universal labels. Context, measurement scale, prior studies, and practical consequences all influence whether an observed effect is meaningful.
How to Report a Paired Samples t-Test in a Dissertation
A strong statistical write-up combines the research comparison, descriptive statistics, inferential test, confidence interval, and effect size where appropriate. It should give the reader enough information to understand both the direction and magnitude of the finding without copying an entire SPSS output table into the dissertation.
Using the hypothetical results above, a concise write-up could state that post-intervention scores were higher than pre-intervention scores and then provide the relevant numerical evidence. Because the Pre minus Post difference was used by SPSS, the negative t statistic is mathematically correct even though the substantive change was an improvement.
Participants scored higher after the intervention (M = 68.90, SD = 7.60) than before it (M = 62.40, SD = 8.10). A paired samples t-test indicated a statistically significant mean increase of 6.50 points, t(39) = -6.63, p < .001, with the 95% confidence interval for the Pre minus Post difference ranging from -8.48 to -4.52. The standardised within-participant difference was large in this hypothetical example (|dz| = 1.05).
The wording must remain consistent with the way the difference was calculated. Alternatively, the researcher can present the change as Post minus Pre, producing a positive mean difference and t statistic. Either approach is acceptable when the direction is explained clearly and the reported numbers remain internally consistent.
Epic Essay's guide to dissertation findings and discussion emphasises the distinction between presenting statistical outcomes and interpreting their academic meaning. The results section should report the paired t-test accurately, while the discussion should explain what the observed difference means in relation to the research question and previous literature.
Should You Write p = .000 in the Results?
SPSS output may display a probability as .000 because the interface rounds very small values to three decimal places. This does not mean that the probability is literally zero. Statistical software has simply calculated a value smaller than the displayed rounding threshold.
When SPSS shows .000, academic reporting should normally state p < .001 rather than p = .000. This accurately communicates that the probability is extremely small without making the impossible claim that the observed test statistic has exactly zero probability under the null model.
The same principle applies to copied SPSS tables. Students should not assume that the software's display format is automatically the correct prose format for a dissertation. Statistical output needs to be translated into recognised academic reporting conventions.
Never report SPSS output of .000 as p = .000. Report it as p < .001.
What If the Paired t-Test Is Not Statistically Significant?
A non-significant result does not demonstrate that the two measurements are identical. It indicates that the study did not obtain sufficiently strong evidence against the null hypothesis at the chosen significance level. The confidence interval is especially useful because it shows the range of population differences compatible with the data.
Researchers should avoid phrases such as "there was no effect" solely because p exceeded .05. A wide confidence interval may still contain differences that would be practically important, particularly when the sample is small. Low statistical power can make genuine differences difficult to detect.
A more accurate write-up states that the paired t-test did not identify a statistically significant mean difference and then reports the descriptive statistics, t statistic, degrees of freedom, p-value, and confidence interval. The discussion can then consider sample size, precision, measurement limitations, or theoretical explanations without claiming that the null hypothesis has been proven.
This distinction is essential for critical quantitative writing because absence of statistically significant evidence is not automatically evidence of complete absence.
Paired Samples t-Test vs Independent Samples t-Test
The paired and independent samples t-tests both compare two means, but their error structures differ because they answer questions about different research designs. A paired test uses the correlation between linked observations by analysing within-pair differences. An independent test assumes that observations belong to unrelated groups.
For example, comparing anxiety before and after therapy among the same 30 participants requires a paired test. Comparing anxiety among 30 therapy participants and a separate group of 30 control participants requires an independent samples test. The number of groups is two in both examples, but the relationship between observations is fundamentally different.
Using an independent t-test for genuinely paired data discards information about the pairing. Using a paired t-test for unrelated groups creates artificial relationships that do not exist. Correct test selection therefore depends on the design rather than the appearance of two columns of numbers.
Students should identify the sampling and measurement structure before deciding which SPSS command to use. Software cannot repair a mismatch between the statistical procedure and the study design.
Paired Samples t-Test vs Wilcoxon Signed-Rank Test
The Wilcoxon signed-rank test is frequently presented as a non-parametric alternative to the paired t-test. It can be useful when two related measurements are being compared and the assumptions required for the parametric mean-difference test are not defensible. It is also commonly considered for appropriate ordinal data.
However, the two tests should not be described as mathematically identical versions of the same hypothesis. The paired t-test directly concerns the population mean of the differences. The Wilcoxon signed-rank procedure operates through ranks and has different distributional assumptions and interpretation.
A statistically significant Shapiro-Wilk result alone should not trigger an automatic switch. Researchers should inspect the difference distribution, sample size, extreme observations, outcome scale, research question, and methodological expectations before choosing an alternative.
Correct statistical reasoning requires explaining why the selected test answers the research question more appropriately than its alternatives.
Common Paired t-Test Mistakes in SPSS
One common mistake is using a paired t-test for two independent groups simply because there are two columns in SPSS. Pairing is a property of the research design, not the spreadsheet layout. Every observation in the first measurement must have a defensible relationship with one observation in the second.
A second mistake is checking normality separately for the two measurement variables but ignoring the difference scores. The central normality assumption concerns the paired differences. Researchers should calculate or inspect those differences explicitly when evaluating the assumption.
Students also frequently report only the p-value. This removes the descriptive context, direction of the change, uncertainty, and effect magnitude. A stronger report includes the two means and standard deviations, mean difference or direction of change, t statistic, degrees of freedom, p-value, confidence interval, and an effect size where appropriate.
Finally, statistical significance should not be transformed into a causal claim that the intervention "proved" it caused the observed difference. Causality depends on the research design as a whole. A paired t-test alone cannot eliminate competing explanations for change over time.
A Paired Samples t-Test Checklist for SPSS
Before submitting a quantitative assignment or dissertation, students should audit the complete analytical chain rather than checking only the final p-value. The research question, data structure, assumptions, SPSS setup, numerical interpretation, and written reporting should all tell the same methodological story.
- Confirm that the research question compares exactly two related measurements.
- Check that the outcome is suitable for a paired parametric analysis.
- Confirm that each first measurement is correctly paired with its corresponding second measurement.
- Inspect the number of complete pairs available for analysis.
- Create and examine the paired difference scores.
- Check the difference scores for extreme outliers.
- Assess approximate normality of the differences using appropriate graphical and statistical evidence.
- Run Analyze > Compare Means > Paired-Samples T Test in SPSS.
- Inspect the descriptive statistics before interpreting significance.
- Check the variable order before interpreting the sign of the mean difference and t statistic.
- Report the t statistic, degrees of freedom, p-value, and confidence interval.
- Report an appropriate effect size where required.
- Write p < .001 rather than p = .000 when SPSS displays .000.
- Keep statistical significance separate from practical importance and causal interpretation.
- Connect the result back to the research question in the discussion chapter.
This checklist turns the paired t-test from a software procedure into a defensible statistical analysis. Examiners are interested not only in whether SPSS was operated correctly but whether the researcher understands why the analysis is appropriate and what the output can legitimately support.
Using the Paired Samples t-Test in SPSS with Confidence
A paired samples t-test in SPSS is appropriate when a study compares two meaningfully related measurements of a continuous outcome. Its logic is based on the differences within pairs, which means that research design, correct pairing, outlier assessment, and approximate normality of the difference scores all matter before the final significance test is interpreted.
The SPSS output should be read as an integrated set of evidence. Descriptive means establish the observed direction of change, the mean difference quantifies that change, the t statistic and p-value assess evidence against a zero population mean difference, the confidence interval communicates precision, and an appropriate effect size helps describe magnitude. No single number should carry the entire interpretation.
For dissertation reporting, present the result concisely and accurately rather than reproducing raw SPSS output. Explain what was compared, report the necessary descriptive and inferential statistics, keep the subtraction direction clear, and discuss practical meaning separately from statistical significance. When test selection, assumptions, analysis, and reporting are aligned, the paired samples t-test becomes a transparent and academically defensible way to evaluate change or differences within related observations.
Comments