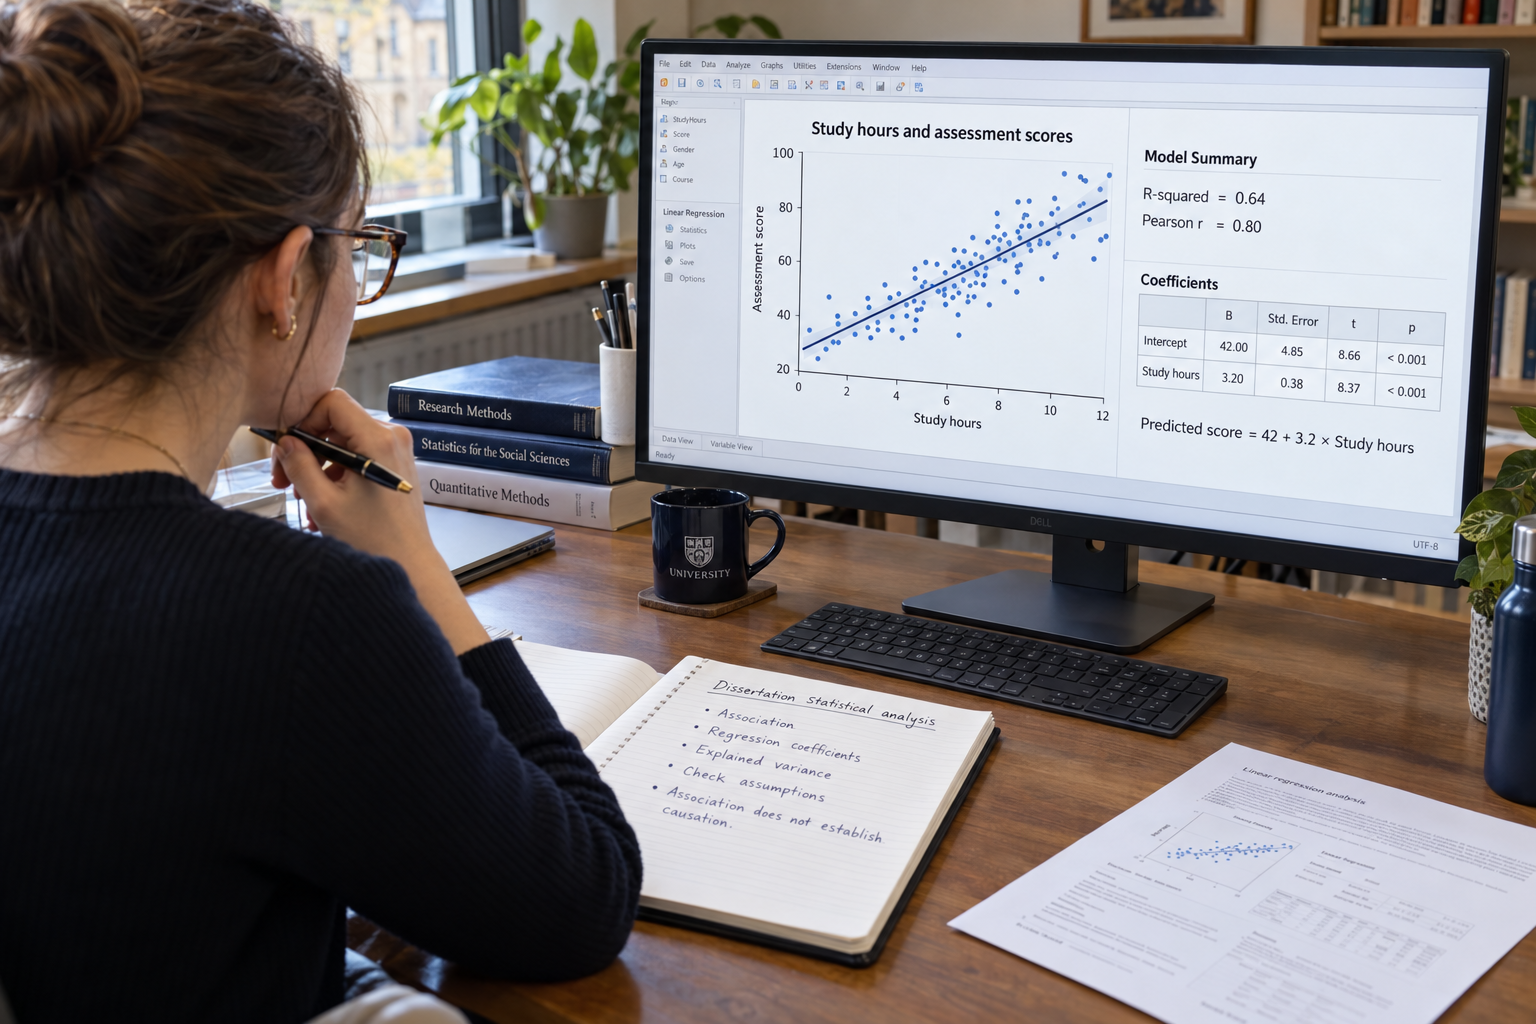
Quantitative dissertations frequently investigate relationships between variables. A business student may examine whether employee engagement is associated with productivity, an education researcher may study the relationship between study hours and assessment scores, and a health researcher may analyse whether physical activity is related to blood pressure. Correlation and regression are two of the most common statistical methods used for these questions, which is why students often assume they are interchangeable.
The distinction matters because correlation vs regression involves different analytical purposes. Correlation describes the strength and direction of an association between two variables, whereas regression models an outcome variable as a function of one or more predictor variables. Regression can therefore estimate how much the outcome is expected to change when a predictor changes, assess model fit, incorporate multiple predictors, and generate predicted values.
Choosing between the two should begin with the research question rather than the software menu. A dissertation asking whether two variables are associated may require correlation, while a dissertation asking whether one or more variables predict variation in an outcome may require regression. This guide explains those differences, shows how the methods are related mathematically, and demonstrates how students can interpret and report each analysis without overstating what the statistics prove.
What Does Correlation Measure?
Correlation measures the degree to which two variables vary together. Pearson's correlation coefficient, usually represented by r, describes the direction and strength of a linear relationship between two quantitative variables. Its value ranges from -1 to +1: positive values indicate that higher values of one variable tend to occur with higher values of the other, while negative values indicate that higher values of one variable tend to occur with lower values of the other.
A correlation close to zero indicates little linear association, but this does not automatically mean that no relationship exists. Variables can have a strong curved or otherwise non-linear relationship while producing a Pearson correlation near zero. A scatterplot should therefore be inspected alongside the coefficient so that unusual patterns, clusters, and influential observations are not hidden behind a single numerical summary.
The Penn State STAT 500 guidance on correlation and regression emphasises several important properties of Pearson's r: it is unit-free, its sign shows the direction of the linear relationship, and its magnitude reflects linear association. Correlation is also symmetrical, meaning that the correlation between X and Y is identical to the correlation between Y and X.
What Does Regression Analysis Measure?
Linear regression examines how a dependent or outcome variable is statistically related to one or more predictor variables. In simple linear regression, one predictor is used to model one continuous outcome. The regression equation estimates an intercept and a slope, allowing the researcher to calculate the expected value of the outcome at specified values of the predictor.
The slope coefficient has a direct quantitative interpretation. If a dissertation estimates that each additional hour of weekly study is associated with a 1.35-point increase in assessment score, the unstandardised regression coefficient B is 1.35. Unlike a correlation coefficient, this estimate retains the measurement units of the variables, making it useful for describing the expected magnitude of change.
Regression can also be extended beyond one predictor. Multiple regression estimates the statistical association between each predictor and the outcome while the other predictors in the model are held constant statistically. Epic Essay's regression analysis interpretation guide explains how regression coefficients, R-squared, confidence intervals, model significance, and diagnostic checks contribute to a complete interpretation.
Correlation vs Regression: What Are the Main Differences?
The clearest distinction lies in the research purpose. Correlation asks how strongly two variables are associated and in which direction. Regression asks how an outcome changes in relation to one or more predictors and can be used to estimate expected outcome values. This makes regression more structured because the researcher explicitly defines which variable is the dependent outcome and which variable or variables are predictors.
Correlation does not make this directional distinction. Swapping the order of X and Y leaves Pearson's r unchanged. In regression, swapping the dependent and independent variables creates a different model because the model is now estimating a different outcome.
| Feature | Correlation | Regression |
|---|---|---|
| Main purpose | Measure the strength and direction of association | Model an outcome using one or more predictors |
| Typical statistic | Pearson's r or another correlation coefficient | B, beta, R-squared, F statistic, confidence intervals |
| Variable roles | Variables are treated symmetrically | Dependent and predictor variables have distinct roles |
| Units | Correlation coefficient is unit-free | Unstandardised coefficients retain measurement units |
| Range | r ranges from -1 to +1 | Regression coefficients are not restricted to -1 to +1 |
| Prediction | Does not directly produce an outcome prediction equation | Can generate predicted values of the dependent variable |
| Multiple predictors | A simple pairwise correlation considers two variables at a time | Multiple regression can include several predictors simultaneously |
| Causation | Does not establish causation | Does not establish causation by itself |
The table shows that regression is not simply a "stronger correlation." It answers a more structured modelling question and provides additional parameters. The correct method therefore depends on what the dissertation is trying to estimate rather than which technique appears more statistically advanced.
How Are Correlation and Simple Linear Regression Related?
Correlation and simple linear regression are mathematically connected when both involve the same two quantitative variables. The sign of Pearson's r is the same as the sign of the simple regression slope. A positive correlation therefore corresponds with a positive regression slope, while a negative correlation corresponds with a negative slope.
In a simple linear regression containing only one predictor, R-squared is equal to the square of Pearson's correlation coefficient when the same observations and ordinary least-squares model are used. For example, a correlation of r = .50 corresponds to R-squared = .25. This means the simple linear model accounts for 25% of the observed variance in the outcome, although the meaning of "explained" should remain statistical rather than automatically causal.
Penn State's regression foundations material also notes that the hypothesis test for Pearson correlation and the hypothesis test for the slope in simple linear regression are closely related. With one predictor, testing whether the population correlation equals zero leads to the same inferential conclusion as testing whether the population regression slope equals zero under the corresponding assumptions.
When Should You Use Correlation Rather Than Regression?
Correlation is appropriate when the research question is primarily about association and neither variable needs to be treated as an outcome predicted from the other. A dissertation might ask whether academic self-efficacy is associated with student engagement, whether stress is related to sleep duration, or whether organisational commitment is associated with job satisfaction. In each case, the researcher may be interested mainly in direction and strength rather than producing a predictive equation.
Correlation can also provide an important preliminary analysis before a regression model is constructed. Examining a correlation matrix can reveal patterns among variables and help identify very strong relationships among potential predictors. However, a correlation matrix does not replace regression because pairwise associations do not show how each predictor behaves after other predictors are included in a model.
| Research Question | Likely Method | Reason |
|---|---|---|
| Is study time associated with assessment score? | Correlation | The question focuses on the strength and direction of association |
| How much does assessment score change for each additional study hour? | Regression | The question requires a slope coefficient |
| Can study hours predict assessment score? | Regression | The analysis models an outcome from a predictor |
| Are stress and sleep duration related? | Correlation | No directional modelling question is specified |
| Do stress, workload, and sleep independently relate to burnout score? | Multiple regression | Several predictors are evaluated simultaneously |
| Which of several predictors contributes uniquely to variation in an outcome? | Multiple regression | Conditional coefficients are required |
Epic Essay's guide to choosing statistical tests reinforces this research-question-first approach. Statistical tests should be selected according to data type, study design, assumptions, and analytical objective rather than according to whichever procedure is most familiar.
What Assumptions Do Correlation and Regression Require?
Pearson correlation and ordinary least-squares linear regression both depend on the relationship being appropriately represented as linear. A scatterplot should therefore be examined before interpreting either method. Outliers are also important because a small number of extreme observations can substantially change both the correlation coefficient and regression slope.
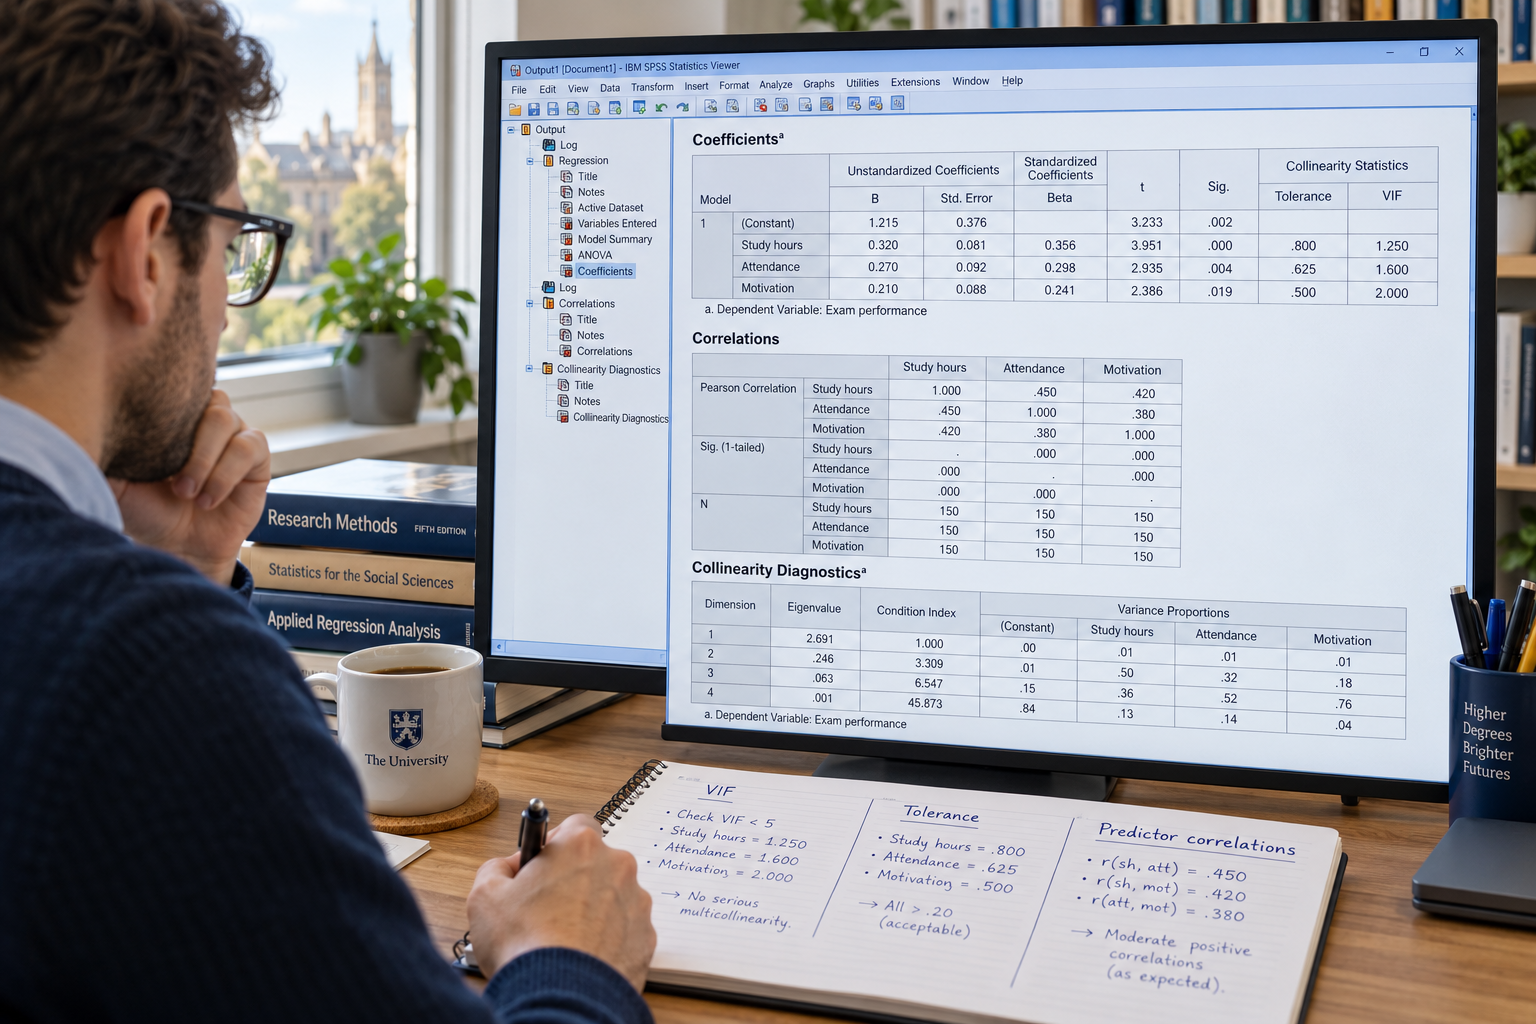
Regression requires additional attention to residuals because inferential conclusions depend on characteristics of the model errors. Important considerations include independence, linearity, approximately constant residual variance, and appropriate residual behaviour for the intended inference. Multiple regression additionally requires examination of problematic multicollinearity and influential observations.
| Issue | Correlation | Regression |
|---|---|---|
| Linearity | Important for Pearson correlation | Important for linear regression specification |
| Outliers | Can strongly distort r | Can alter slopes, model fit, and predictions |
| Independence | Observations should be appropriately independent | Errors should satisfy the independence assumptions of the model |
| Homoscedasticity | Relevant to classical Pearson inference | Residual variance should be appropriately constant for classical OLS inference |
| Residual normality | Not assessed in exactly the same way as regression | Relevant to conventional tests and confidence intervals in smaller samples |
| Multicollinearity | Not a feature of a simple two-variable correlation itself | Important when several predictors are included |
The UCLA SPSS regression diagnostics guide discusses linearity, residual variance, residual normality, independence, multicollinearity, model specification, and influential cases. These diagnostics are essential because a statistically significant regression coefficient can still be misleading when the chosen model fits the data poorly.
Do not select correlation or regression solely because both variables are numerical. The research question, functional form, design, assumptions, and quality of the data must support the chosen analysis.
Dissertation Example: Interpreting a Correlation
Consider a hypothetical education dissertation investigating whether weekly independent study hours are associated with final assessment scores among 120 university students. A scatterplot indicates an approximately linear positive pattern without obviously dominant outliers. Pearson correlation is therefore used to quantify the relationship.
Suppose the analysis produces r = .52 with p < .001. The result indicates a positive linear association: students reporting more weekly study hours tended to achieve higher assessment scores. The magnitude of .52 should be interpreted within the discipline and research context rather than labelled automatically according to a universal "weak, moderate, strong" table.
A concise results statement could read: "Weekly study hours were positively correlated with assessment scores, r(118) = .52, p < .001." The discussion could then consider possible explanations for the association, compare it with previous evidence, and acknowledge that the observational correlation alone does not establish that additional study time caused higher scores.
Dissertation Example: Interpreting Simple Linear Regression
Now suppose the dissertation changes its analytical question from "Are study hours and scores associated?" to "How much does assessment score change in relation to weekly study hours?" Simple linear regression becomes more informative because it produces an estimated slope and prediction equation.
Imagine the regression equation is predicted assessment score = 55.20 + 1.35 × weekly study hours. The unstandardised coefficient B = 1.35 means that each additional weekly study hour is associated with an estimated 1.35-point increase in assessment score on average. If the slope has SE = 0.20, p < .001, and a 95% confidence interval of approximately 0.95 to 1.75, the interval communicates both the direction and uncertainty of the estimated relationship.
Suppose R-squared = .27. The model then accounts statistically for approximately 27% of the observed variance in assessment scores in this sample. This does not mean that study hours "cause 27% of performance" or that the remaining 73% is explained by one particular factor. R-squared describes model fit within the analysed data, not a causal partition of all influences on academic achievement.
| Statistic | Hypothetical Result | Interpretation |
|---|---|---|
| Pearson correlation | r = .52 | Positive linear association between study hours and assessment scores |
| Correlation significance | p < .001 | Evidence against a zero population linear correlation under the test assumptions |
| Regression slope | B = 1.35 | Estimated 1.35-point score increase per additional weekly study hour |
| Slope 95% CI | [0.95, 1.75] | Interval estimate for the population slope |
| R-squared | .27 | Approximately 27% of observed outcome variance is accounted for by the simple linear model |
These results illustrate how the same data can answer related but different questions. The correlation summarises association on a standardised, unit-free scale, whereas regression converts that relationship into an estimated change in the outcome's measurement units.
How Do You Report Correlation and Regression Differently?
A correlation write-up normally reports the type of coefficient, direction, value of r, degrees of freedom where required, p-value, and sometimes a confidence interval. The emphasis remains on the association itself. A regression write-up generally requires more information because it describes both the overall model and individual predictor coefficients.
For regression, students may need to report R-squared or adjusted R-squared, the model F statistic, degrees of freedom, p-value, unstandardised coefficients, standard errors, standardised coefficients where useful, and confidence intervals. Multiple regression also requires clear identification of which predictors remain associated with the outcome conditional on the other variables included in the model.
A hypothetical regression report could state: "Weekly study hours significantly predicted assessment score, B = 1.35, SE = 0.20, 95% CI [0.95, 1.75], p < .001. The model was statistically significant and accounted for 27% of the variance in assessment scores, R-squared = .27." The exact statistics required should follow the discipline, assessment instructions, and reporting standard being used.
When these results appear in a dissertation, the findings section should present them accurately before the discussion interprets their broader meaning. Epic Essay's guide to dissertation findings and discussion explains why reporting statistical output and interpreting its theoretical significance are related but distinct academic tasks.
What Does Multiple Regression Add Beyond Correlation?
Multiple regression becomes useful when a dissertation includes several predictors of the same outcome. Suppose assessment score is modelled using weekly study hours, attendance percentage, academic self-efficacy, and previous GPA. The model estimates a separate coefficient for each predictor while statistically accounting for the others included in that model.
This can produce conclusions that differ from pairwise correlations. Study hours may correlate strongly with assessment scores when examined alone but contribute less uniquely after previous GPA and attendance are included. This occurs because predictors can share overlapping information about the outcome. A correlation matrix cannot by itself show these conditional relationships.
However, describing a multiple-regression coefficient as an "independent effect" can be misleading if it suggests causal independence. The coefficient is conditional on the variables included in the statistical model. Omitted confounding, measurement error, inappropriate functional form, selection processes, and study design can still affect interpretation.
Why Neither Correlation nor Regression Automatically Proves Causation
Correlation is often accompanied by the warning that correlation does not imply causation, but the same caution applies to regression. Giving one variable the label "predictor" and another the label "dependent variable" does not demonstrate that changes in the predictor cause changes in the outcome. Regression can estimate associations under a specified model without establishing the causal mechanism behind them.
Consider the study-hours example. Students who study more may also differ in prior achievement, motivation, available time, socioeconomic resources, attendance, course difficulty, or other factors associated with academic performance. A positive regression coefficient for study hours may remain statistically significant even though the observational design cannot rule out all alternative explanations.
Stronger causal conclusions require a research design and assumptions capable of supporting them, potentially involving randomisation, temporal ordering, credible control strategies, natural experiments, causal inference methods, or other discipline-appropriate evidence. Statistical significance alone is not a substitute for causal identification.
Regression specifies a direction in the mathematical model. It does not, by itself, prove a direction of causation in the real world.
Common Correlation vs Regression Mistakes Students Make
One common mistake is choosing regression simply because it appears more sophisticated. A simple research question about whether two variables are associated may be answered clearly with correlation. Adding an unnecessary regression model can complicate the results without answering a more meaningful question.
A second mistake is interpreting correlation as prediction. A correlation of r = .60 shows a positive linear association, but it does not tell the reader how many units the outcome is expected to change for a one-unit increase in the other variable. That interpretation requires a regression slope.
Students also frequently interpret R-squared too aggressively. Saying that R-squared = .40 means "40% of Y is caused by X" is incorrect. R-squared describes the proportion of observed outcome variance accounted for statistically by the fitted model in the analysed data. Causal language requires additional justification beyond model fit.
A significant correlation or regression coefficient should never be rewritten automatically as "X causes Y." Match the language of the conclusion to the research design and evidence actually available.
How to Choose Between Correlation and Regression Step by Step
The best decision process begins with the analytical question rather than the output you hope to obtain. Researchers should define what they need to know about the variables, confirm the measurement level and design, inspect the data visually, and then select a procedure whose assumptions and interpretation fit that purpose.
Use the following sequence when planning a dissertation analysis:
- Write the research question in statistical terms.
- Identify the outcome, predictor, and other variables involved.
- Ask whether the goal is association, prediction, explanation, or another form of inference.
- Use correlation when the central question concerns the strength and direction of association between two suitable variables.
- Use simple regression when one variable is explicitly modelled as an outcome from one predictor.
- Consider multiple regression when several predictors need to be evaluated within the same outcome model.
- Inspect scatterplots and descriptive statistics before running inferential tests.
- Check the assumptions relevant to the chosen procedure.
- Investigate unusual or influential observations rather than deleting them automatically.
- Interpret coefficients, uncertainty, and model fit rather than relying only on p-values.
- Use causal terminology only when the research design supports causal inference.
- Report the result in a form that directly answers the dissertation research question.
The statistical method should also be justified explicitly in the methodology chapter. Epic Essay's dissertation methodology guide emphasises that data-analysis choices should be linked directly to the research questions and data rather than presented as unexplained software procedures.
Choosing Correlation or Regression for a Stronger Dissertation
The central difference between correlation and regression lies in what the researcher wants the data to answer. Correlation provides a standardised measure of the direction and strength of association between two variables without assigning them unequal statistical roles. Regression specifies an outcome and one or more predictors, estimates coefficients in meaningful units, assesses model fit, and can generate predicted values.
The two techniques are closely connected in simple linear settings, but they are not interchangeable. A correlation coefficient answers a different question from an unstandardised regression slope, and multiple regression extends analysis well beyond a pairwise association. Assumptions, residual diagnostics, uncertainty, influential observations, and research design all need to be considered before either method is interpreted.
For dissertation work, the most defensible approach is to begin with the research question, select the statistic that answers it directly, and report only conclusions the design can support. Explain associations as associations, interpret regression coefficients in context, report uncertainty alongside significance, and reserve causal claims for studies with an appropriate causal design. That combination of statistical accuracy and methodological restraint produces a stronger quantitative dissertation than simply choosing the most complex analysis available.
Comments