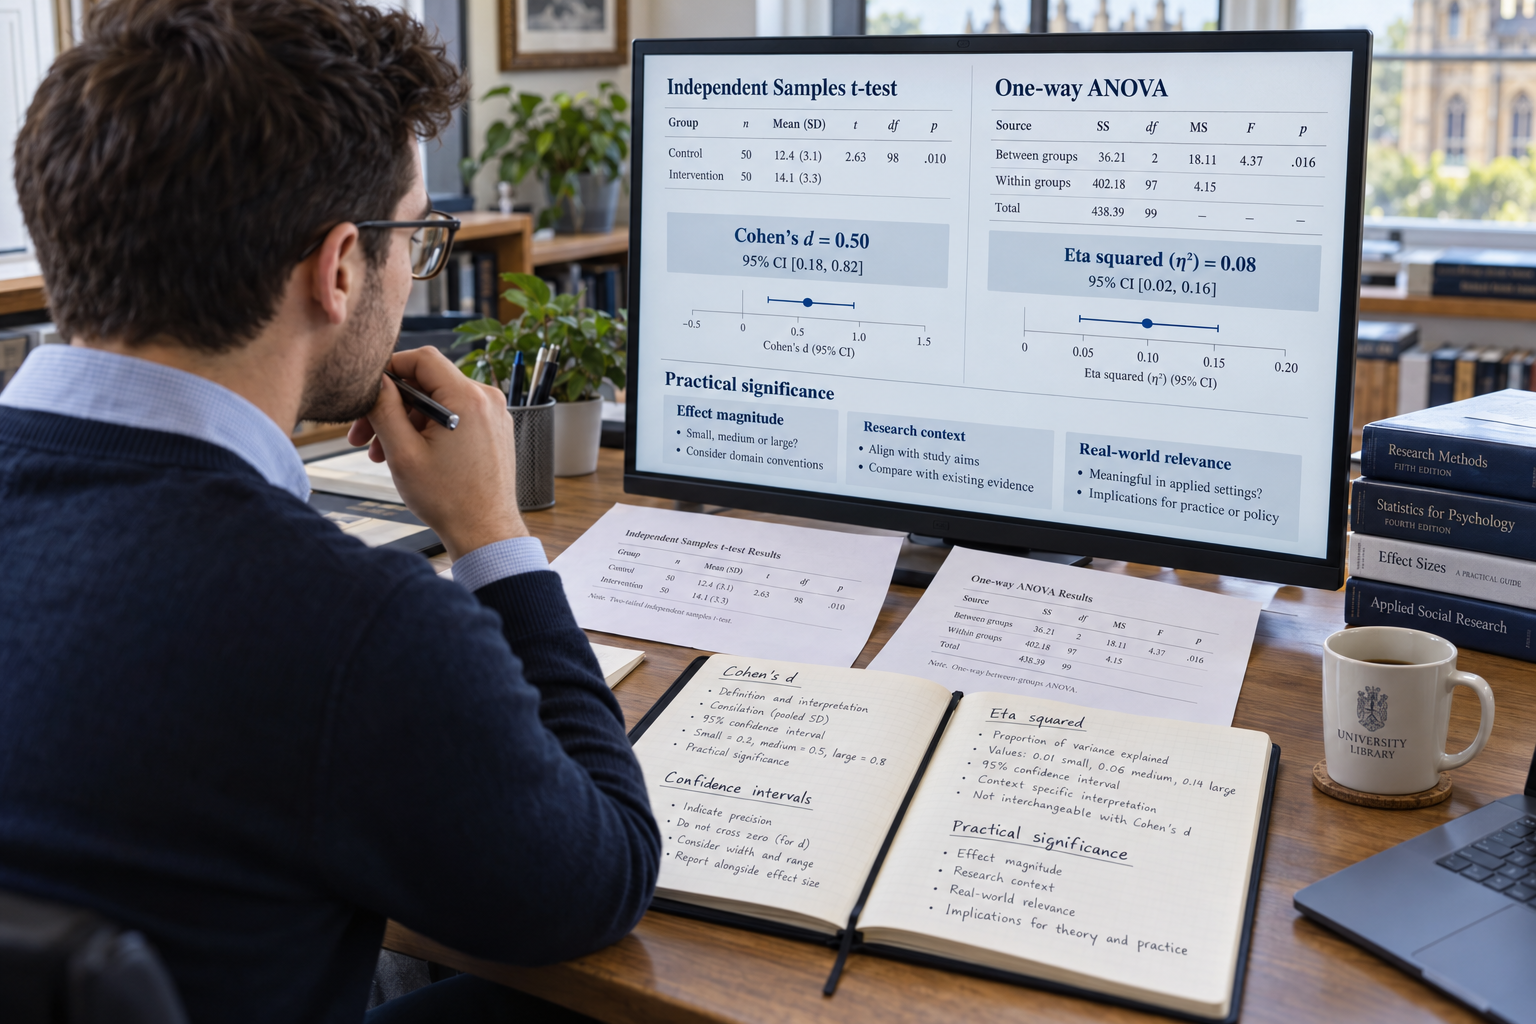
Statistical significance tells researchers whether the observed data provide evidence against a specified null hypothesis, but it does not tell them how large or important the observed effect is. A difference between two groups can produce a very small p-value while being practically trivial, especially in a large sample. Conversely, a potentially meaningful effect can fail to reach conventional statistical significance when a study is small or imprecise.
Effect size addresses this limitation by quantifying the magnitude of a result. Depending on the statistical test and research design, an effect size may describe a standardised difference between means, the proportion of variance associated with an experimental factor, the strength of an association, or another measure of substantive magnitude. Cohen’s d and eta squared are among the effect sizes students encounter most frequently when using t-tests and ANOVA.
Understanding effect size is therefore essential for interpreting dissertation results critically. Students need to know not only whether a result is statistically significant but whether the observed difference is small, substantial, precise, practically meaningful, and comparable with previous research. This guide explains Cohen’s d, eta squared, partial eta squared, effect-size benchmarks, practical significance, and the common mistakes that occur when effect sizes are interpreted mechanically.
What Is an Effect Size?
An effect size is a quantitative measure of the magnitude of a difference, relationship, or effect observed in research. Unlike a p-value, which is strongly influenced by sample size and sampling variability, an effect-size statistic is designed to communicate how large the observed phenomenon is on a defined scale. This makes effect sizes particularly valuable when comparing findings across studies or assessing whether statistically significant results are important enough to matter.
The appropriate effect-size measure depends on the research question and statistical procedure. Mean comparisons commonly use standardised mean differences such as Cohen’s d. ANOVA commonly uses variance-based measures such as eta squared or partial eta squared. Correlation coefficients, odds ratios, risk ratios, and R-squared are also forms of effect-size information in other analytical contexts.
Epic Essay's guide to choosing statistical tests explains that statistical methods should be matched to the research question, design, variables, and assumptions. Effect-size selection follows the same principle: the researcher should report the measure that meaningfully represents the type of effect estimated by the chosen analysis.
Statistical significance asks whether the data are sufficiently inconsistent with a null model. Effect size asks how large the observed effect is.
Why Effect Size Matters Beyond the P-Value
A p-value does not measure the magnitude of an effect. A study with thousands of participants can detect a very small difference because the estimate is highly precise, while a small study may produce a sizeable estimated difference with considerable uncertainty. Looking only at whether p is below .05 can therefore hide the practical meaning of the result.
Effect-size reporting helps separate magnitude from statistical detectability. Suppose two teaching methods differ by only 0.4 percentage points in average examination score but the sample includes 20,000 students. The difference could be statistically significant while being educationally negligible. An effect-size estimate would make that small magnitude clearer.
The reverse situation is also possible. A pilot study may estimate a substantial improvement but fail to reach statistical significance because the sample is small and the confidence interval is wide. Effect size can help describe the estimated magnitude, although the uncertainty around that estimate must still be acknowledged.
The peer-reviewed effect-size primer by Lakens emphasises that effect sizes should be interpreted in relation to prior research and practical consequences rather than through rigid universal labels. This is especially important for dissertation writing, where interpretation should reflect the substantive context of the study.
What Is Cohen’s d?
Cohen’s d is a standardised mean-difference effect size. It expresses the difference between two means in standard deviation units, allowing researchers to compare group differences even when studies use different measurement scales. In a simple independent-groups design, Cohen’s d is commonly based on the difference between the group means divided by an appropriate pooled standard deviation.
A general representation is:
Cohen’s d = difference between means ÷ standard deviation used for standardisation
Suppose students taught using Method A achieve a mean score of 74, while students taught using Method B achieve a mean score of 68. If the relevant pooled standard deviation is 10, Cohen’s d is approximately 0.60. This means the two group means differ by about six-tenths of a standard deviation.
The sign indicates direction. A negative Cohen’s d does not mean that the effect is statistically worse in some universal sense; it simply reflects the order in which the means were subtracted. Researchers should explain which group scored higher rather than interpreting the sign without context.
How Should Cohen’s d Be Interpreted?
Cohen's commonly cited rules of thumb describe values around 0.20 as small, 0.50 as medium, and 0.80 as large. These thresholds can provide a rough orientation when no better discipline-specific information exists. However, they should not be treated as universal boundaries separating unimportant from important effects.
The Vanderbilt University discussion of effect sizes similarly presents the traditional benchmarks while stressing that previous research and the practical context should guide interpretation. A small standardised effect can be consequential when the outcome involves public health, safety, educational access, or another high-impact result.
| Cohen’s d | Traditional Description | Better Interpretation Approach |
|---|---|---|
| About 0.20 | Small | Compare with effects considered meaningful in the relevant field |
| About 0.50 | Medium | Interpret alongside the outcome scale and previous research |
| About 0.80 | Large | Consider whether the magnitude has meaningful practical consequences |
The table should therefore be treated as a rough descriptive reference rather than a grading system. An effect of d = 0.49 does not suddenly become qualitatively different from d = 0.51. Context, confidence intervals, study quality, previous evidence, and the consequences of the difference remain more important than assigning a verbal category.
Cohen’s d for Independent and Paired Samples Is Not Always the Same
Students should be careful when reporting Cohen’s d because several standardisation approaches exist. For two independent groups, a pooled within-group standard deviation is commonly used. For paired or repeated measurements, researchers may instead standardise the mean difference using the standard deviation of the difference scores or another repeated-measures denominator.
This means that two statistics both labelled Cohen’s d may not be numerically identical if they use different denominators. Paired-sample effect sizes are particularly sensitive to this choice because the relationship between repeated observations affects variability. Students should therefore report which effect-size definition was used rather than assuming that "Cohen’s d" refers to one universal calculation.
When an assignment uses a t-test, Epic Essay's guide to t-tests and ANOVA provides the broader analytical context for choosing the correct comparison procedure. The effect-size calculation should then correspond with the actual t-test design.
Do not report Cohen’s d without knowing how it was standardised. Independent-groups and repeated-measures designs can require different denominators and therefore different interpretations.
What Is Eta Squared?
Eta squared, written as η², is an effect-size measure commonly associated with ANOVA. It describes the proportion of total variation in the dependent variable that is associated with a particular effect under the relevant ANOVA decomposition. Its value ranges from 0 to 1 because it is expressed as a proportion.
A general representation is:
η² = SS effect ÷ SS total
If η² = .12, the factor is associated with 12% of the total observed variance in the dependent variable within the analysed model structure. This provides substantially more information about magnitude than the ANOVA p-value alone. A significant F test establishes evidence of group differences, whereas eta squared helps quantify how much variation is associated with the factor.
Eta squared is especially intuitive in a one-way ANOVA because there is one principal grouping factor being compared with residual variation. More complicated factorial and repeated-measures designs require greater care because several effects, interactions, and error components may contribute to the overall variance.
What Is Partial Eta Squared?
Partial eta squared, written as ηp², is another ANOVA effect-size measure and is commonly produced by general linear model procedures in statistical software. Instead of dividing an effect sum of squares by the total sum of squares, partial eta squared divides the effect sum of squares by the effect plus its associated error sum of squares.
The basic formula is:
Partial η² = SS effect ÷ (SS effect + SS error)
The Lakens effect-size guide for t-tests and ANOVAs explains this calculation and shows how partial eta squared can also be derived from an F statistic and its degrees of freedom under appropriate designs. Partial eta squared is particularly common in factorial and repeated-measures ANOVA because it gives an effect-size estimate for a specific factor or interaction relative to its associated error.
Students should not use the terms eta squared and partial eta squared interchangeably. In a simple one-way ANOVA they can coincide under standard formulations, but in factorial designs partial eta squared will generally differ from eta squared because the denominators represent different quantities.
| Feature | Eta Squared | Partial Eta Squared |
|---|---|---|
| Symbol | η² | ηp² |
| General denominator | Total sum of squares | Effect sum of squares plus associated error |
| Interpretation | Proportion of total variance associated with the effect | Proportion of relevant effect-plus-error variance associated with the effect |
| Common use | Often useful in simpler ANOVA contexts | Common in factorial and repeated-measures ANOVA |
| Directly interchangeable? | No | No |
The distinction becomes important when comparing studies. Two papers may report apparently similar values while using different eta-squared measures. Researchers should verify the exact statistic before comparing magnitudes across studies.
How Large Is an Eta-Squared Effect?
Traditional rules of thumb often describe eta-squared values around .01 as small, approximately .06 as medium, and approximately .14 as large. Similar benchmarks are frequently applied to partial eta squared, although interpretation can become problematic because the measures have different denominators and can vary according to the research design.
The University of North Dakota's statistical effect-size resources provide conventional benchmark values for ANOVA effect sizes, including eta squared and Cohen’s f. These thresholds can be useful when students need an initial frame of reference, but they should not replace substantive knowledge of the research area.
For example, η² = .04 might be labelled small according to a generic benchmark, yet an intervention accounting for 4% of variation in a high-impact health or educational outcome could be meaningful. Conversely, an effect that appears numerically large may have limited practical importance if the dependent measure itself is not substantively important.
| Eta-Squared Value | Traditional Label | Interpretive Caution |
|---|---|---|
| About .01 | Small | Can still matter when outcomes are important or interventions are inexpensive |
| About .06 | Medium | Should be compared with typical effects in the field |
| About .14 | Large | Does not automatically establish practical or causal importance |
Students should therefore resist writing statements such as "η² = .14 proves a large and important effect." A better interpretation explains the proportion of variance represented and evaluates whether that magnitude is meaningful in the substantive context.
Cohen’s d vs Eta Squared: Which Effect Size Should You Use?
Cohen’s d and eta squared answer related but different questions. Cohen’s d is particularly suited to expressing the standardised difference between two means. Eta squared is suited to quantifying the proportion of variance associated with an ANOVA factor. The correct choice follows naturally from the statistical analysis and research design.
If a dissertation compares average stress levels between two independent groups using a t-test, Cohen’s d may provide an intuitive standardised difference. If the study compares stress across four intervention conditions using a one-way ANOVA, eta squared may be more natural because the analysis concerns an overall group factor rather than one pairwise contrast.
Post-hoc comparisons after ANOVA can introduce additional effect sizes. The overall ANOVA might report eta squared, while specific pairwise comparisons can be accompanied by standardised mean differences where appropriate. Researchers should distinguish the effect size for the overall factor from effect sizes for individual group contrasts.
| Research Situation | Common Effect Size | What It Communicates |
|---|---|---|
| Two independent group means | Cohen’s d | Standardised difference between the two group means |
| Pre-test vs post-test | A paired-sample standardised mean difference | Magnitude of change in standardised units |
| One-way ANOVA | Eta squared | Proportion of total variance associated with the grouping factor |
| Factorial ANOVA | Often partial eta squared | Magnitude of each factor or interaction relative to its associated error |
| Individual ANOVA post-hoc contrast | Often a standardised mean difference | Magnitude of a specific pairwise difference |
The table demonstrates why effect-size reporting should follow the statistical question rather than a preference for one familiar measure. A good results section can contain more than one effect-size statistic when different analyses answer different questions.
Effect Size vs Statistical Significance
Statistical significance and effect size should be interpreted together but should never be treated as synonyms. Statistical significance depends on the estimated effect, its variability, sample size, and the statistical model. Effect size focuses more directly on magnitude, although effect-size estimates themselves also have sampling uncertainty.
Consider a study in which two student groups differ by only one percentage point but the sample contains several thousand observations. The t-test may produce p < .001 because the standard error is very small, yet Cohen’s d may be only .08. The evidence that the population means are not exactly identical may be strong while the standardised difference remains tiny.
A second study could estimate d = .60 but produce p = .08 because only a small number of participants were recruited. The estimated effect is potentially substantial, but its uncertainty may be too large to support a precise conclusion. Reporting the confidence interval around the effect size would make this uncertainty clear.
This interpretation is closely related to Epic Essay's guidance on statistical reporting: SPSS output should be interpreted rather than copied mechanically. The site's SPSS analysis and reporting guide specifically identifies ignoring effect sizes as a common academic reporting mistake.
What Is Practical Significance?
Practical significance asks whether an observed effect is large enough to matter outside the statistical test. The answer depends on the research context. A change of two points can be trivial on one scale and critically important on another, so practical significance cannot be determined from Cohen’s d or eta squared alone.
In education, a modest improvement might be meaningful if an intervention is inexpensive, scalable, and benefits large numbers of students. In clinical research, even a small standardised effect may matter if it reduces severe symptoms or prevents rare but serious outcomes. In organisational research, a small improvement in productivity may have large financial consequences when applied across thousands of employees.
Costs, risks, baseline performance, alternative interventions, stakeholder priorities, and the importance of the outcome all contribute to practical interpretation. An effect-size benchmark cannot evaluate these considerations automatically.
Practical significance is a substantive judgement informed by effect size, confidence intervals, previous research, costs, risks, and the real-world importance of the outcome.
Why Effect-Size Benchmarks Should Not Be Applied Mechanically
The traditional small, medium, and large labels are widely taught because they make unfamiliar statistics easier to interpret. The problem begins when these approximate conventions are transformed into universal scientific rules. Different disciplines operate with very different typical effect sizes, measurement reliability, interventions, and consequences.
Lakens' practical primer notes that Cohen's conventional d values were never intended to replace comparison with prior research or substantive interpretation. An effect such as d = .20 might be unimportant in one setting but extremely valuable in another. The same principle applies to eta squared and partial eta squared.
Researchers should therefore begin with discipline-specific evidence where available. If previous high-quality studies normally report effects around d = .30, an observed effect of d = .45 may be notable even though a generic table would label both within the broad small-to-medium region. Comparison with comparable studies provides a more defensible interpretation than an isolated benchmark.
Do not turn effect-size thresholds into pass-or-fail rules. Values immediately above and below an arbitrary benchmark are not substantively different simply because their verbal labels change.
Why Confidence Intervals Around Effect Sizes Matter
Effect sizes are sample estimates and therefore contain sampling uncertainty. Reporting d = .50 without an interval can make the estimate appear far more precise than it actually is. A 95% confidence interval provides information about the range of population effect sizes compatible with the data and model assumptions.
Suppose a dissertation estimates Cohen’s d = .52 with a 95% confidence interval from .35 to .69. The sample suggests a moderate standardised difference with reasonably useful precision. If the same estimate had an interval from -.10 to 1.14, the central estimate would be identical, but the evidential situation would be dramatically less certain.
The same principle applies to eta-squared estimates. Confidence intervals can help distinguish an apparently sizeable effect that is estimated imprecisely from one that is supported by a relatively narrow range. This is particularly useful in small dissertation samples where point estimates can fluctuate considerably.
Effect-size reporting is therefore strongest when magnitude and uncertainty are presented together. The estimate answers "How large?", while the interval helps answer "How precisely do we know?"
Dissertation Example: Cohen’s d for an Independent t-Test
Consider a hypothetical dissertation comparing examination performance between students taught with a traditional lecture method and those taught through an interactive teaching approach. The interactive group has a mean score of 76.0 with a standard deviation of 9.5, while the traditional group has a mean score of 69.5 with a standard deviation of 10.2.
The mean difference is 6.5 points. If the pooled standard deviation is approximately 9.86, Cohen’s d is approximately 0.66. The group means therefore differ by about two-thirds of a pooled standard deviation.
A weak write-up would state only that the groups differed significantly, p < .05. A stronger report would include the descriptive statistics, inferential test, confidence interval, and effect size. The discussion could then compare d = .66 with effects found in previous teaching-intervention research and consider whether a 6.5-point improvement is educationally meaningful.
The effect size does not prove that the teaching method caused the difference unless the research design supports causal inference. It quantifies the observed difference; the study design determines what interpretation can be placed on that difference.
Dissertation Example: Eta Squared for a One-Way ANOVA
Now consider a dissertation comparing student engagement scores across four teaching formats. A one-way ANOVA produces a statistically significant overall difference, F(3, 196) = 6.80, p < .001. Statistical significance indicates that the population group means are not all adequately represented by an identical-mean model under the ANOVA assumptions.
Suppose η² = .094. Approximately 9.4% of the observed total variance in engagement scores is associated with teaching format in the analysed sample and model. This provides a clearer sense of magnitude than the p-value alone.
A results statement might report: "Student engagement differed significantly across teaching formats, F(3, 196) = 6.80, p < .001, η² = .094." Post-hoc comparisons would then be needed to identify which groups differ from one another if that question is relevant.
The discussion should not convert η² = .094 automatically into a causal claim that teaching format "explains 9.4% of engagement" in every population. The statistic describes the analysed data and model, while causal and generalisable conclusions depend on sampling, design, measurement, and other methodological considerations.
Effect Size in SPSS: What Should Students Look For?
SPSS output varies by procedure and software version. Some analyses provide effect-size estimates directly, while others may require the researcher to request them or calculate them from descriptive statistics, sums of squares, test statistics, or specialised procedures. Students should therefore know which effect size their test requires before searching the output.
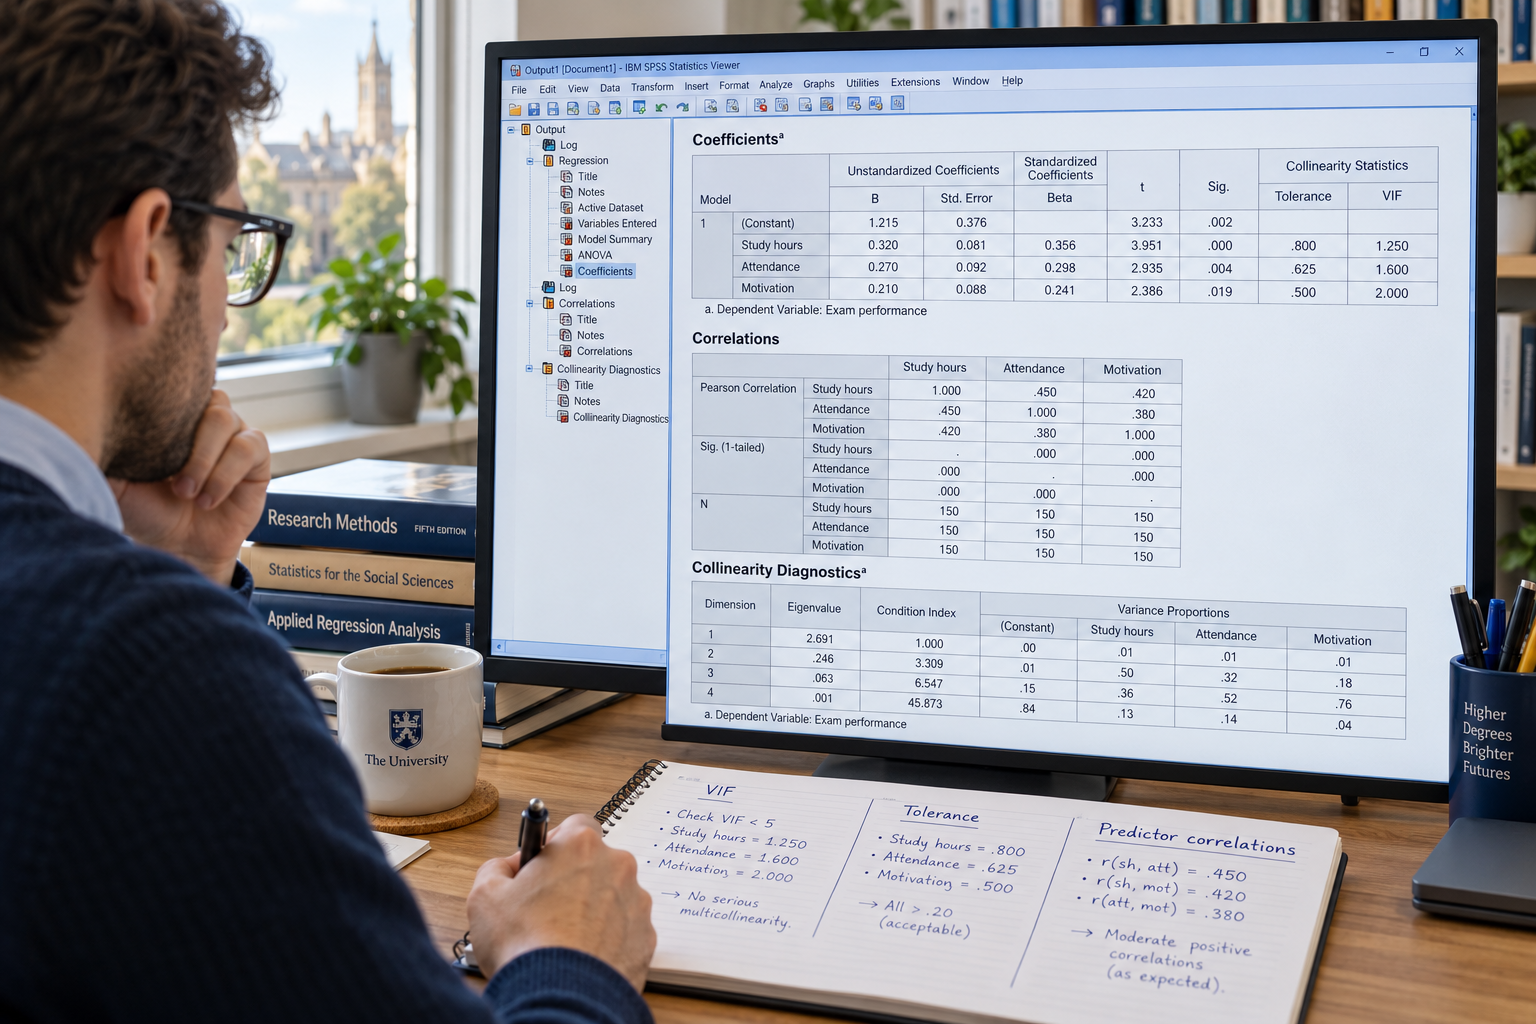
In ANOVA procedures, SPSS general linear model output commonly reports partial eta squared when effect-size statistics are requested. Students should check the table heading carefully because reporting a partial eta-squared value as ordinary eta squared changes the meaning of the statistic.
For t-tests, researchers may need to obtain or calculate an appropriate standardised mean difference depending on the SPSS version and procedure used. The denominator should match the design, particularly for paired data. Copying a value from an online calculator without understanding the underlying formula can create inconsistencies.
A strong SPSS assignment therefore identifies the statistical test, checks assumptions, reports statistical significance, and interprets the relevant effect size rather than presenting output tables without explanation.
Effect Size, Statistical Power, and Sample Size
Effect size also plays a central role in statistical power analysis. Before collecting data, researchers may specify the smallest effect that is theoretically or practically important and estimate the sample size required to detect such an effect with acceptable statistical power. This is more defensible than choosing a sample size without reference to the intended analysis.
Expected effect sizes can come from previous research, pilot studies, meta-analyses, or a clearly justified smallest effect of interest. Generic Cohen benchmarks can sometimes be used when no better evidence exists, but this should be acknowledged as a limitation rather than treated as empirical knowledge about the topic.
After the study, the observed effect size should not be interpreted as though it were the exact population effect. Sample estimates fluctuate, particularly in small studies. Confidence intervals remain essential for understanding how uncertain the magnitude may be.
Effect size therefore connects study planning with result interpretation. It informs how much data may be needed before a study begins and helps explain how substantial the observed findings are after the analysis is completed.
Common Effect-Size Mistakes Students Should Avoid
One common mistake is reporting only the p-value. Saying that a difference is "significant" tells the reader little about whether the effect is negligible or substantial. Where the statistical method supports an interpretable effect-size measure, reporting it improves the analytical value of the results.
A second mistake is using the wrong effect size for the design. Cohen’s d calculated for two independent groups should not automatically be reused for paired observations, and eta squared should not be confused with partial eta squared. The measure and calculation need to match the analysis.
Another error is applying benchmark labels mechanically. Writing "d = .79 is medium but d = .80 is large" creates an artificial distinction unsupported by substantive reasoning. Effect-size interpretation should remain continuous and contextual.
Students also sometimes equate a large effect size with statistical significance or certainty. A large sample effect can be estimated very imprecisely, and a small effect can be estimated with considerable precision. Magnitude and uncertainty are separate dimensions of the result.
How to Report Effect Size in a Dissertation
A good dissertation results section reports the effect size alongside the inferential statistics it complements. For a t-test, this may include group means, standard deviations, t, degrees of freedom, p, confidence interval, and Cohen’s d. For ANOVA, it may include F, degrees of freedom, p, eta squared or partial eta squared, and relevant post-hoc results.
A hypothetical t-test sentence could read: "Students receiving the interactive teaching method achieved higher scores than those receiving traditional instruction, t(98) = 3.29, p = .001, Cohen’s d = 0.66." If an appropriate confidence interval for d is available, adding it would improve the report further.
A hypothetical ANOVA sentence could state: "Teaching format was significantly associated with engagement scores, F(3, 196) = 6.80, p < .001, η² = .094." The discussion can then interpret whether the magnitude is meaningful within the education literature rather than relying entirely on a generic label.
The goal is concise but complete statistical communication. Readers should be able to identify the direction, magnitude, uncertainty, and statistical evidence without having to interpret raw SPSS output themselves.
A Practical Checklist for Interpreting Effect Size
Before describing an effect as small, medium, large, meaningful, or unimportant, students should work through a structured interpretation. This helps prevent effect-size reporting from becoming another mechanical numerical exercise.
- Identify the statistical test and research design.
- Select an effect-size measure appropriate to that design.
- Confirm exactly how the effect size was calculated.
- Check whether the sign indicates direction or only reflects subtraction order.
- Report the effect estimate with the main test statistics.
- Use a confidence interval for the effect size where available.
- Treat generic benchmarks as rough reference points rather than fixed rules.
- Compare the effect with similar studies in the relevant literature.
- Consider the original measurement scale as well as the standardised statistic.
- Ask whether the observed magnitude has practical, clinical, educational, or organisational consequences.
- Consider costs, risks, feasibility, and alternative interventions where relevant.
- Do not infer causality from effect size alone.
- Do not interpret a large effect as automatically precise.
- Distinguish eta squared from partial eta squared explicitly.
- Connect effect-size interpretation directly to the dissertation research question.
This sequence moves the analysis from numerical description to substantive interpretation. Effect-size statistics become most valuable when they help explain the research finding rather than simply adding another number to the results chapter.
Using Cohen’s d and Eta Squared to Interpret Practical Significance
Effect size provides the information that statistical significance alone cannot supply: an estimate of how large the observed phenomenon is. Cohen’s d expresses mean differences in standard deviation units, while eta squared and partial eta squared quantify variance associated with ANOVA effects using different denominators. These measures help researchers move beyond the limited question of whether p falls below a conventional significance threshold.
The strongest interpretation combines magnitude with uncertainty and substantive context. Traditional benchmarks for Cohen’s d and eta squared can provide an initial reference point, but they should not replace comparison with previous research, the original measurement scale, practical consequences, or confidence intervals. A numerically small effect can matter greatly, while a statistically impressive result can have little practical value.
For dissertation research, report the effect-size measure appropriate to the statistical design, name it precisely, explain what it represents, and evaluate its practical meaning rather than merely assigning a label. When effect size, confidence intervals, statistical significance, and disciplinary context are interpreted together, the results provide a much more complete account of what the research has actually found.
Comments