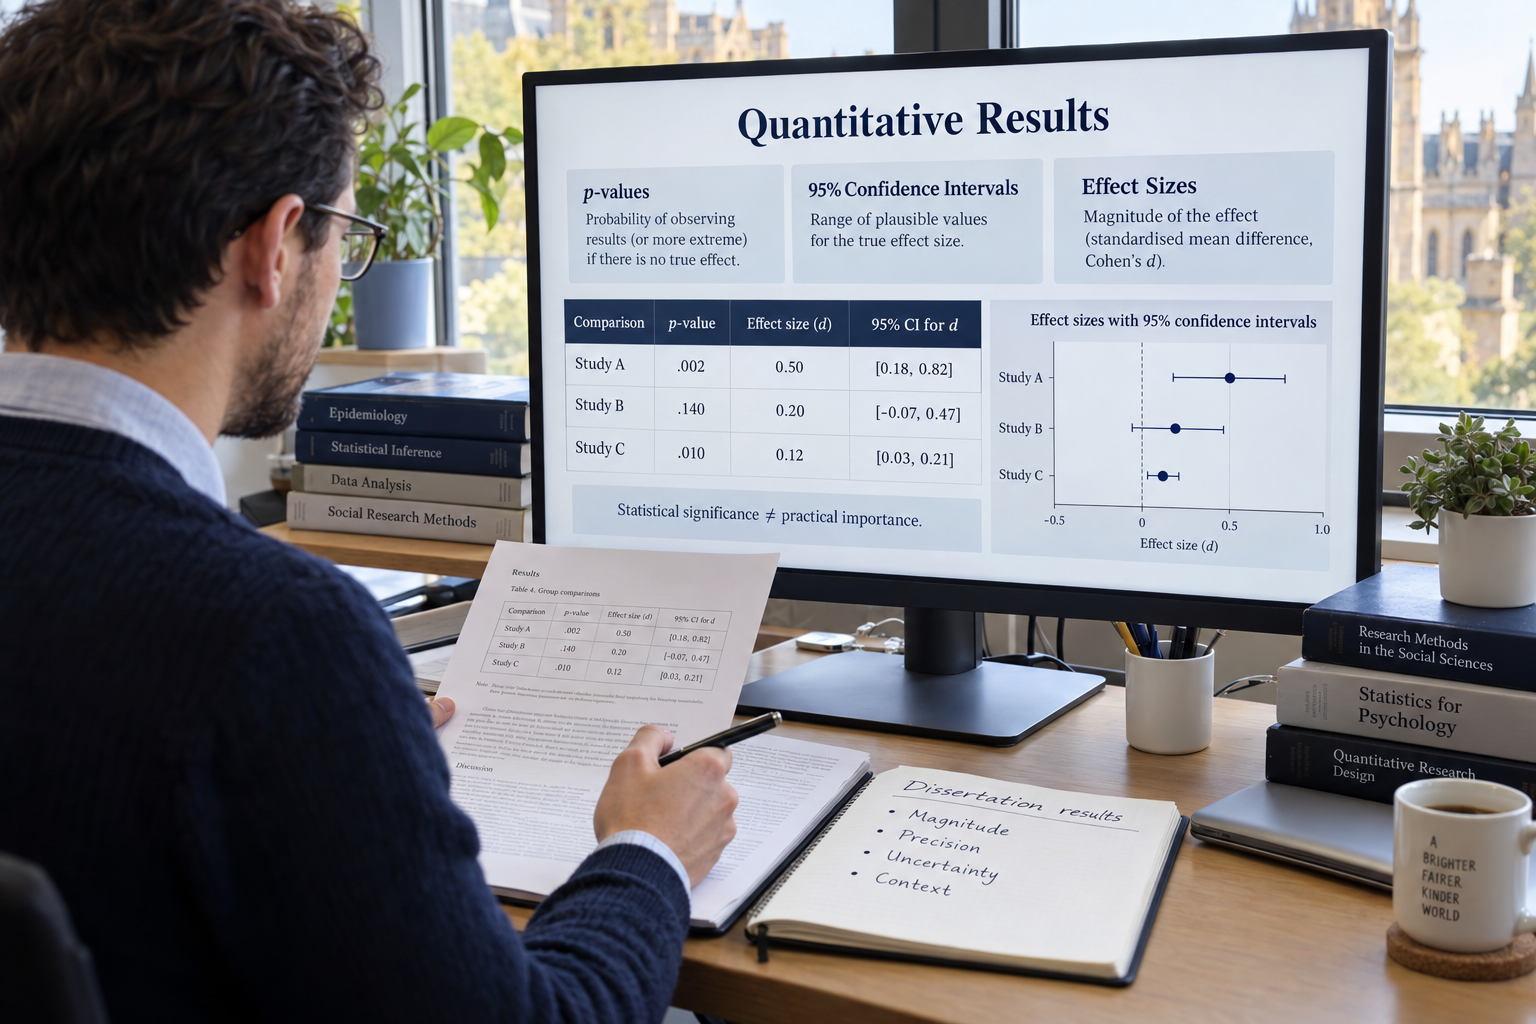
Statistical significance appears throughout quantitative university research, from t-tests and ANOVA to correlation, regression, and experimental analysis. Students are often taught to look first for whether p is below .05, but that habit can reduce a complex statistical result to a simple significant-versus-not-significant label. A result can have a very small p-value yet represent a trivial effect, while a non-significant result can remain too imprecise to rule out an academically or practically important effect.
Understanding p-value vs confidence interval interpretation therefore requires recognising that the two statistics provide different information. A p-value evaluates the compatibility of observed data with a specified null hypothesis and statistical model. A confidence interval focuses on estimation by showing a range of parameter values compatible with the data and analytical assumptions, thereby revealing both the estimated magnitude and its precision.
For dissertation writing, the strongest interpretation normally considers the effect estimate, confidence interval, p-value, study design, assumptions, and substantive context together. This guide explains what each statistic means, how they are connected, why p < .05 should not be treated as a universal definition of importance, and how to report quantitative findings without making conclusions the analysis cannot support.
What Does a P-Value Actually Mean?
A p-value is calculated under a statistical model that includes a null hypothesis. In simplified terms, it describes how unusual the observed result, or a result at least as extreme according to the chosen test statistic, would be if the null hypothesis and other model assumptions were correct. Smaller p-values indicate greater incompatibility between the observed data and that specified null model.
The American Statistical Association's statement on p-values and statistical significance emphasises that a p-value does not tell researchers the probability that the null hypothesis is true. It also does not measure the probability that the findings occurred purely "by chance." These interpretations reverse the conditional logic of the statistical test.
For example, suppose an independent samples t-test produces p = .03 when testing a null hypothesis of no difference between two population means. The correct interpretation is not that there is a 3% probability that the null hypothesis is true. Instead, the result indicates that the observed data are relatively incompatible with the specified zero-difference model under the assumptions of the test.
A p-value is calculated assuming a statistical model and null hypothesis. It is not the probability that the null hypothesis itself is true.
What Does a Confidence Interval Tell You?
A confidence interval provides an interval estimate for a population parameter such as a mean difference, regression coefficient, proportion, correlation, or risk ratio. Rather than reporting only one sample estimate, it shows the uncertainty surrounding that estimate. A narrow interval generally indicates greater precision, whereas a wide interval indicates substantial uncertainty about the population effect.
For example, suppose a study estimates that an intervention increases test scores by 4.2 points, with a 95% confidence interval from 1.3 to 7.1 points. The point estimate is 4.2, but the interval shows that population effects reasonably compatible with the model and data extend across a wider range. This provides considerably more information than knowing only that p is below .05.
The frequentist interpretation of a confidence interval also requires care. The NIST guidance on confidence limits explains that a calculated 95% interval should not be interpreted as meaning there is a 95% probability that the fixed population parameter lies inside that particular realised interval. The 95% refers to the long-run coverage of the interval-producing procedure under repeated sampling and the stated assumptions.
In student-friendly language, it is conventional to report that "we are 95% confident that the population parameter lies between the lower and upper limits." The important academic point is that the interval communicates plausible effect magnitudes and estimation precision rather than assigning a posterior probability to the parameter.
P-Value vs Confidence Interval: What Is the Main Difference?
The most important difference is that a p-value is primarily connected to hypothesis testing, whereas a confidence interval is primarily connected to estimation. A hypothesis test asks how compatible the observed evidence is with a specified null value. A confidence interval shows the effect estimate together with a range representing uncertainty around that estimate.
This distinction matters because researchers usually care about more than whether an effect differs statistically from zero. They also need to know how large the effect might be and how precisely it has been estimated. Confidence intervals make those questions visible in a way that a standalone p-value cannot.
| Feature | P-Value | Confidence Interval |
|---|---|---|
| Main purpose | Assess compatibility with a specified null model | Estimate a population parameter with uncertainty |
| Main output | A probability value between 0 and 1 | A lower and upper limit around an estimate |
| Shows effect magnitude directly? | No | Yes, through the point estimate and interval limits |
| Shows precision directly? | No | Yes |
| Can determine practical importance alone? | No | No, but it provides information needed to assess plausible effect sizes |
| Common misuse | Treating p < .05 as proof of an important or real effect | Treating a 95% interval as having a 95% probability of containing the fixed parameter |
The two approaches are complementary rather than competing. A strong dissertation can report both, using the p-value to describe the result of the hypothesis test and the confidence interval to communicate the estimated effect and its uncertainty.
How Are P-Values and Confidence Intervals Connected?
Under common statistical procedures, confidence intervals and two-sided hypothesis tests are mathematically connected. If a 95% confidence interval for a parameter excludes the null value, the corresponding two-sided test will generally produce p < .05 when both calculations use the same statistical model, assumptions, and standard-error method. If the interval includes the null value, the corresponding p-value will generally be at least .05.
The relevant null value depends on the statistic being analysed. For a mean difference, regression coefficient, or many other additive effects, the null value is usually zero. For ratio measures such as risk ratios or odds ratios, the null value is usually one because a ratio of one represents no relative difference.
| Effect Type | Typical Null Value | Example 95% CI | General Interpretation |
|---|---|---|---|
| Mean difference | 0 | [1.20, 4.80] | Excludes 0; corresponding two-sided test is generally p < .05 |
| Regression coefficient | 0 | [-0.90, 2.40] | Includes 0; corresponding two-sided test is generally p ≥ .05 |
| Risk ratio | 1 | [1.15, 1.72] | Excludes 1; corresponding two-sided test is generally p < .05 |
| Odds ratio | 1 | [0.74, 1.31] | Includes 1; corresponding two-sided test is generally p ≥ .05 |
This relationship explains why confidence intervals can often communicate the essential significance result without reducing interpretation to a threshold. The interval also provides additional information about the range of effect magnitudes compatible with the data.
Why Does p < .05 Mean Statistically Significant?
The .05 threshold is a conventional significance level rather than a natural boundary separating truth from falsehood. When researchers set alpha at .05 before analysis, they establish a decision rule for a particular hypothesis-testing procedure. A p-value below that threshold is conventionally labelled statistically significant, while a value above it is conventionally labelled non-significant.
The danger arises when the threshold is treated as a sharp scientific divide. Results of p = .049 and p = .051 are extremely similar statistically, yet a mechanical approach might label one a discovery and the other a failure. The American Statistical Association explicitly warns against basing scientific conclusions solely on whether a p-value crosses a specific threshold.
Epic Essay's guide to choosing statistical tests similarly emphasises that quantitative analysis involves understanding research questions, assumptions, and interpretation rather than merely running software procedures. Statistical significance is one component of that reasoning, not a substitute for it.
Do not treat p = .049 as conclusive evidence and p = .051 as evidence that nothing happened. Interpret the estimate, uncertainty, design, assumptions, and research context together.
Statistical Significance vs Practical Significance
Statistical significance addresses evidence relative to a null model; practical significance concerns whether the estimated effect is large enough to matter in the real research context. These are fundamentally different questions. A result can be statistically significant while being too small to have meaningful educational, clinical, organisational, or economic consequences.
Large samples make this distinction particularly important because very small effects can sometimes be estimated with enough precision to produce extremely small p-values. Suppose a study of 50,000 students finds that a new learning tool raises average examination marks by 0.15 points on a 100-point scale, with p < .001. The statistical evidence against an exact zero effect may be strong, but the substantive importance of a 0.15-point difference requires separate evaluation.
The reverse can also occur. A small pilot study may estimate an educationally meaningful improvement but produce p = .08 because the confidence interval is wide. The appropriate conclusion is not automatically that the intervention has "no effect." Instead, the study may simply be too imprecise to distinguish a meaningful positive effect from a small or null effect.
Epic Essay's regression interpretation guide makes the same distinction for regression coefficients: statistical significance does not automatically establish that an estimated relationship is large or practically important.
How Sample Size Affects P-Values and Confidence Intervals
Sample size influences statistical precision because larger well-designed samples generally reduce the standard error of an estimate. Smaller standard errors tend to produce narrower confidence intervals and can also make hypothesis tests more sensitive to small departures from the null value. Consequently, the same underlying effect can generate very different p-values in studies of different sizes.
Imagine two studies that both estimate an average difference of 2 points. A small study may produce a 95% confidence interval of [-1.5, 5.5], leaving substantial uncertainty and including zero. A much larger study could estimate the same 2-point difference with an interval of [1.6, 2.4], indicating far greater precision and producing a much smaller p-value.
This does not mean large studies are problematic. Greater precision is desirable. The problem occurs when a tiny p-value in a large study is interpreted as evidence that the effect itself must be large. Effect magnitude must be read from the estimate and its scale, not inferred from the p-value.
Similarly, a large p-value in a very small study can reflect inadequate information rather than compelling evidence of no meaningful effect. Confidence intervals make this uncertainty much easier to identify.
Why a Non-Significant Result Does Not Prove No Effect
One of the most common statistical writing errors is stating that "there was no difference" simply because p exceeded .05. Failure to reject a null hypothesis does not establish that the null hypothesis is true. A non-significant result can arise because the true effect is small, because variability is high, because the sample is limited, or because the estimate is simply too imprecise to discriminate among several possibilities.
Suppose a treatment produces an estimated mean improvement of 3.0 points with a 95% confidence interval from -1.0 to 7.0 and p = .14. Zero lies inside the interval, so the result is not conventionally significant at the .05 level. However, the same interval also includes improvements of 5, 6, or 7 points, which might be practically important in the relevant field.
The defensible conclusion is that the study did not provide sufficiently precise evidence to establish a non-zero effect under the specified test. It would be inaccurate to claim that the treatment was proven ineffective. Researchers should examine whether the confidence interval rules out effects that would actually matter.
"Not statistically significant" and "no effect" are not equivalent conclusions.
Can a Confidence Interval Support Evidence of Little or No Important Effect?
A confidence interval can sometimes provide stronger evidence about the absence of a substantively important effect than a non-significant p-value alone. Suppose researchers define in advance that differences smaller than 5 points are too small to matter practically. If a narrow confidence interval ranges from -1.0 to 1.5, then effects as large as ±5 are not compatible with that interval under the model.
This differs from an interval ranging from -8 to 6. Both intervals include zero and could therefore accompany non-significant conventional tests, but they support very different interpretations. The first is precise and centred near zero; the second is too wide to rule out substantial positive or negative effects.
Formal claims of equivalence or non-inferiority require dedicated statistical procedures and prespecified margins rather than simply observing that p > .05. Nevertheless, examining the confidence interval already encourages more sophisticated reasoning than treating all non-significant findings as identical.
This is why the interval's width and location matter. Researchers should ask not only whether the interval contains the null value but what scientifically or practically important values it also contains or excludes.
How to Interpret P-Values and Confidence Intervals Together
A useful interpretation begins with the estimated effect rather than the p-value. Ask what the sample suggests about the magnitude and direction of the relationship or difference. Then examine the confidence interval to determine how precise that estimate is and which alternative effect sizes remain compatible with the analysis.
The p-value can then be reported as evidence from the specified hypothesis test. This sequence prevents the common mistake of treating significance as the result itself. The actual result is the estimated difference, association, coefficient, ratio, or other parameter together with its uncertainty.
| Pattern | What It Suggests | What You Should Not Claim |
|---|---|---|
| Meaningful estimate, narrow CI excluding null, small p-value | Precise evidence of a non-null effect whose practical size can be evaluated | That the result is automatically causal or universally important |
| Tiny estimate, narrow CI excluding null, very small p-value | Precise evidence that the effect differs from the null but may be practically trivial | That a tiny p-value means a large effect |
| Meaningful estimate, wide CI including null, p > .05 | Substantial uncertainty; meaningful effects may still be compatible with the data | That there is definitely no effect |
| Estimate near null, narrow CI around null, p > .05 | Relatively precise evidence suggesting that large effects may be unlikely | Formal equivalence unless an appropriate equivalence procedure was used |
This approach shifts statistical reporting away from yes-or-no declarations and toward estimation, uncertainty, and context. It also makes dissertation discussions more analytically useful because students can explain both what the evidence suggests and what remains uncertain.
Dissertation Example: Interpreting a Significant Result Correctly
Consider a hypothetical dissertation evaluating whether a study-skills programme improves examination scores. The intervention group scores an average of 4.8 points higher than the comparison group, with a 95% confidence interval from 2.1 to 7.5 points and p = .001.
A weak interpretation would say, "The programme was effective because p < .05." This statement focuses entirely on the threshold and may imply causality without considering the research design. A stronger interpretation reports the estimated 4.8-point difference, notes that the interval excludes zero, and then evaluates whether differences between 2.1 and 7.5 points are educationally meaningful.
If the study was a well-conducted randomised experiment, stronger causal language may be defensible than if it was an observational comparison. Statistical significance does not determine that distinction. Study design determines what kinds of substantive inference can reasonably be made.
The findings chapter should therefore report the numerical result, whereas the discussion evaluates practical importance and explains how the finding relates to theory and previous research. Epic Essay's guide to dissertation findings and discussion explains this distinction between presenting results and interpreting their academic significance.
Dissertation Example: Interpreting a Non-Significant Result Correctly
Now consider a second hypothetical dissertation in which the estimated difference is 3.2 points, the 95% confidence interval is [-2.0, 8.4], and p = .22. The conventional hypothesis test is not statistically significant because the interval contains zero and the p-value exceeds .05.
However, the interval is wide. It includes a small negative effect, no effect, and a potentially meaningful positive effect of more than 8 points. Concluding that "the intervention had no effect" would therefore overstate what the sample can establish.
A stronger interpretation is that the study did not obtain statistically significant evidence of a difference and that the estimate remains imprecise. The confidence interval indicates that the data are compatible with a fairly broad range of population effects. Future research with greater precision may be necessary if the magnitude is substantively important.
This wording communicates uncertainty without disguising the statistical result. It is also more useful than presenting p = .22 alone because readers can see why the non-significant result does not settle the substantive question.
How to Report P-Values Correctly in Academic Writing
Where possible, exact p-values are often more informative than writing only p < .05. For example, p = .032 provides more information than merely saying the result was significant. Extremely small values can be reported using a threshold such as p < .001 when the statistical software rounds beyond that level.
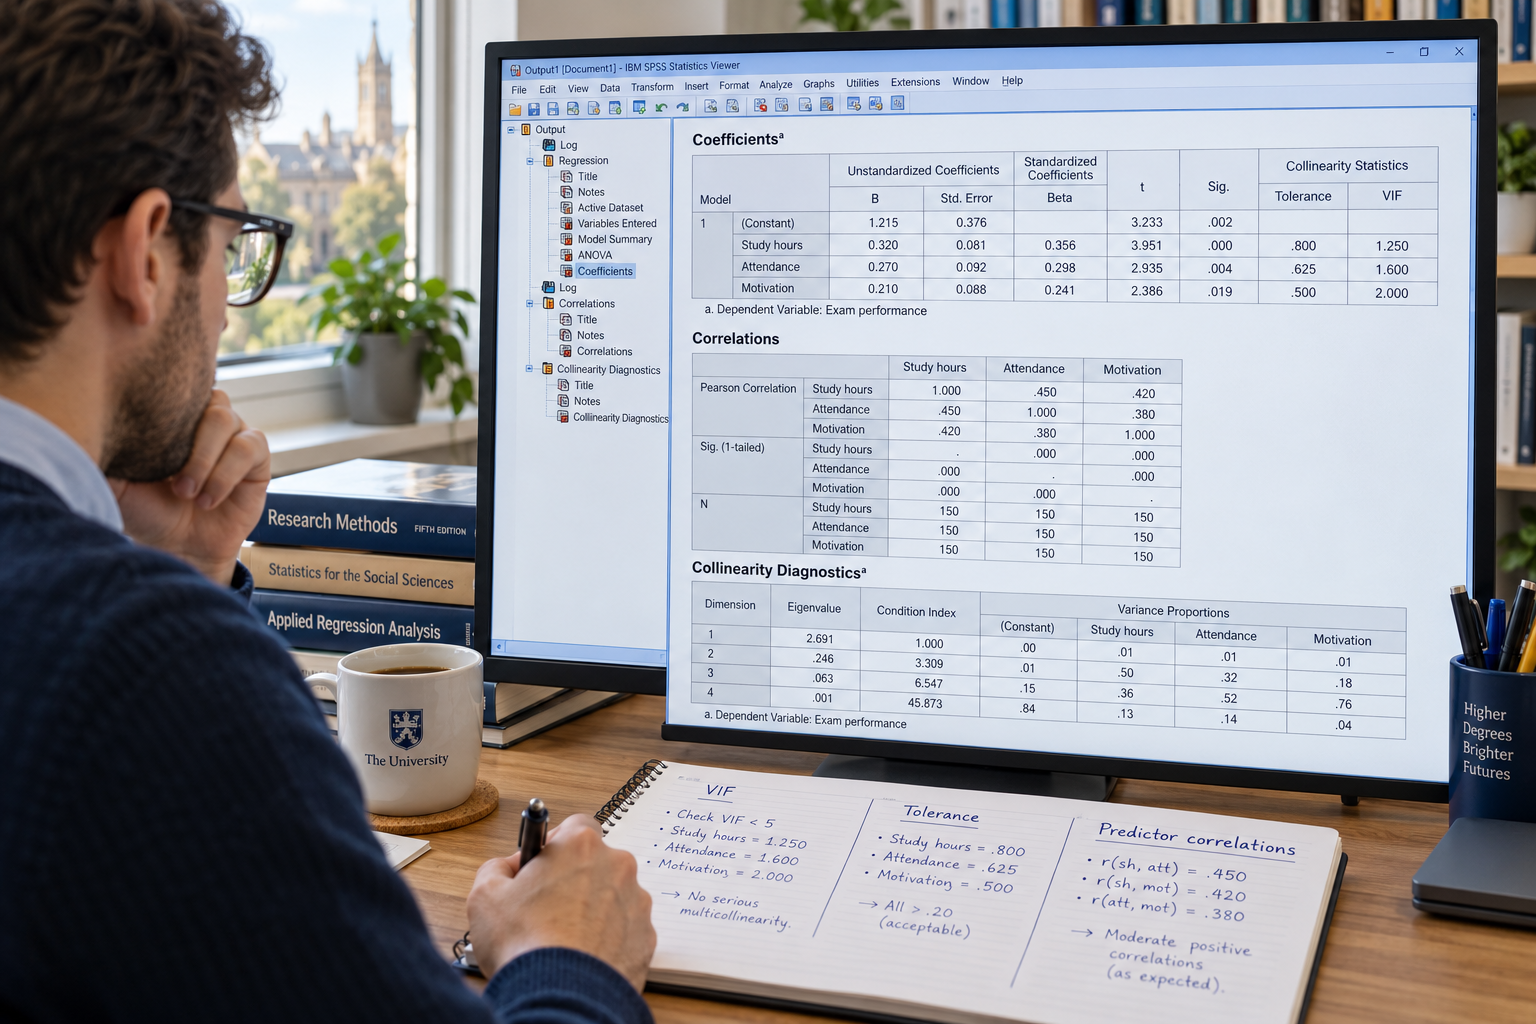
SPSS commonly displays very small significance values as .000. This does not mean the mathematical probability is literally zero. The value has been rounded for display, so academic writing should normally report p < .001 rather than p = .000.
Students should also avoid writing p < .05 when the actual value is p = .047 if their required style or discipline expects exact reporting. Consistent numerical reporting improves transparency and avoids making the .05 threshold appear more important than the result itself.
If SPSS displays .000, do not write p = .000. Report p < .001.
How to Report Confidence Intervals in Dissertation Results
A confidence interval should be linked directly to the parameter being estimated. Writing "95% CI [1.4, 4.7]" without explaining whether this interval refers to a mean difference, regression slope, odds ratio, or another statistic forces readers to reconstruct the analysis themselves. The estimate and interval should normally appear together.
For example, a regression result might be reported as: "Study hours were positively associated with examination score, B = 1.42, 95% CI [0.81, 2.03], p < .001." This gives the direction, estimated magnitude, precision, and hypothesis-test result in one concise sentence.
A group comparison might instead state: "The intervention group scored 4.8 points higher on average than the control group, 95% CI [2.1, 7.5], p = .001." The wording makes the parameter understandable before presenting inferential statistics.
This estimate-first reporting style is more informative than describing a result simply as significant. It also makes it easier for the discussion chapter to evaluate whether the plausible effect sizes are meaningful within the subject area.
Common P-Value and Confidence Interval Interpretation Mistakes
The most common p-value error is claiming that p = .04 means there is a 4% probability that the null hypothesis is true. Conventional significance testing does not calculate that probability. The p-value describes the behaviour of the test statistic under the null model rather than assigning probabilities to competing hypotheses.
A second mistake is assuming that a smaller p-value necessarily represents a larger effect. Sample size, variability, effect magnitude, and the statistical procedure all influence the p-value. Effect magnitude should be evaluated using the estimate itself and an appropriate effect-size measure.
Students also misinterpret confidence intervals by claiming that there is a 95% probability that the population parameter lies within a particular calculated interval. Under the conventional frequentist framework, the parameter is fixed and the interval is the random quantity produced through sampling. The 95% property belongs to the repeated interval procedure.
Finally, researchers sometimes replace p-value worship with confidence-interval worship, treating any interval that barely excludes zero as definitive. Confidence intervals also depend on assumptions, model specification, sampling quality, and analytical decisions. No single numerical output can compensate for weak research design.
What Else Should Be Reported Besides P-Values and Confidence Intervals?
Statistical interpretation should normally include the estimated effect itself and, where appropriate, a standardised effect-size measure. Depending on the analysis, relevant quantities might include Cohen's d, Pearson's r, an unstandardised regression coefficient, odds ratio, risk ratio, eta-squared, or another discipline-appropriate measure.
Descriptive statistics also remain important. Means, standard deviations, frequencies, medians, or other summaries help readers understand the underlying data before inferential statistics are introduced. A p-value without descriptive context can conceal whether the underlying difference is large, small, or based on highly variable observations.
Assumptions and analytical choices should also be documented where relevant. Epic Essay's quantitative thesis research guide places hypothesis testing within the broader research process of defining variables, collecting appropriate numerical data, selecting suitable statistical techniques, and interpreting the findings transparently.
Ultimately, good quantitative reporting integrates estimation, uncertainty, effect magnitude, data quality, and methodological context. Statistical significance is useful, but it should never become the only evidence readers receive.
A Step-by-Step Checklist for Interpreting Statistical Significance
Before writing the dissertation results chapter, students should review the analysis in a consistent sequence. Beginning with the effect estimate rather than immediately searching the SPSS output for an asterisk or p-value reduces threshold-driven interpretation.
- Identify the exact parameter or effect being estimated.
- Report the observed effect in meaningful units where possible.
- Examine the 95% confidence interval and its width.
- Identify the null value relevant to the statistic.
- Check whether the confidence interval includes or excludes that null value.
- Report the exact p-value where appropriate.
- Do not interpret the p-value as the probability that the null hypothesis is true.
- Do not infer effect size from how small the p-value is.
- Ask whether the confidence interval includes practically important effects.
- Distinguish a non-significant result from evidence of no meaningful effect.
- Report an appropriate effect-size measure where required.
- Consider sample size and statistical precision.
- Check whether test and model assumptions were adequately satisfied.
- Interpret causality only when the study design supports causal inference.
- Connect statistical findings to the research question and substantive literature.
This process encourages quantitative reasoning rather than mechanical significance testing. It also produces results sections that are easier for examiners to evaluate because every statistical conclusion can be traced to an estimate, uncertainty measure, and appropriately interpreted test.
Interpreting P-Values and Confidence Intervals with Statistical Confidence
The difference between a p-value and confidence interval becomes clearer when hypothesis testing and estimation are treated as complementary tasks. A p-value describes how incompatible the observed data are with a specified null model, whereas a confidence interval shows the estimated parameter together with a range reflecting uncertainty. Neither statistic should be interpreted without considering the assumptions and research design that produced it.
Statistical significance also does not establish practical importance. A tiny p-value can accompany a trivial effect in a large sample, while a non-significant result with a wide confidence interval may still be compatible with effects that matter. Confidence intervals help expose this distinction by showing both magnitude and precision rather than reducing the result to one threshold.
For a strong dissertation, report the effect estimate first, accompany it with a confidence interval, provide the p-value where relevant, and interpret all three in substantive context. Avoid equating p < .05 with truth, p > .05 with no effect, or statistical significance with real-world importance. When estimates, uncertainty, study design, and practical meaning are considered together, statistical inference becomes far more informative than a simple significant-or-not-significant decision.
Comments